Migrating Airflow DAGs from to Git end to end [Technical Preview]
Deploy Cloudera Migration Assistant, configure Cloudera Data Engineering and Git sources, and migrate DAGs to a Cloudera Workflow Orchestrator Git repository.
This end-to-end workflow combines deployment, platform preparation, discovery, and workload steps. Detailed reference procedures are reused from the Administrator and Migration guides.
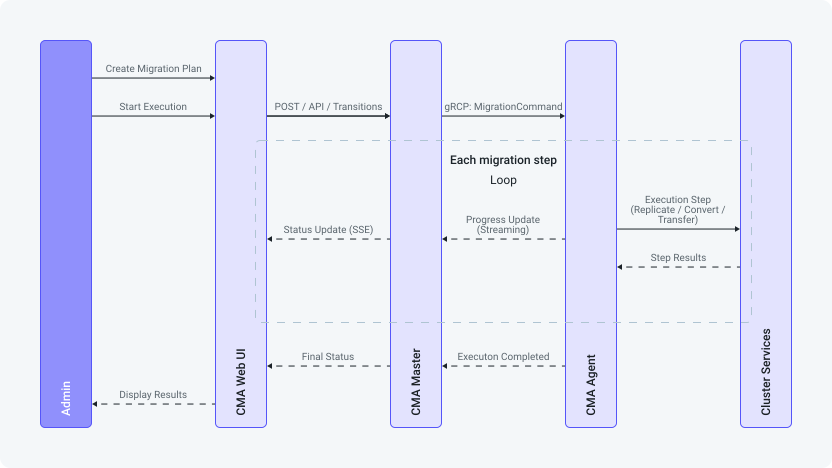
Figure 1. Migration flow
Verify supported platforms and migration paths in Supported platforms and migration paths before you start.
This workflow is technical preview. See Setting up to Cloudera Workflow Orchestrator Git migration.
Phase 1 — Deploy the CMA Master and CMA Agents
Download both CSD files to the
/opt/cloudera/csd/ directory on the
Server host.
Click Save & Verify Configuration to commit the
change.
Click Close.
You are redirected to the Parcels page.
Search for , and click
Download
to download the parcel to the local repository.
After download completes, click Distribute to distribute the
parcel to all clusters.
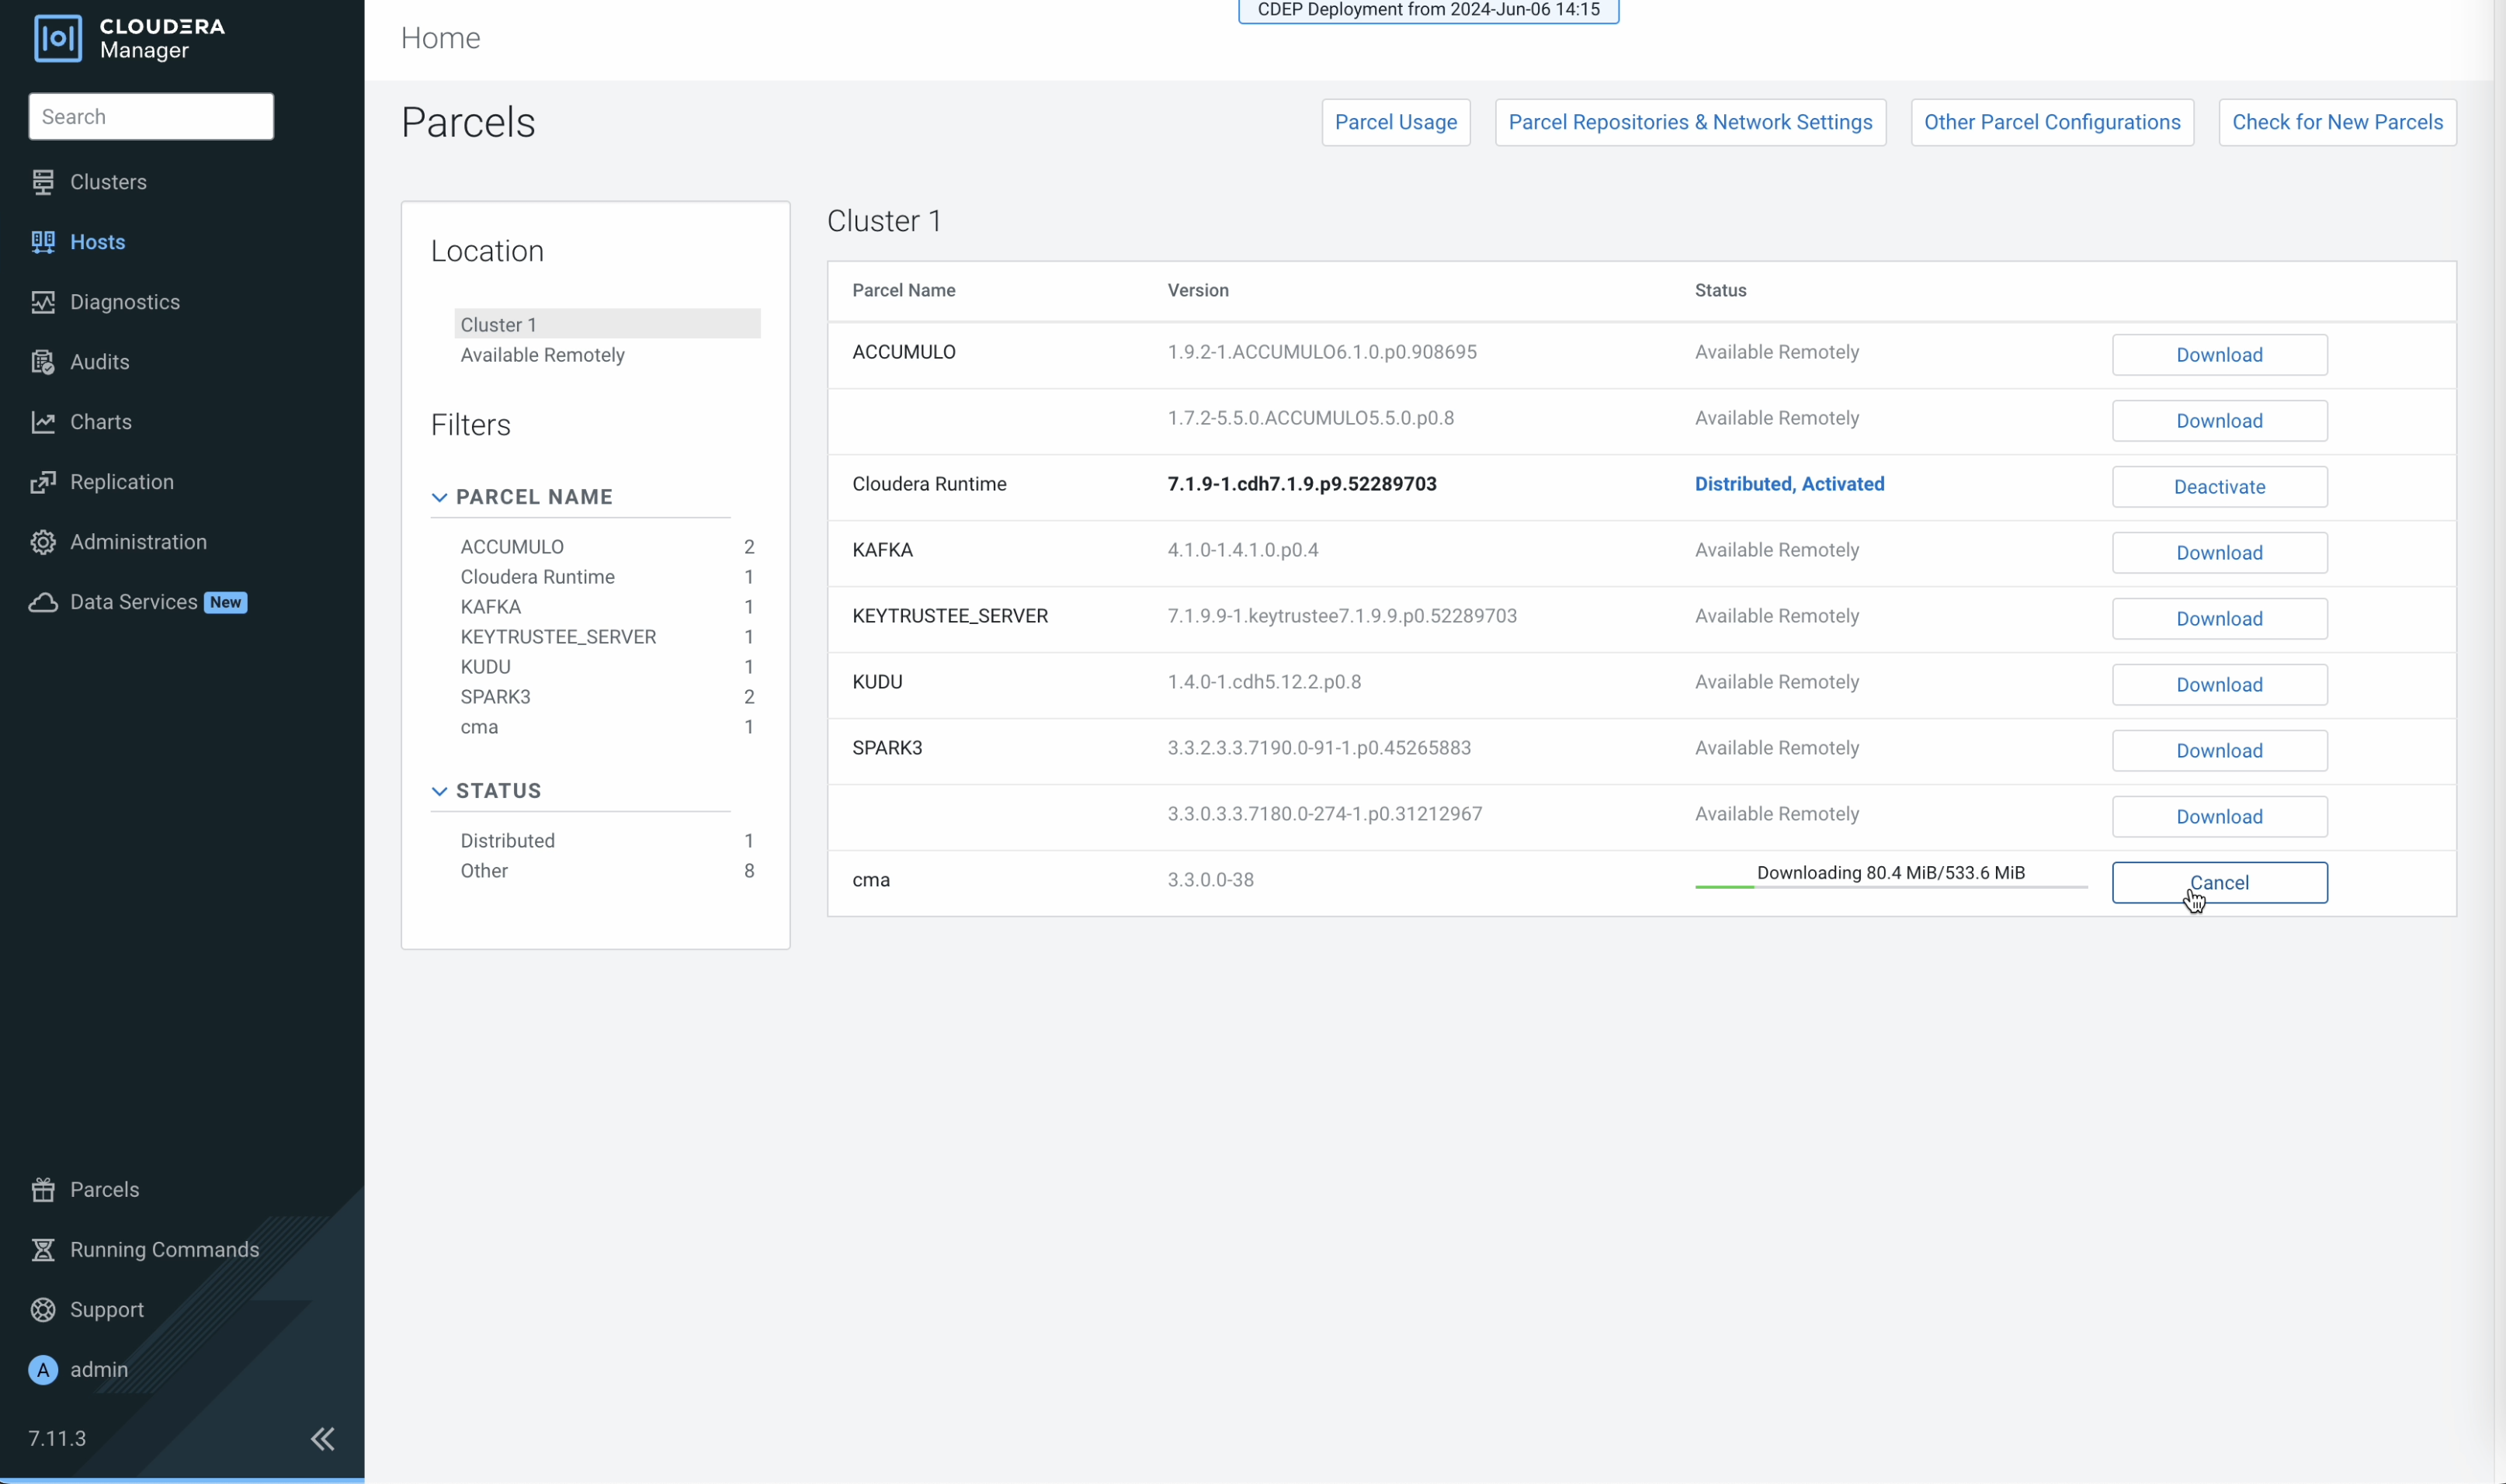
Figure 2. Distribute the parcel
Click
Activate
to activate the parcel.
Click
OK
when confirmation is required.
Click
Clusters
in
the left navigation pane.
Select
Add
Service from the drop-down menu to the right of your
cluster.
From the list, select the service type to add,
then click Continue. The single
parcel provides two service types: CMA_MASTER (central control node) and
CMA_AGENT (cluster-side executor).
The Add Service wizard opens.
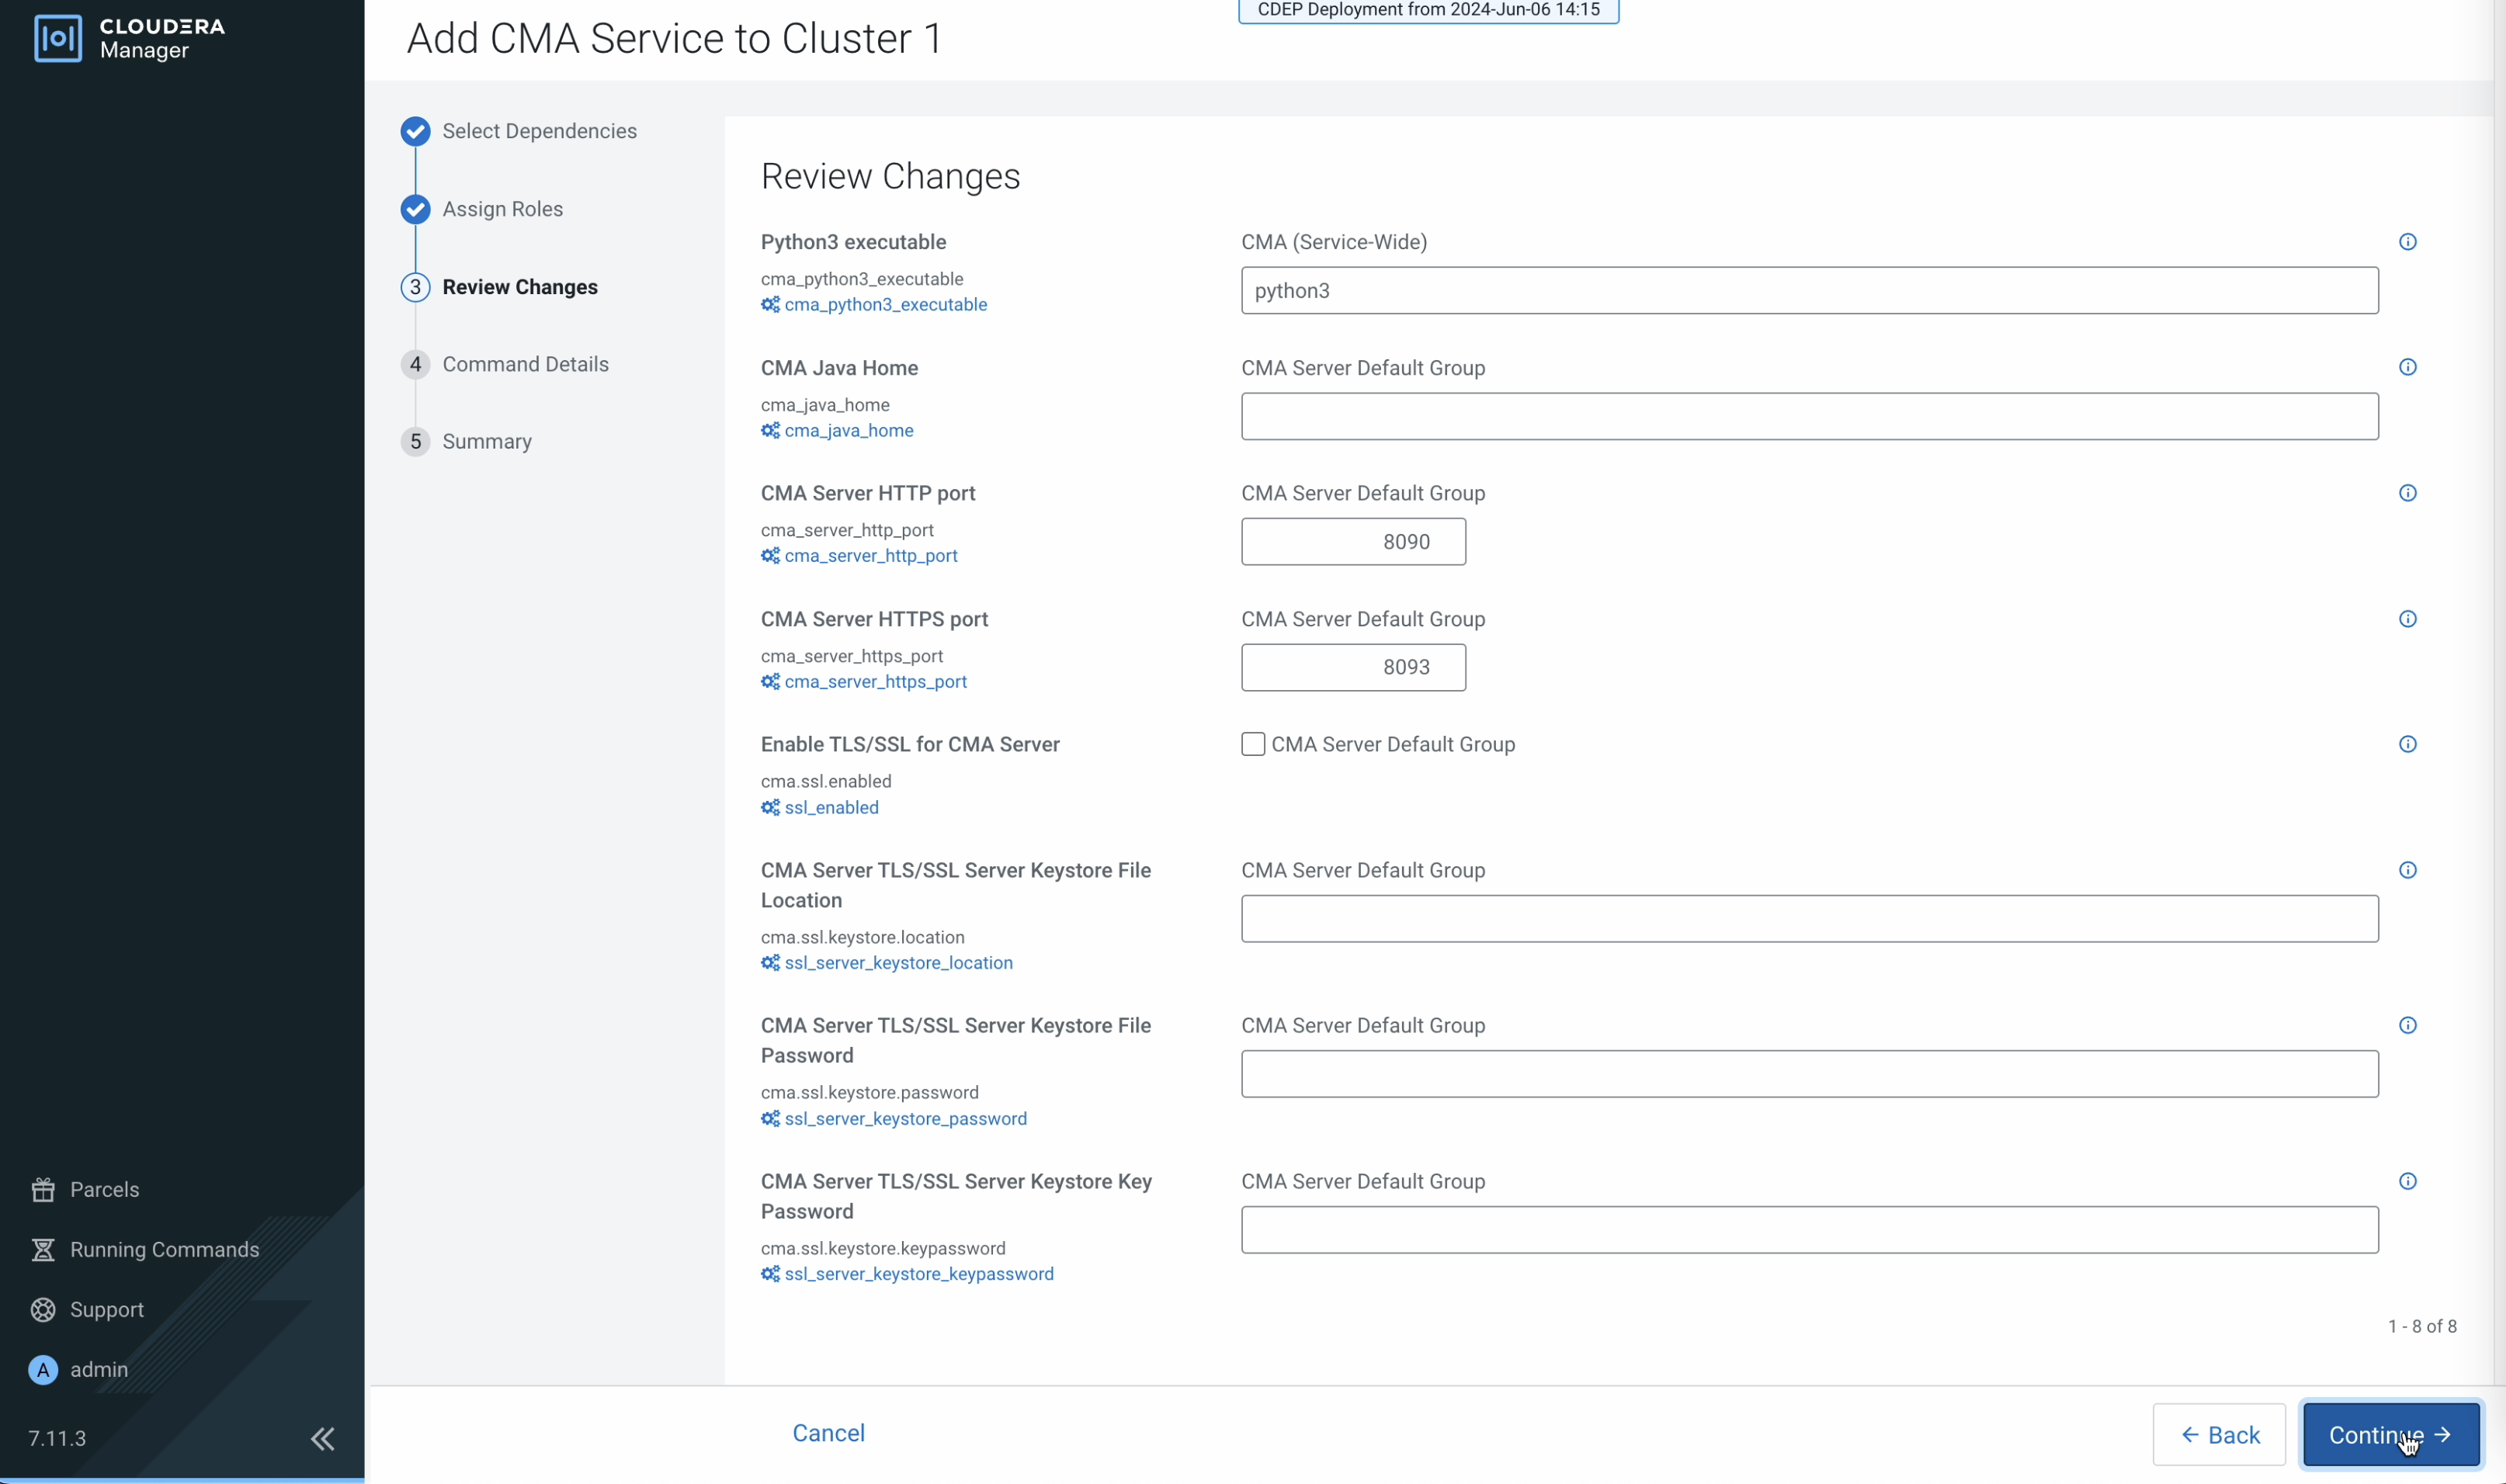
Figure 3. Add service
Assign the service roles to the hosts where Python 3.11 and JDK 17+ are installed, and
click
Continue.
Review service configurations and click Continue. At minimum, set
OAuth2 client credentials (cma_client_secret,
cma_agent_client_secret). If the is on a different cluster from the , also set Gateway URL
(cma_gateway_url).
The first run of the service starts. When the command finishes, the service is added to
the cluster.
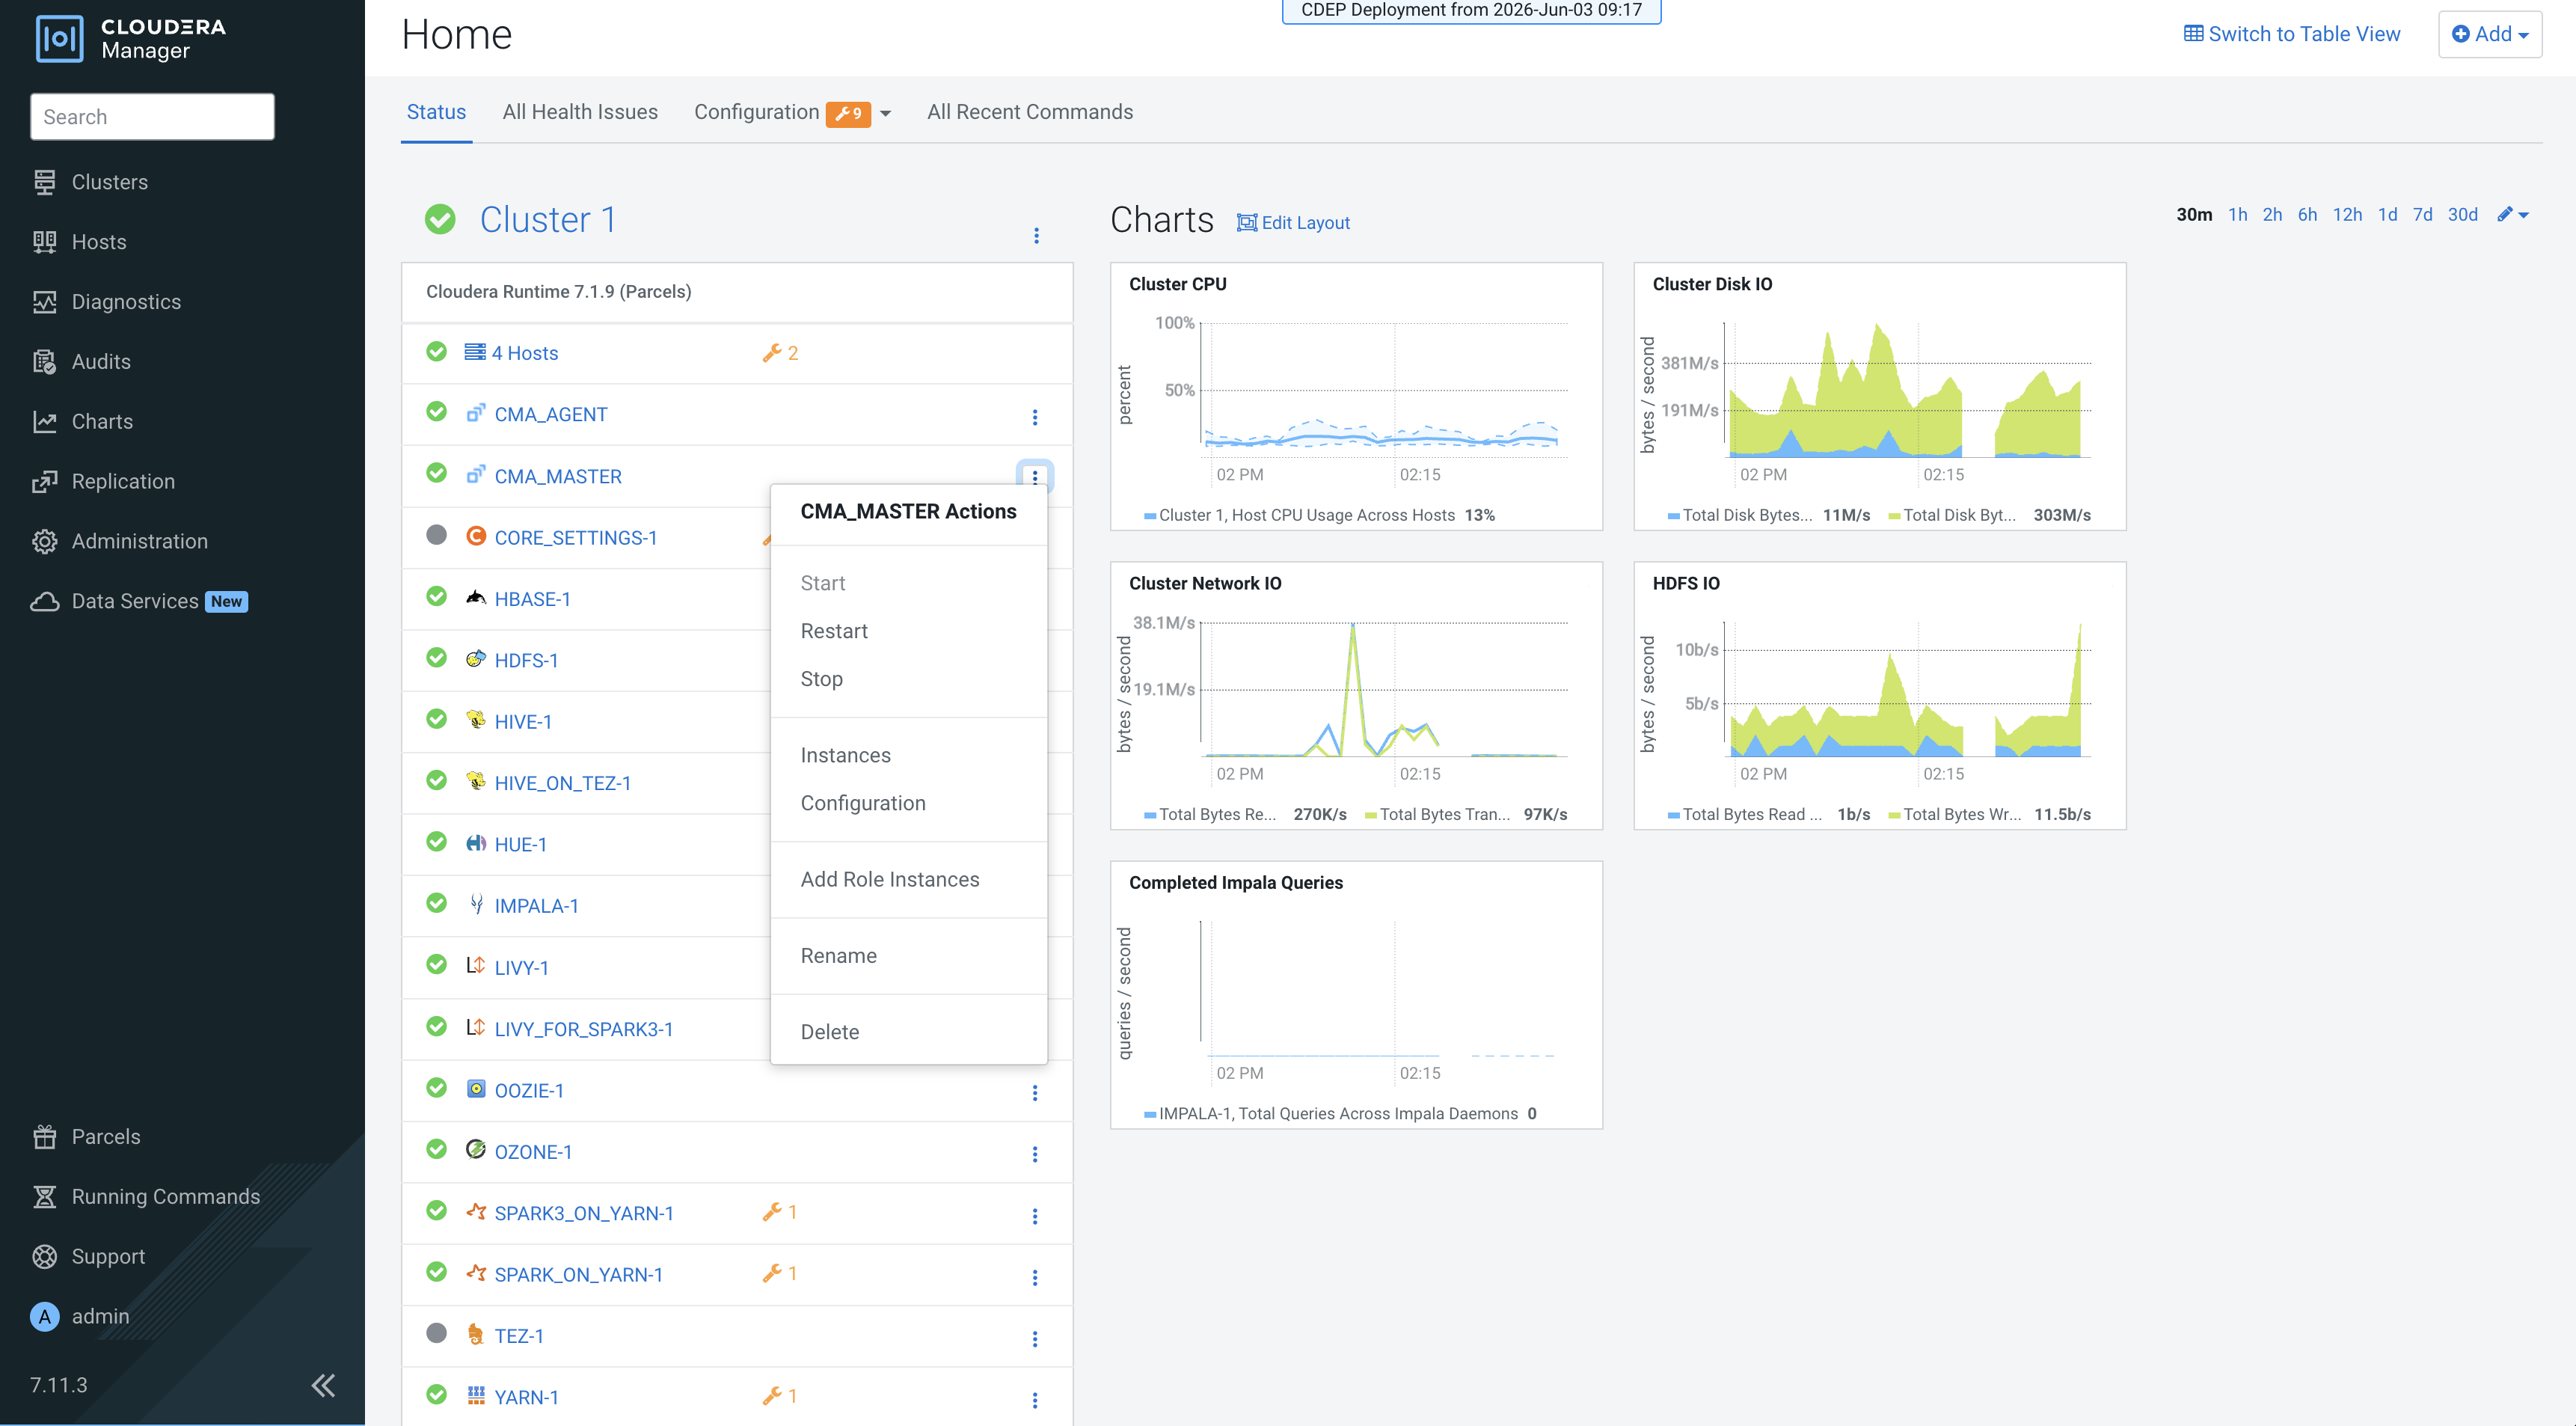
Figure 4. service started
Repeat steps
16–19
to add the other service type if
needed (for example, add
CMA_AGENT after CMA_MASTER, or vice
versa).
Go back to the cluster homepage, open the
service page, and click the Server UI tab to open the UI.
Figure 5. landing page
Set the
service dependency to
none
in the service configuration in Cloudera
Manager
because
Cloudera
Manager
cannot
discover the
Master automatically
across
clusters.
Set the Gateway URL
to
cma_gateway_url
in the service configuration.
Phase 2 — Configure Cloudera Replication Manager on the target cluster
Enable the HDFS to Ozone flag on the Server host.
For HDFS to Ozone migrations, requires the
CMF_FF_API_H2O_REPLICATION feature flag to be enabled. Without this
flag, the API endpoints for HDFS to Ozone replication
are not available.
Append the following line to /etc/default/cloudera-scm-server on
the Server host:
export CMF_FF_API_H2O_REPLICATION=true
Restart the Server.
sudo systemctl restart cloudera-scm-server
Wait for to become available again on port 7180 before proceeding
with the setup.
Register the instance in the UI to allow to locate and communicate with the replication service.
In the Web UI, go to
Settings.
Go to the App Access section.
Configure your connection fields using one of the following validation methods:
If has already detected a service on one of the registered clusters,
select it from the Suggestions drop-down list to
auto-fill the form.
Manually enter your target replication parameters in the following fields:
App URL — The full URL of the REST
API, including protocol, host, and port, for example,
https://rm-host.example.com:9011.
App username — The username for
authenticating with the API.
App password — The password for
authenticating with the API.
Click Save and Push to Agents.
Prepare Cloudera Data Engineering and Git sources (before Phase 2b)
Enable
the cma.cde-git-migration-enabled flag.
In the UI, go to
Settings.
Click the Feature Flags tab.
Locate the cma.cde-git-migration-enabled flag and set it to
true.
Click Save.
Go to the service in .
Click the Configuration tab.
Search for CMA_AGENT_SERVER_role_env_safety_valve.
Add the Cloudera Control Plane and Git repository environment variables listed in
the tables in the next step.
Click Save to save the
advanced
configuration snippet configuration.
Restart the service.
In the UI, go to
Clusters.
Confirm that two new clusters are displayed. If the clusters are not displayed
within a few minutes, check the log for
registration errors.
Configure the advanced configuration
snippet in on the cluster where the is deployed:
and Git credentials are passed to the through the
CMA_AGENT_SERVER_role_env_safety_valve advanced configuration
snippet. These environment variables are read at startup. The agent uses them to
register the and Git clusters.
The Cloudera Control Plane settings allow the to authenticate with the and the Knox
gateway.
Table 1. Cloudera Control Plane environment variables
Variable
Description
Example
CMA_AGENT_CLUSTER_CLOUD_CONTROL_DATACENTER
API endpoint URL.
https://api.us-west-1.cdp.cloudera.com
CMA_AGENT_CLUSTER_CLOUD_CONTROL_ACCESS_KEY_ID
access key ID for Control Plane
authentication. Obtained from the in User Management > Access Keys.
a1b2c3d4-...
CMA_AGENT_CLUSTER_CLOUD_CONTROL_PRIVATE_KEY
private key corresponding to the access
key ID.
<YOUR_CDP_PRIVATE_KEY>
CMA_AGENT_CLUSTER_CLOUD_CONTROL_USERNAME
username. Must be an LDAP user. Used by the to authenticate against the Knox gateway when fetching DAG
metadata.
admin
CMA_AGENT_CLUSTER_CLOUD_CONTROL_PASSWORD
password corresponding to the
username.
<CDE_PASSWORD>
The Git repository settings allow the Git Agent to
scan the target repository and create Pull Requests or Merge Requests.
Table 2. Git repository
environment variables
Variable
Description
Example
CMA_AGENT_CLUSTER_GIT_REPOURL
HTTPS URL of the target Git repository. SSH URLs are not supported.
https://github.com/your-org/your-repo.git
CMA_AGENT_CLUSTER_GIT_TOKEN
Personal access token for the Git repository. For GitHub, the token
requires the repo scope. For GitLab, it requires
api or read_repository +
write_repository.
<YOUR_GIT_PAT>
CMA_AGENT_CLUSTER_GIT_BRANCH
Base branch name. creates a source
branch named cma/<planName> from this branch and opens a
Pull Request or Merge Request back to it. Defaults to main if
not set.
main
Save and restart the .
After the restarts, it registers both
clusters with automatically. No manual
steps are required in the UI.
Verify the cluster registration.
Table 3. Verification values for auto-registered clusters
Cluster Name
Platform Label
Purpose
<clusterName>-cde
Cloudera Data Services
source that is used for scanning
DAGs
<clusterName>-git
Git
Git target that is used for scanning the repository and creating Pull Requests and Merge Requests
Configure user connections
Add per-user Cloudera Data Engineering and Git credentials in the UI. See Managing user connections.
Phase 3 — Register source and target clusters
In on the source cluster, select Add
Service and select
CMA_AGENT.
Configure the required properties.
Table 4. configuration properties
Property
Description
cma_gateway_url
URL of the Gateway,
for
example,
https://master-host:8093.
Required when the is on a different cluster
than
the . The agent uses this URL
to discover the Master host, gRPC port, and Auth Server URI automatically
through
the discovery endpoint (GET /api/agent/config). When connecting
from a different
cluster,
set the service dependency to
none
in .
cm_username
administrator user name.
cm_password
administrator password.
cma_user_home
Home directory for the cma-agent
user,
for
example,
/var/lib/cma-agent.
Set cma_gateway_url when the is on a different cluster than the .
Start the service.
Wait for the agent to connect to the
and finish
the
registration automatically.
Phase 4 — Scan clusters
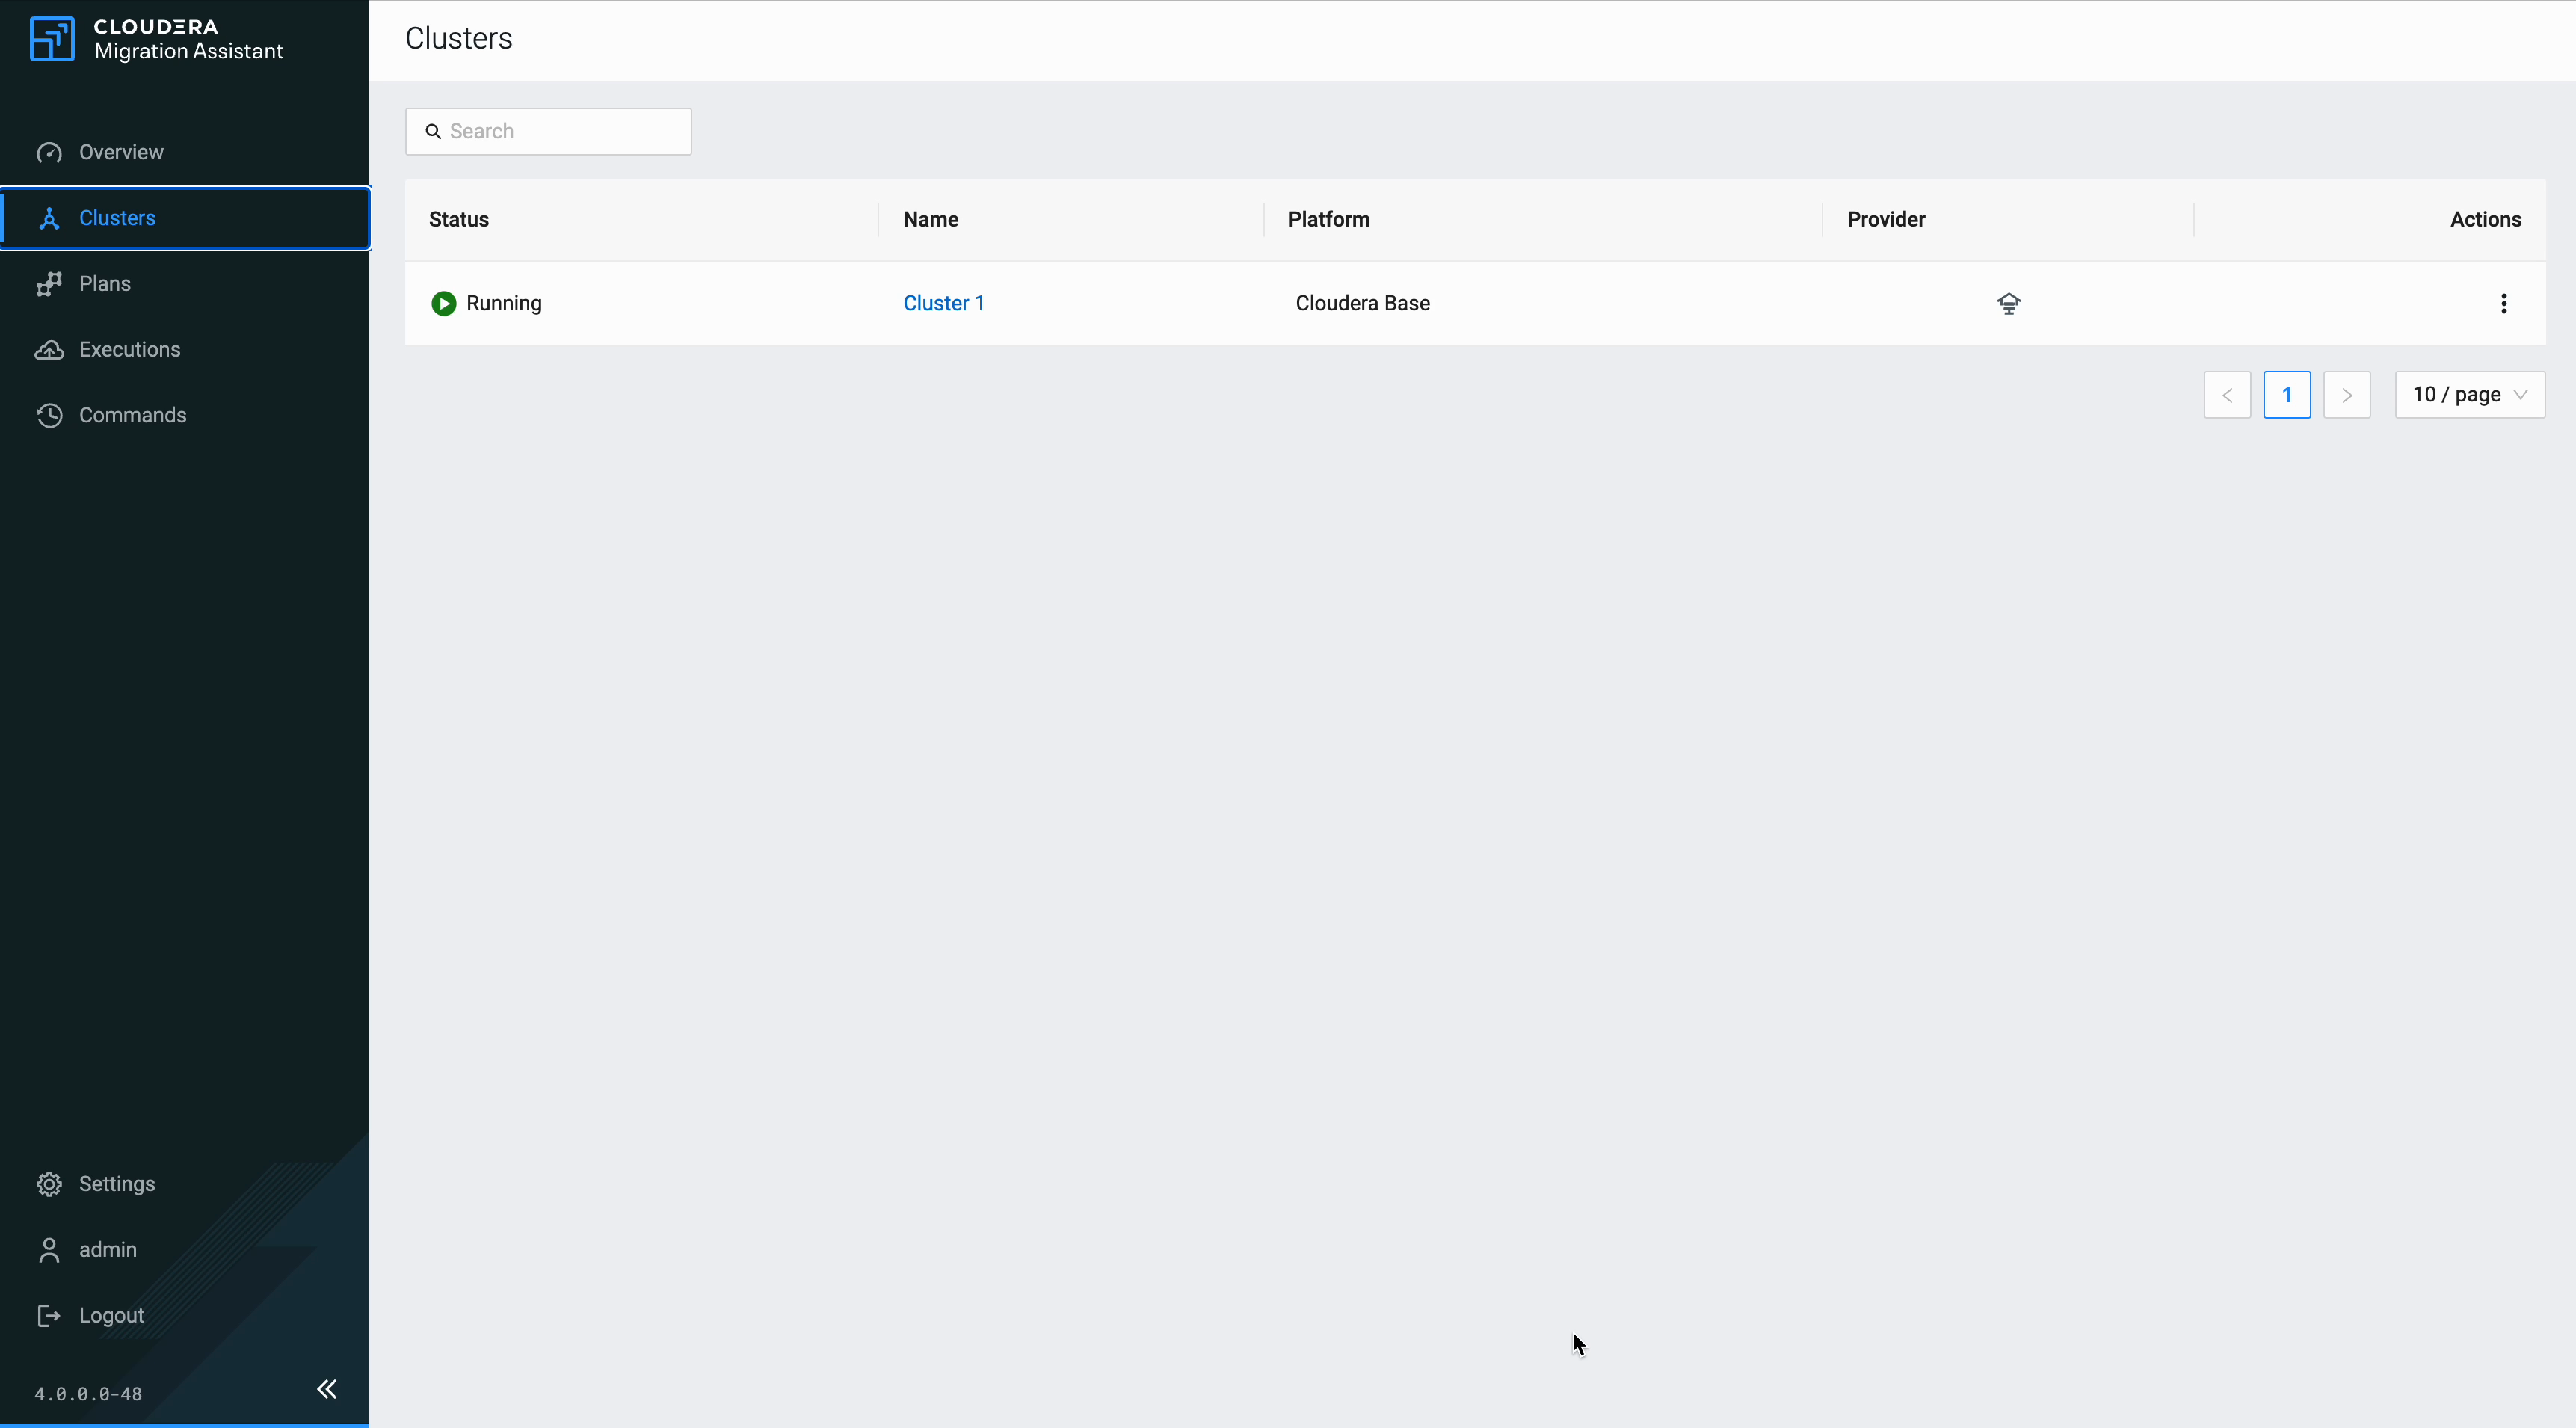
Navigate to the Clusters page and click the cluster you want to scan.
Figure 6. Clusters page
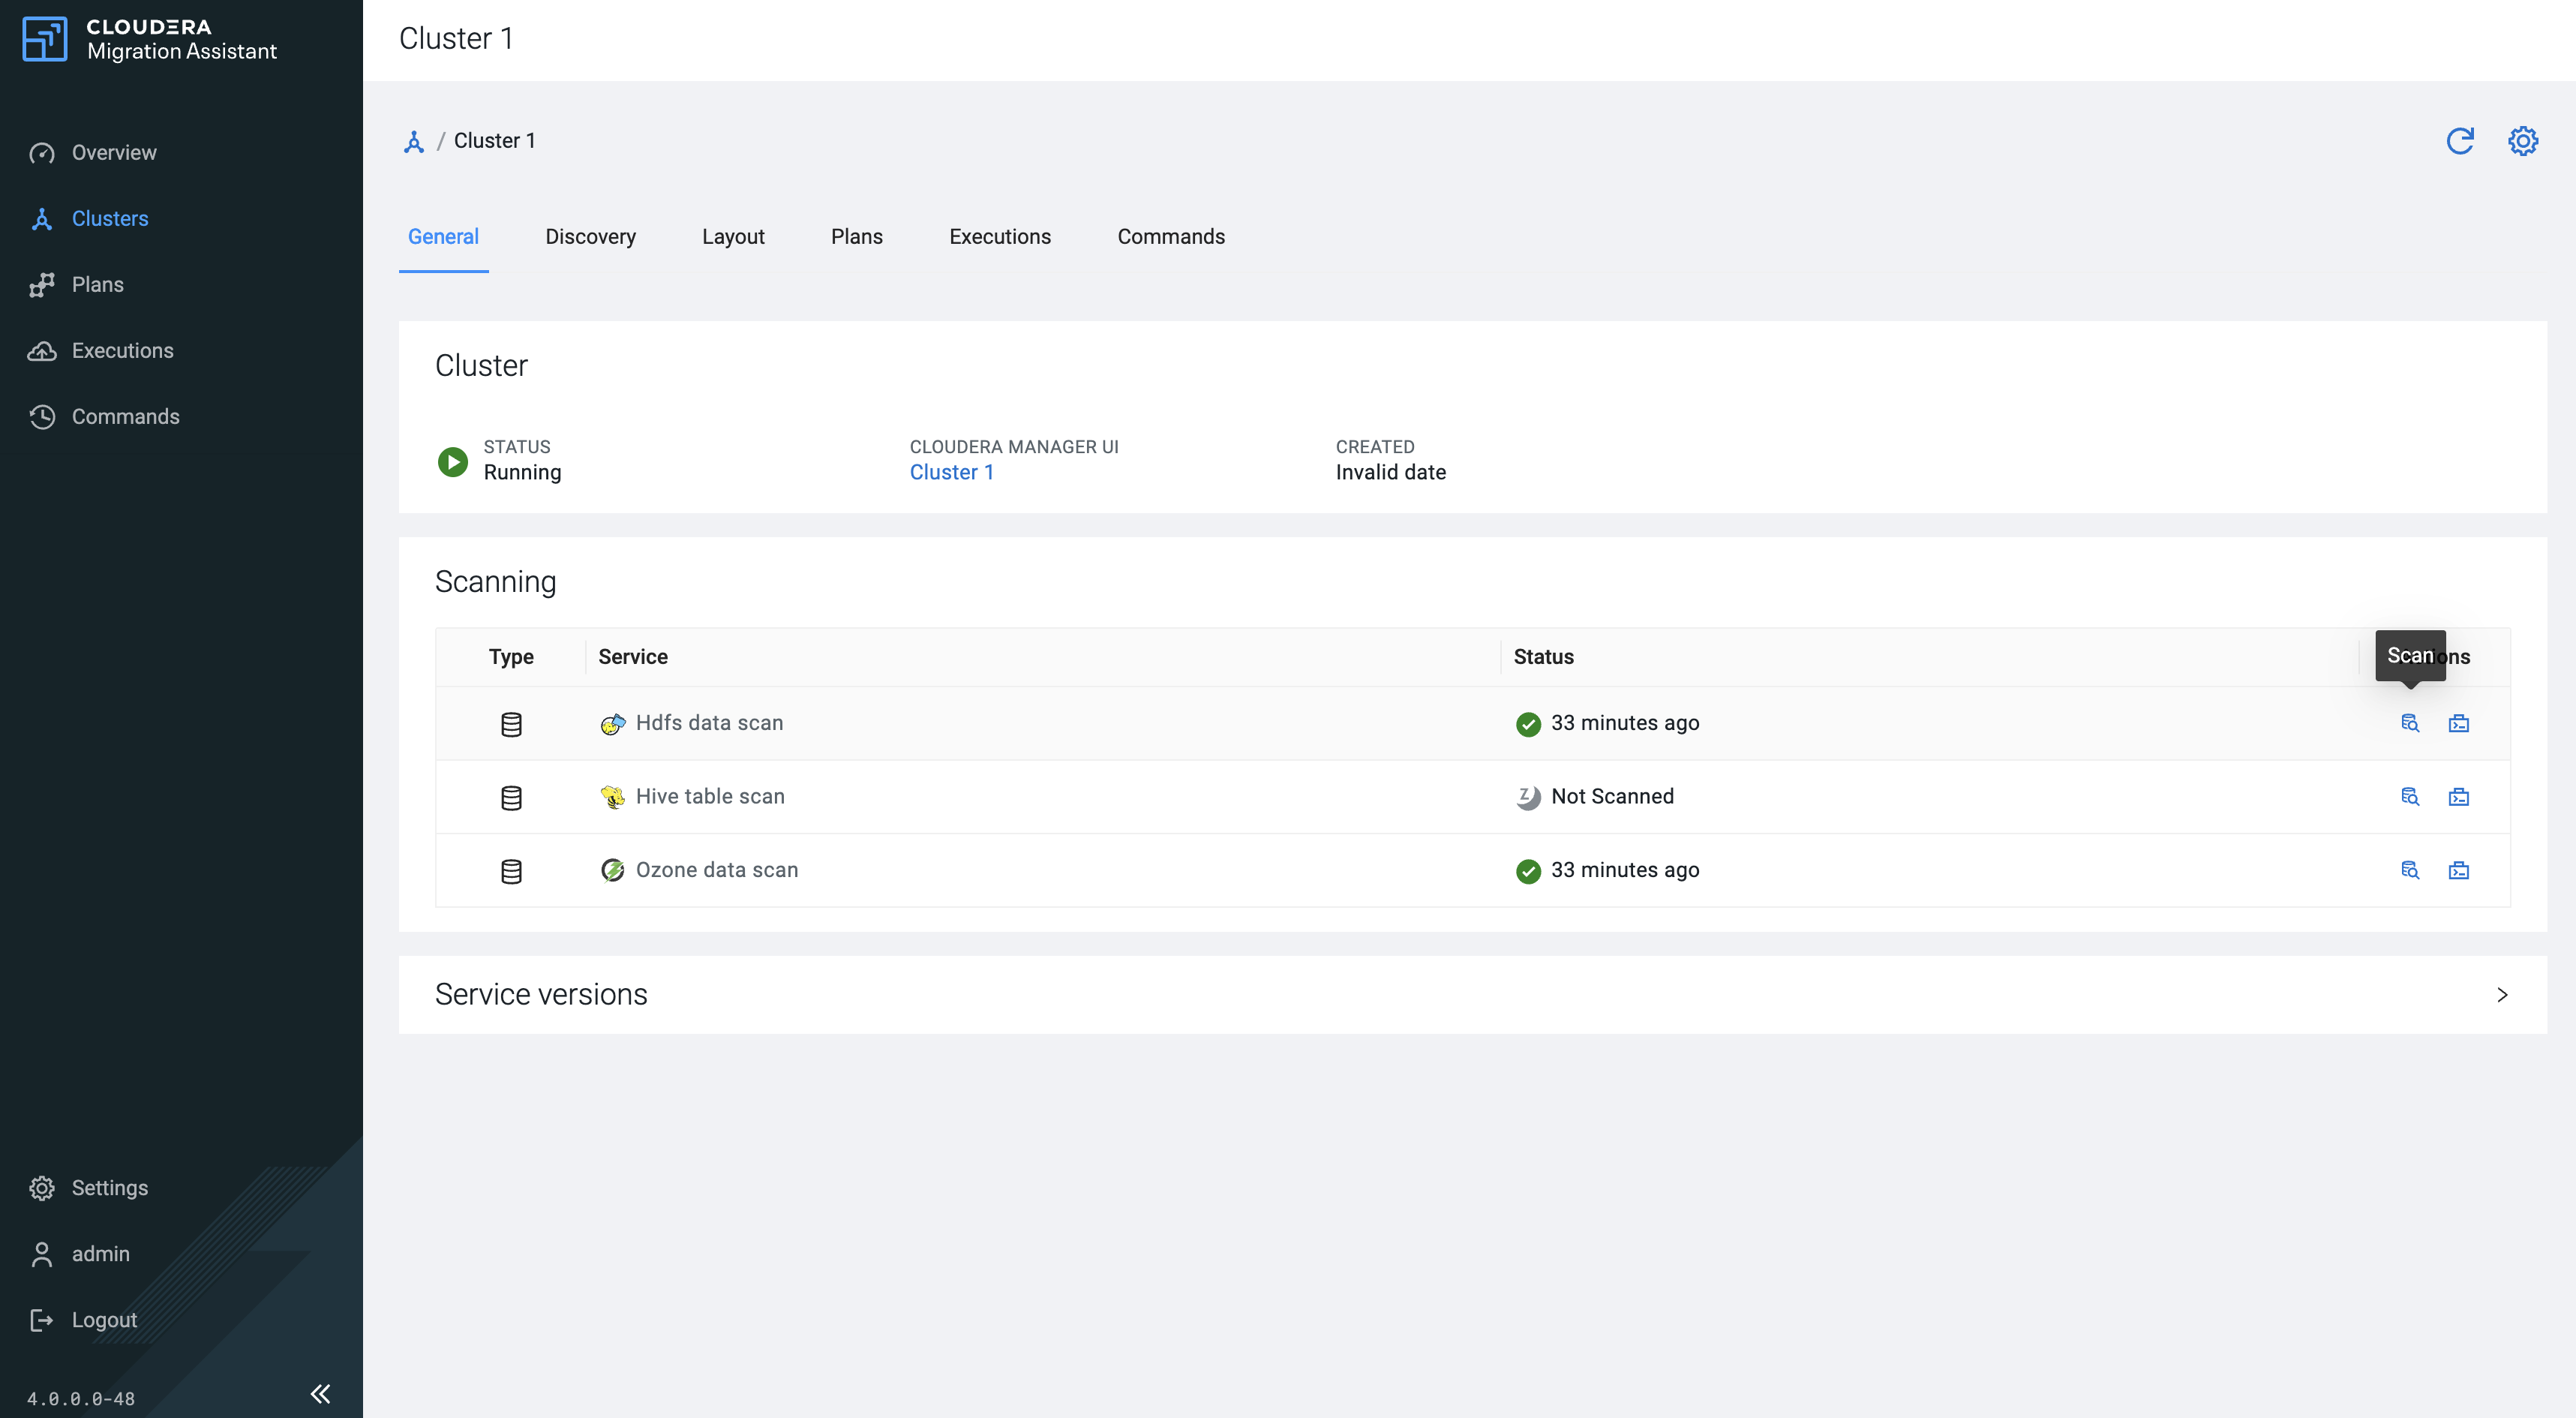
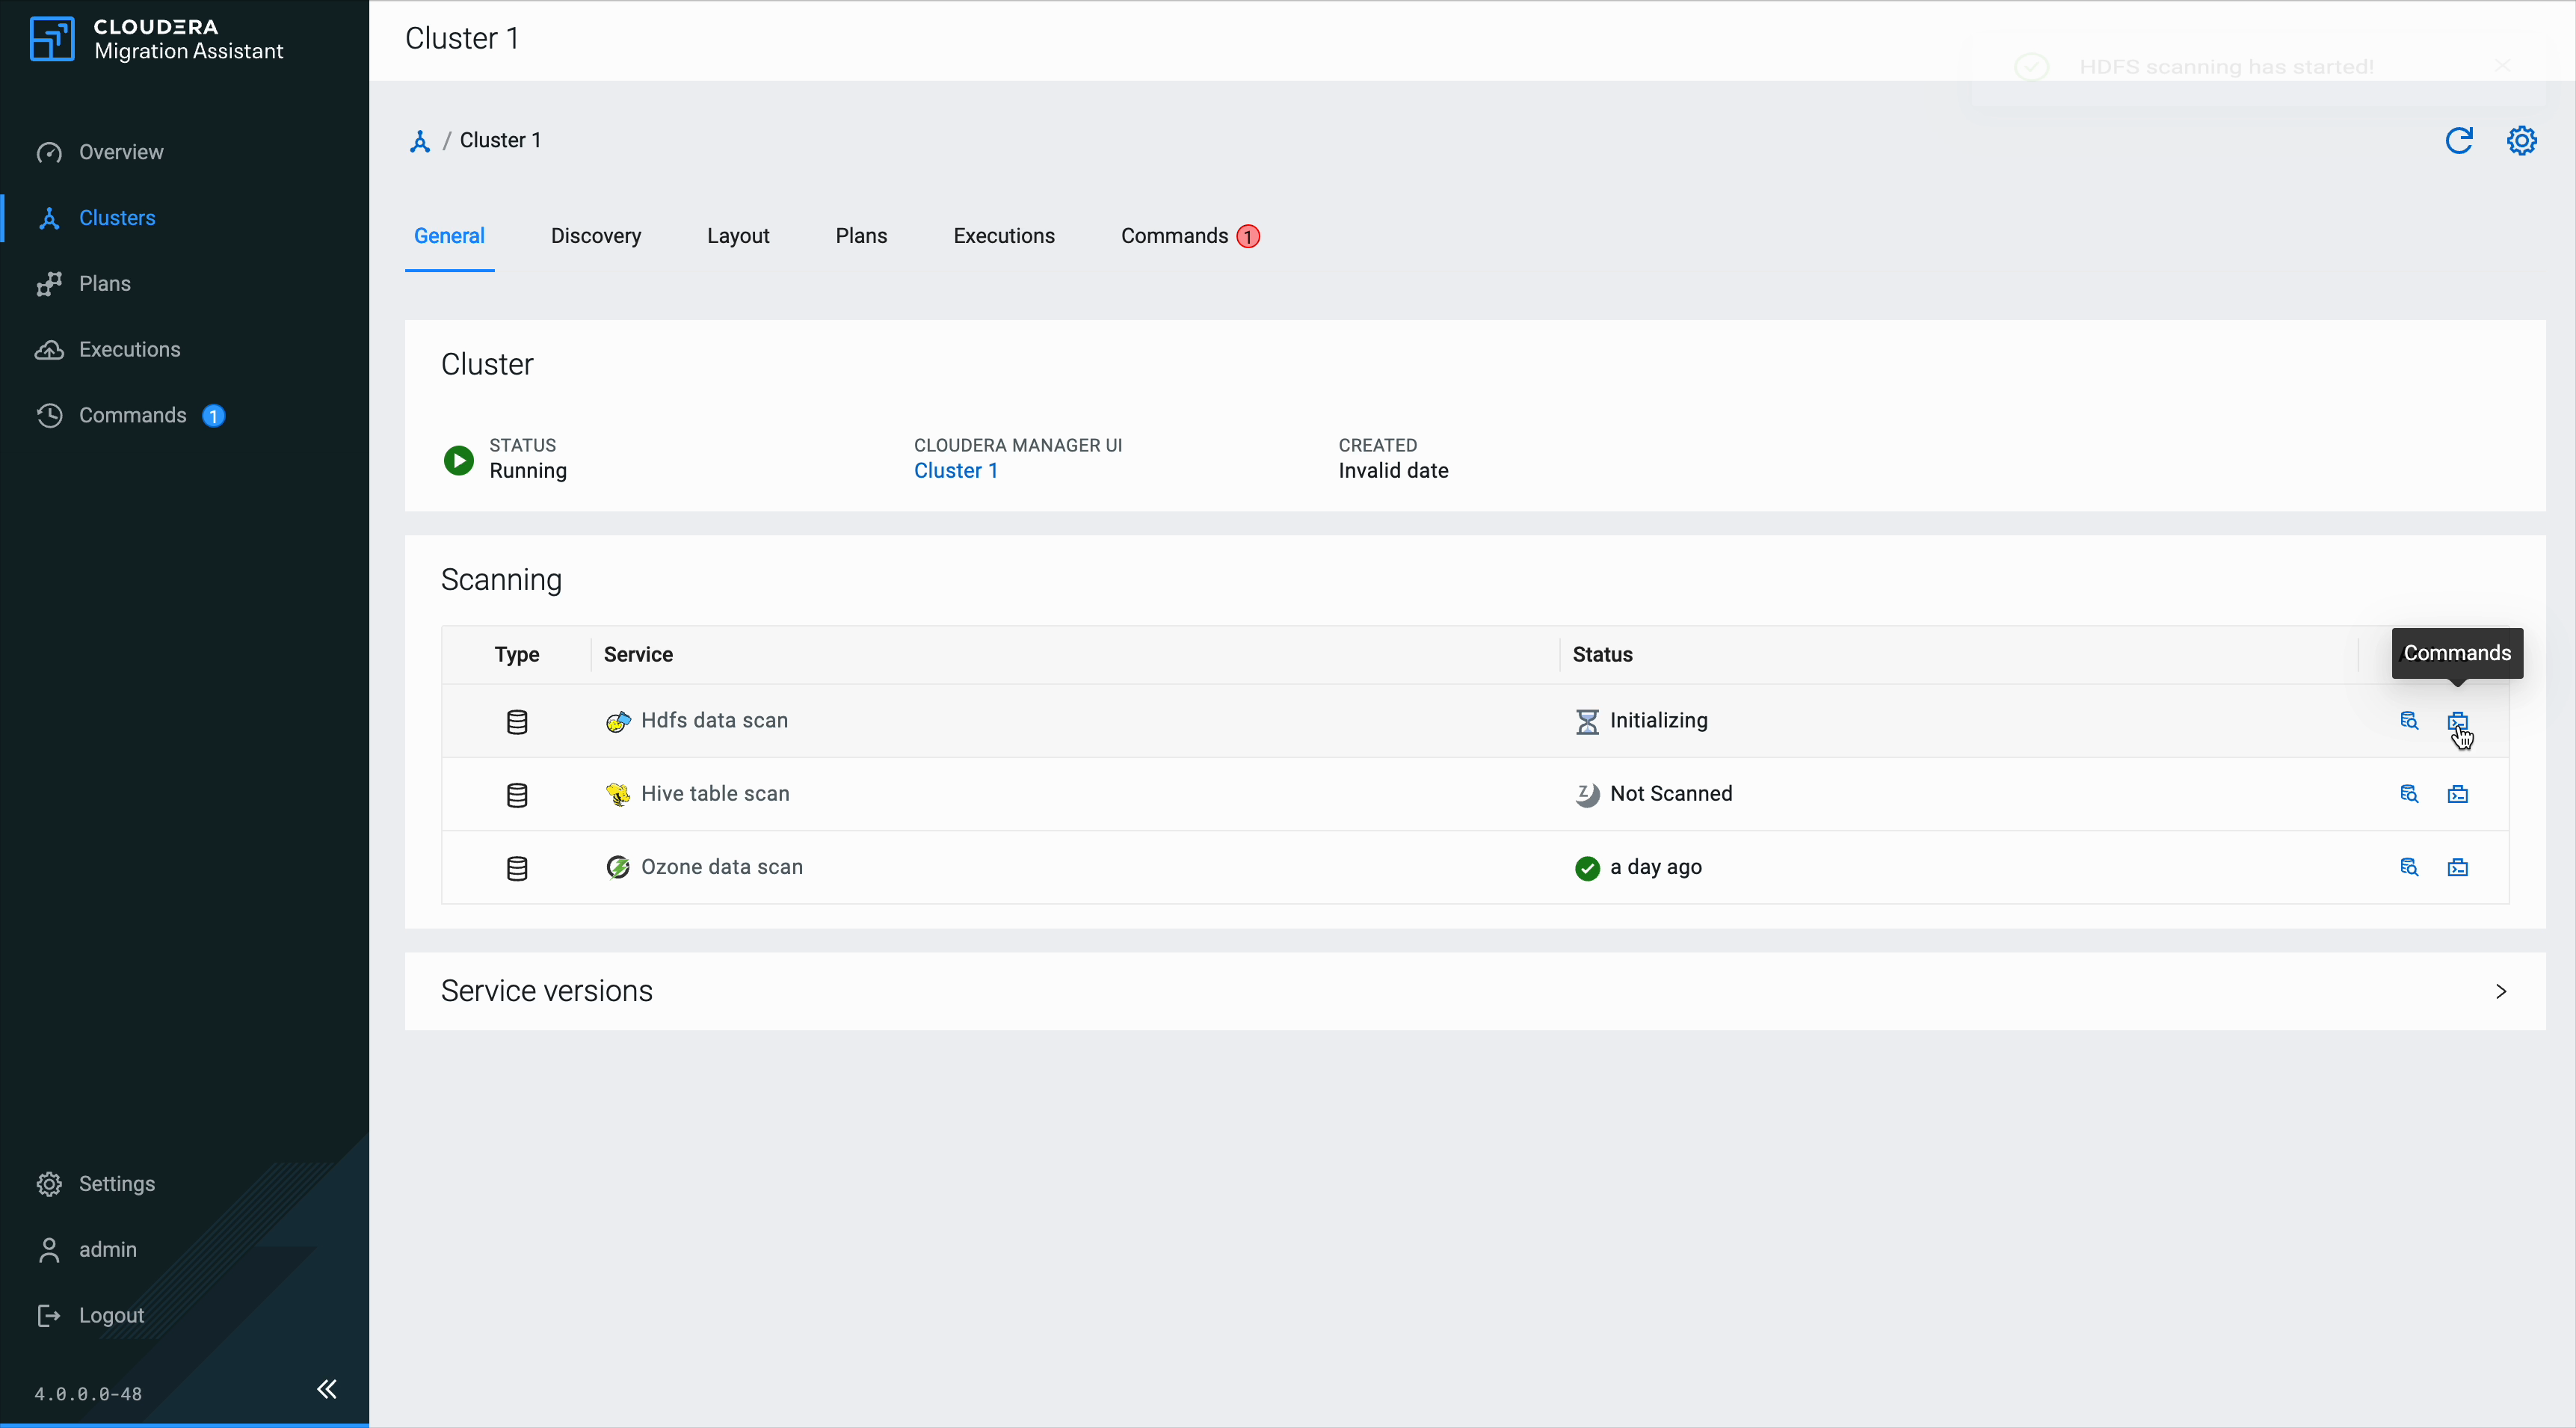
On the cluster detail page, find the Scanning section, which lists the available scan types for your cluster. Click the configuration icon on the right side of the scan type you want to trigger.
Figure 7. cluster scanning
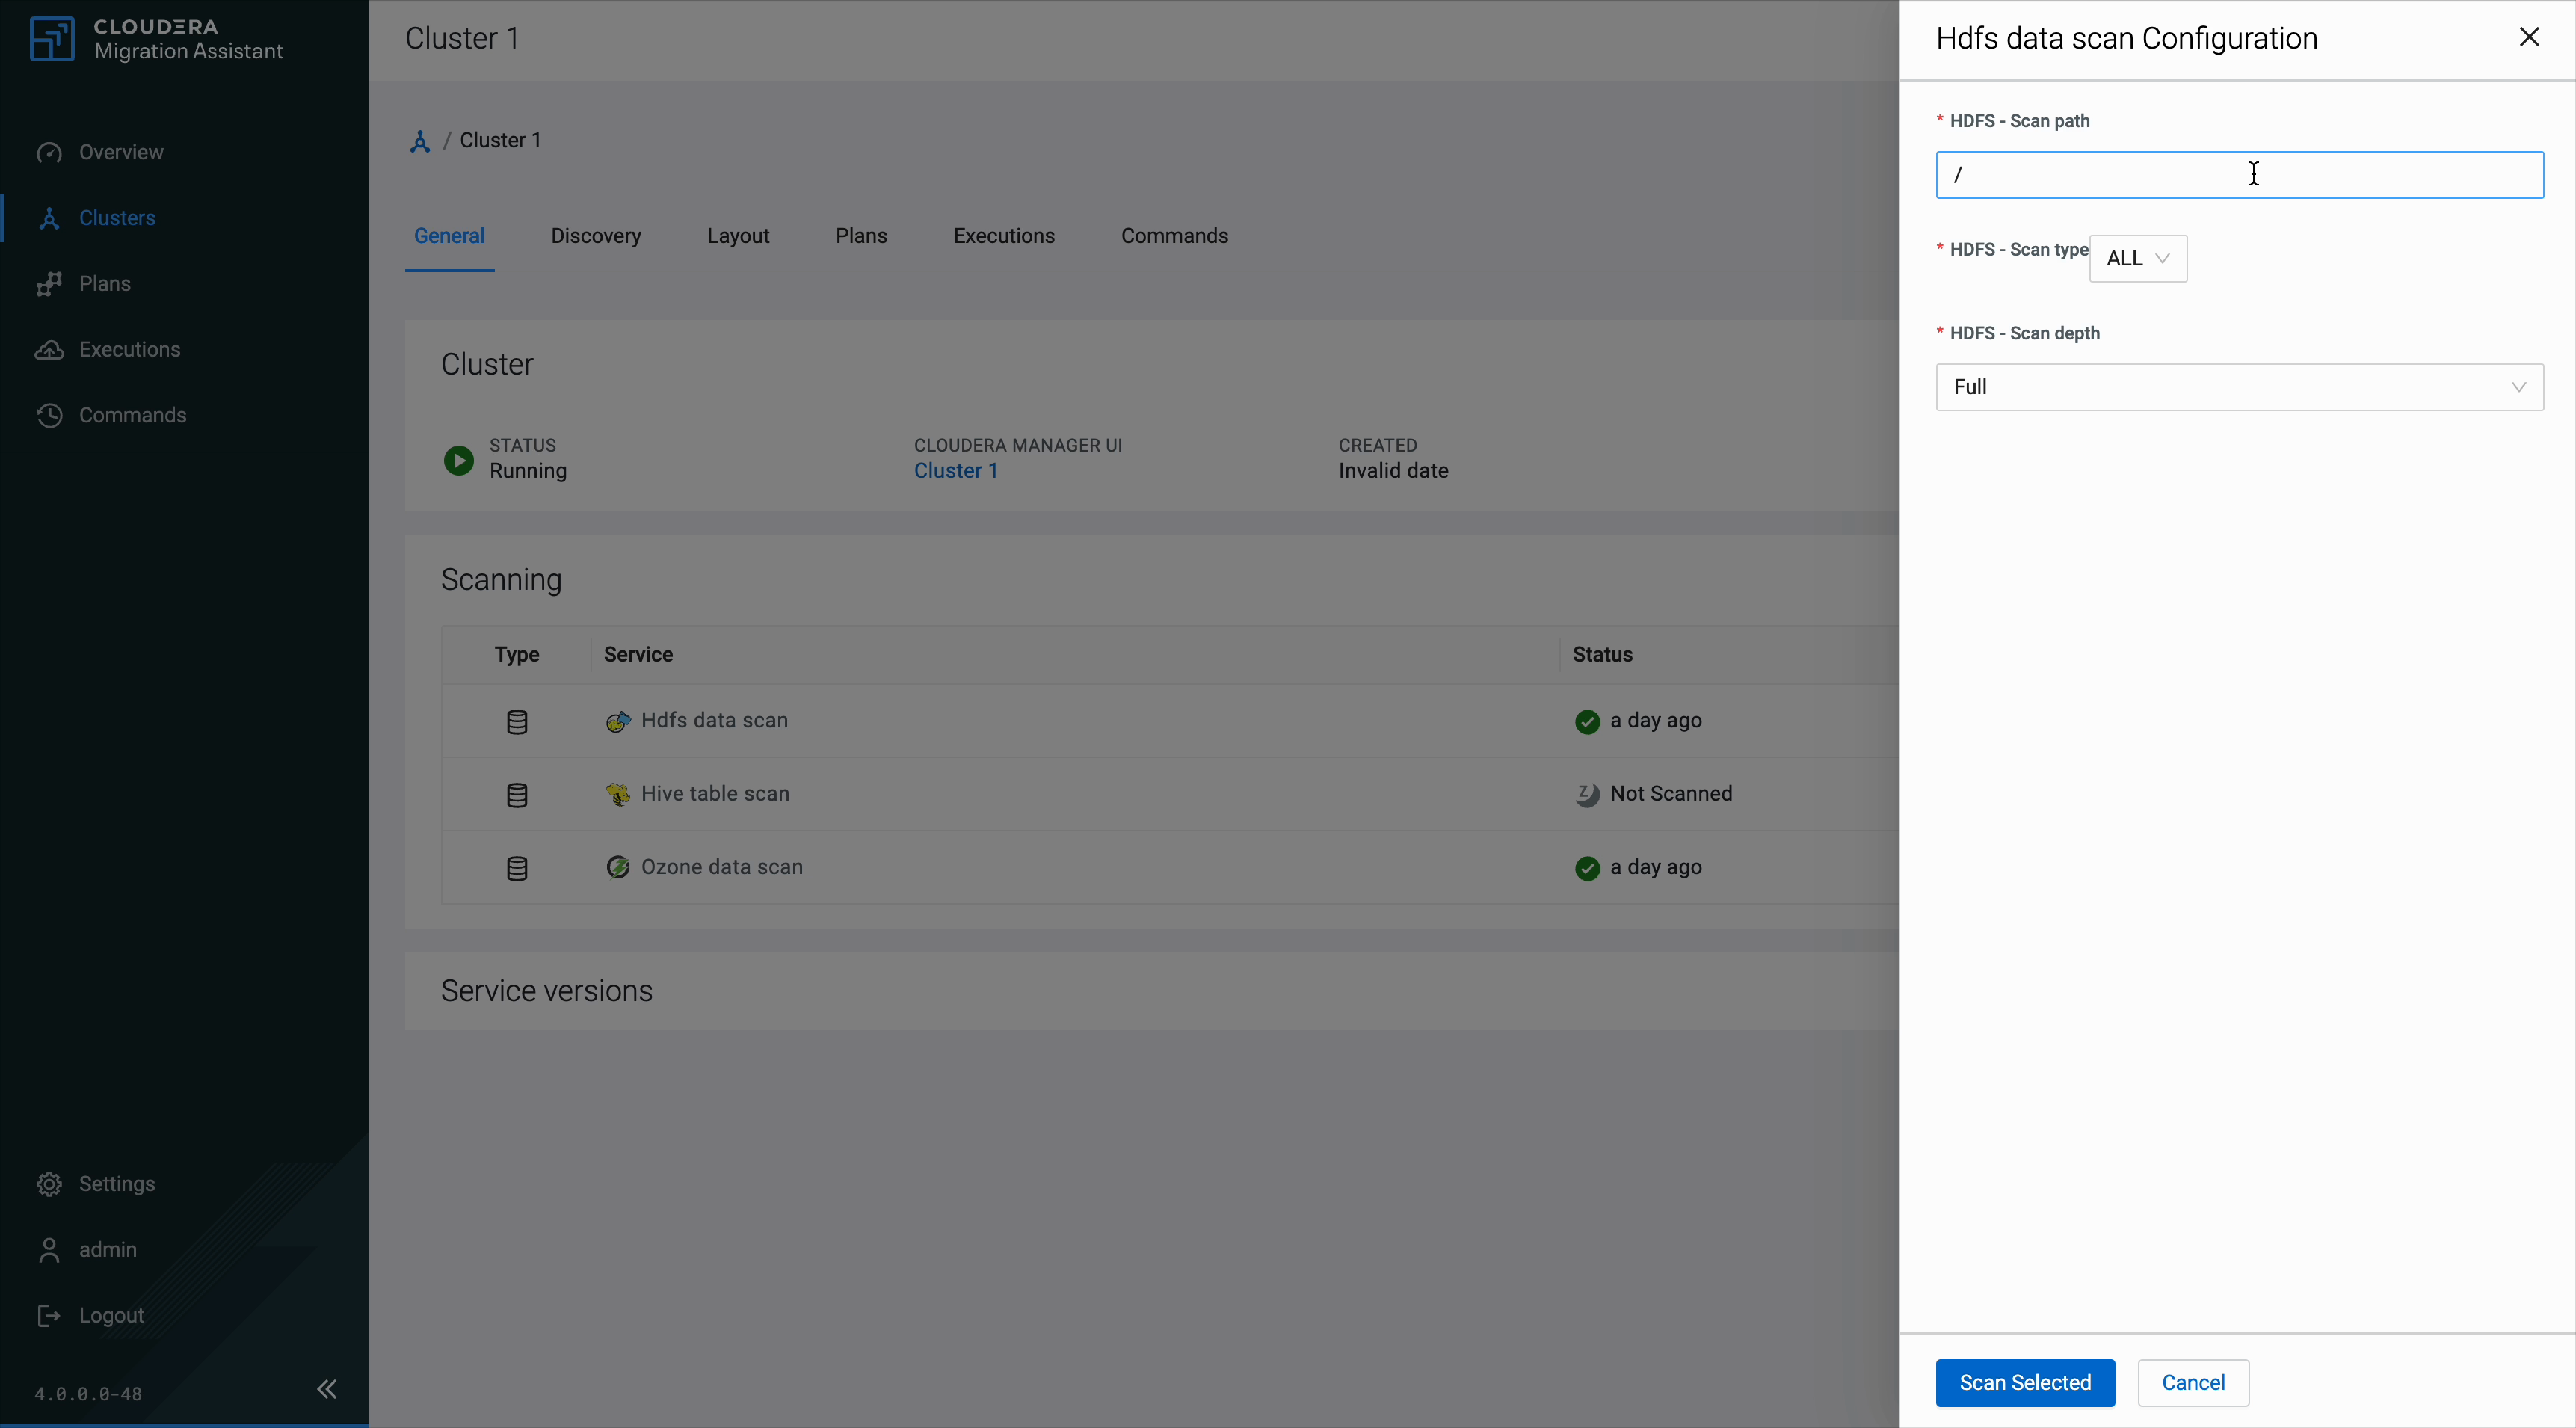
In the scan configuration drawer, configure the scan parameters (for example, scan path, scan type, scan depth) and click Scan Selected.
Figure 8. scan configuration
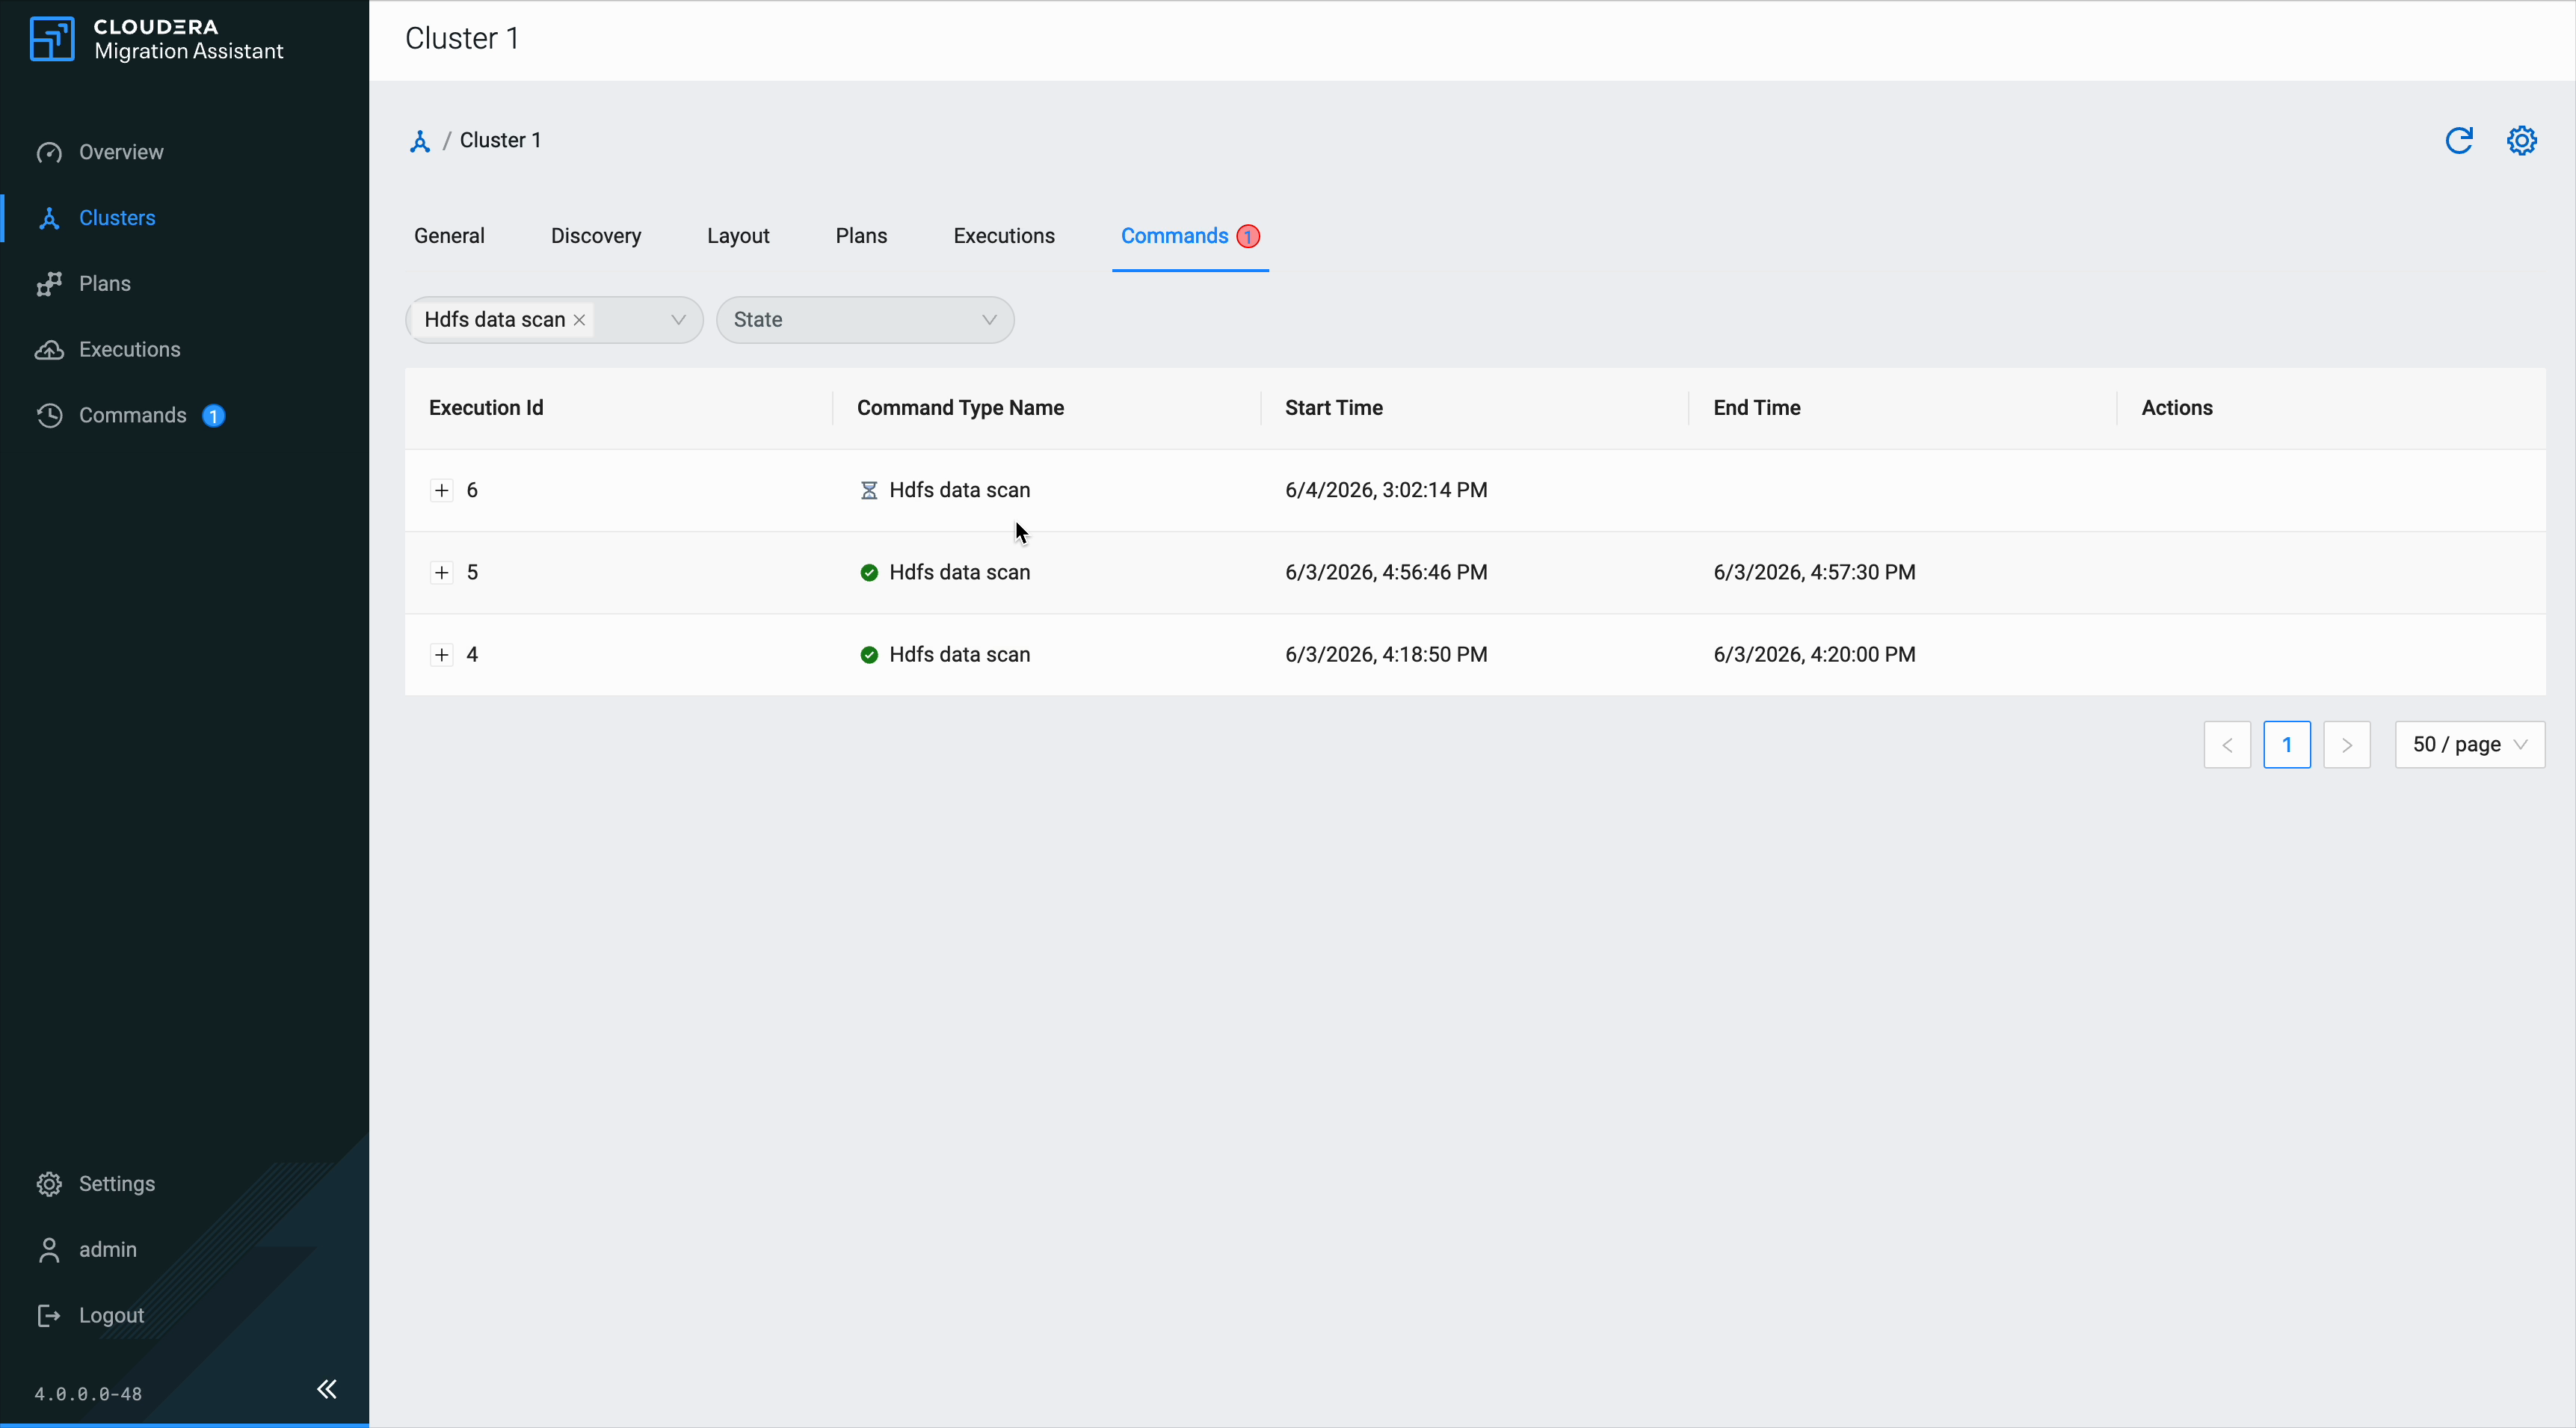
The scan starts and the status changes to Initializing. Track scan progress by clicking the Commands tab, which shows a badge with the number of active commands.
Figure 9. scan in progress
On the Commands tab, expand a command to view its Output Log, Error Log, and Configuration.
Figure 10. scan commands
Phase 5 — Create collections (optional)
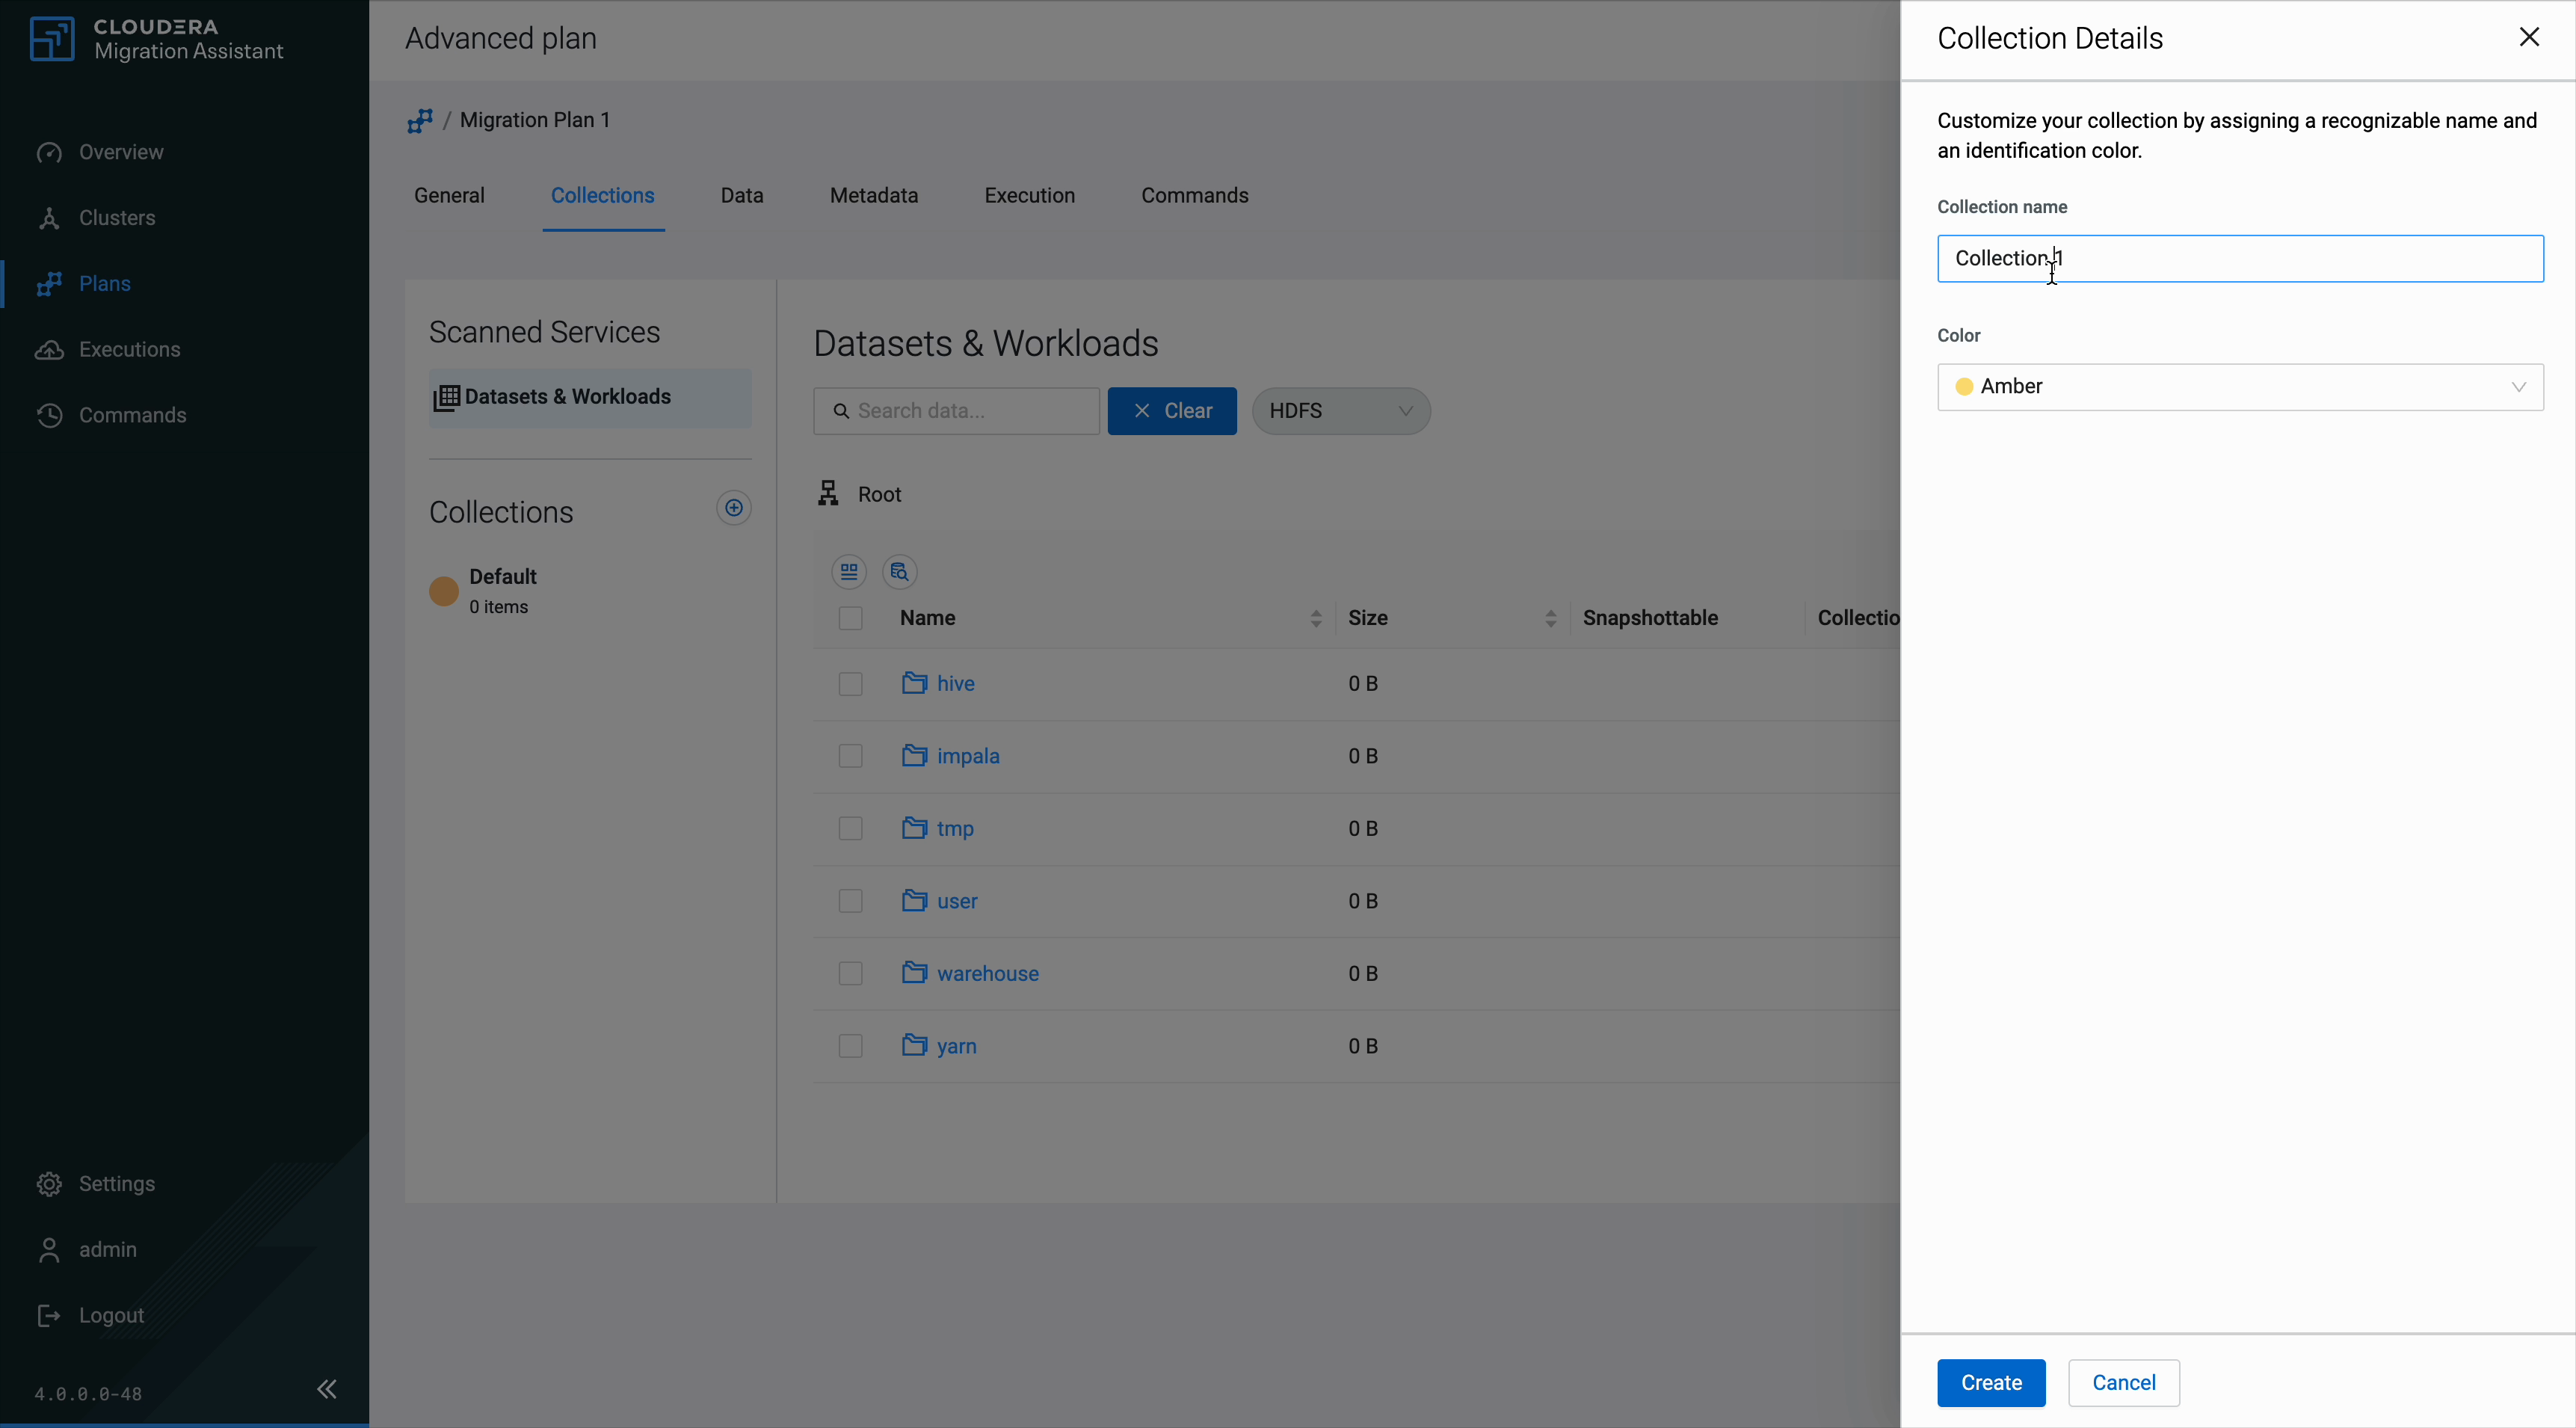
Click the + icon next to Collections in the sidebar.
In the Collection Details drawer, enter a Collection name and select a Color for identification.
Figure 11. create collection
Click Create.
The new collection appears in the sidebar with 0 items.
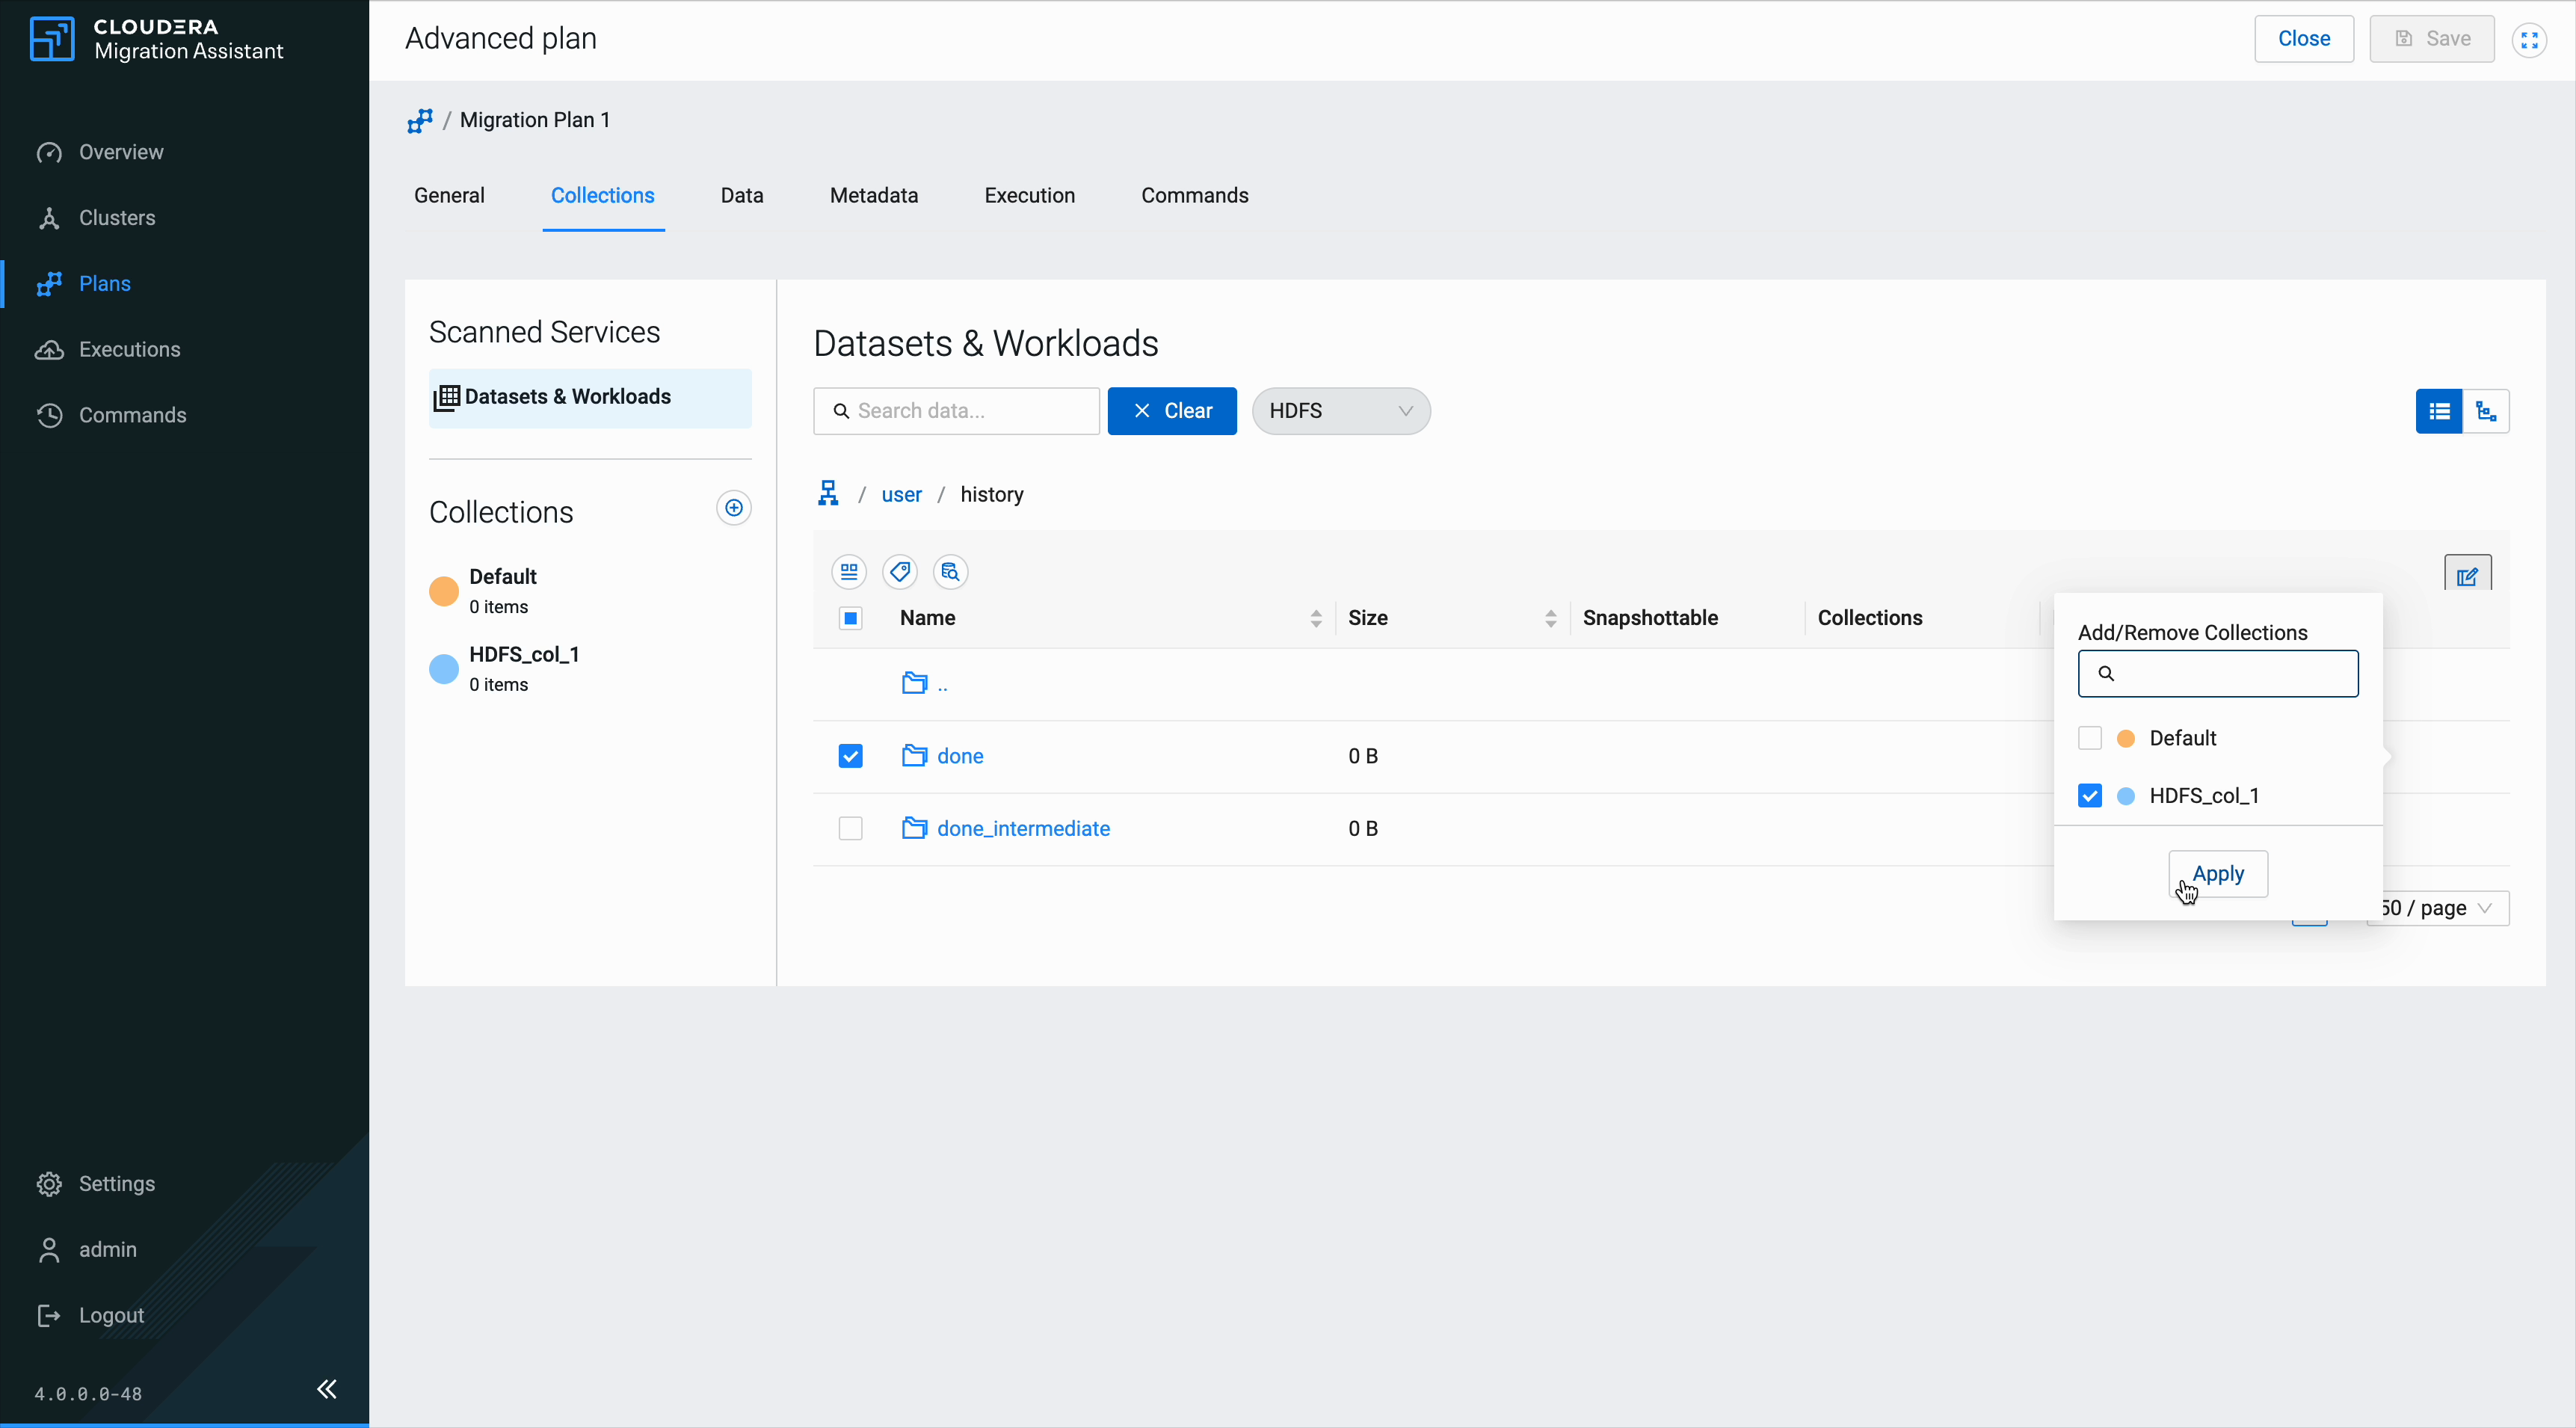
Browse the data tree to find the items you want to migrate. Click folder names to navigate deeper into the hierarchy.
Select items using the checkboxes next to each item.
Click the collection icon that appears on the selected item row.
In the Add/Remove Collections popup, check the collections you want to assign the item to.
Click Apply.
Figure 12. assign to collection
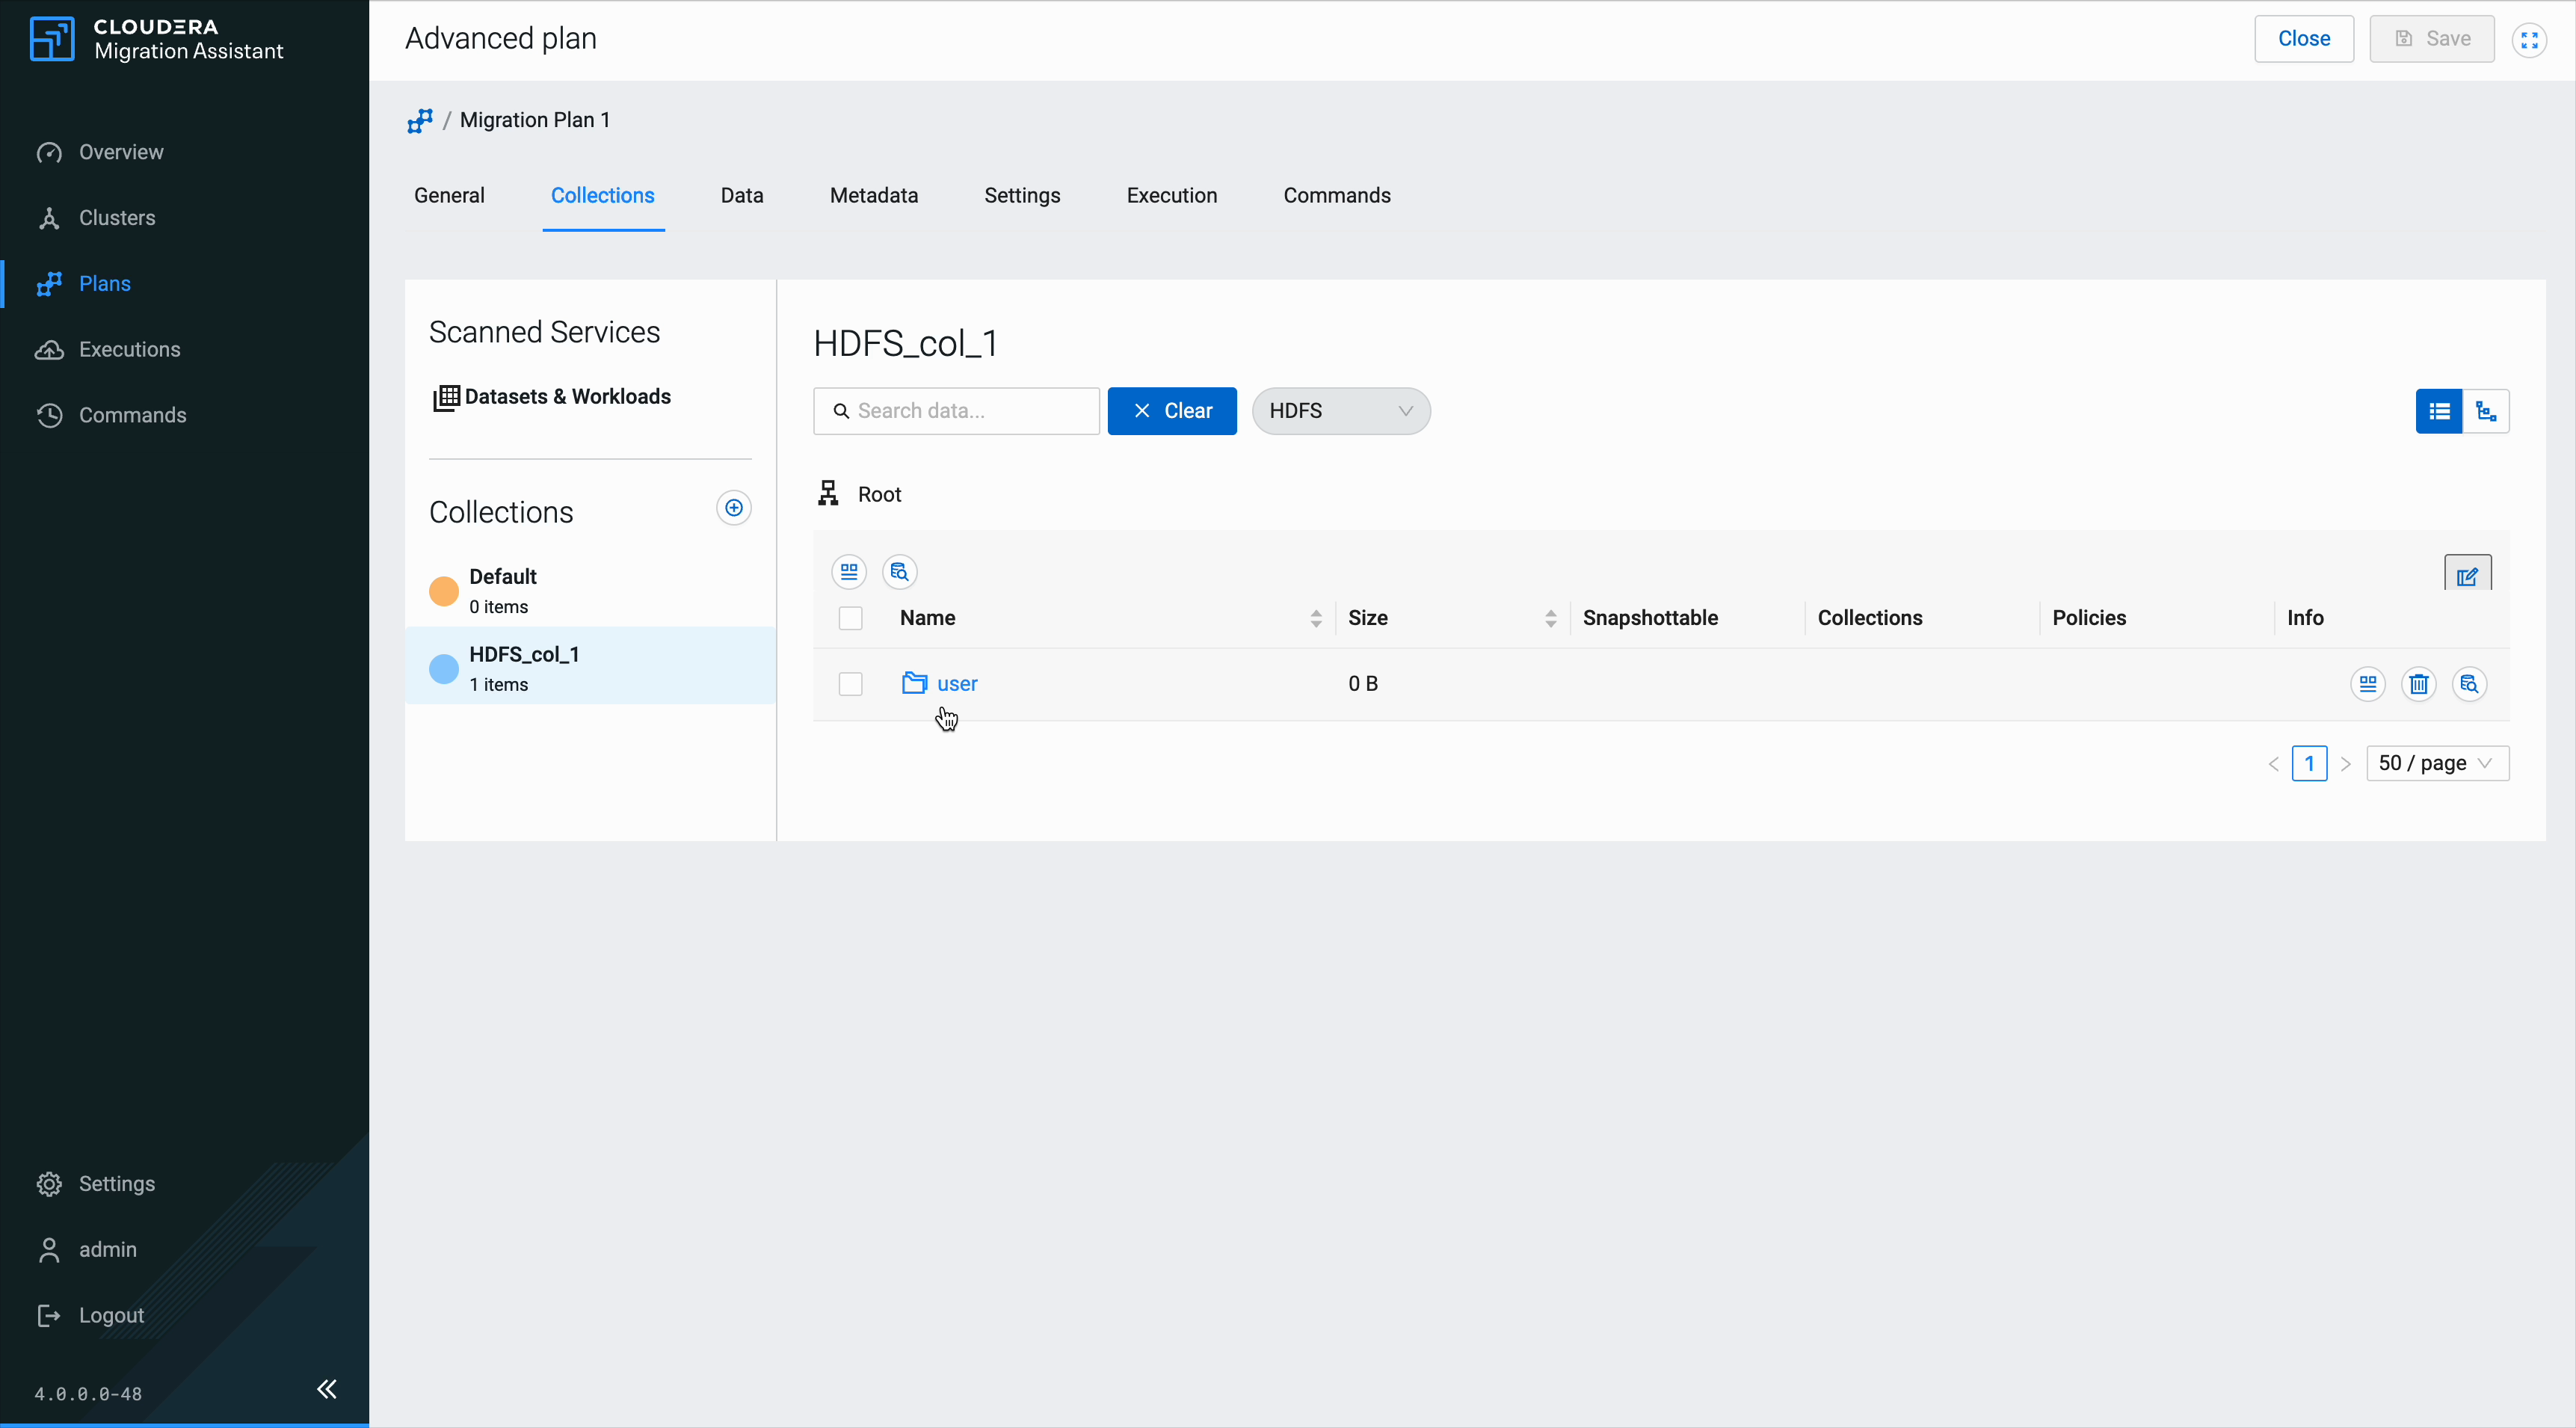
Click a collection name in the sidebar to view its contents. The data browser switches to show only the items assigned to that collection.
Figure 13. view collection
Phase 6 — Run the migration workload
Step 1 — Scan the
cluster
Identify the cluster whose name suffix reads
-cde
and
open it.
Click Start Scanning.
Select Scan for Airflow.
Click Scan
selected
and
wait until the progress indicator
displays
success.
Reading
scan
results
Discovery
displays
CDE Service → Virtual Cluster → Airflow DAGs. Expand each branch
to inspect
individual
items.
Table 5. Discovery page columns
Column
Description
DAG
Name
job
display
name.
DAG
ID
Unique
ID (dag_id) inside the
Python
script.
Cron
Configured schedule expressions.
Active
Indicator of the DAG schedule status.
Operators
Inferred operators,
such
as
BashOperator.
Triggers
Outbound trigger graph.
Triggered
By
Inbound trigger graph.
Resource
Pools
resource pools
allocated
for mounted
artifacts.
You can use the following interface controls to change how the data is displayed:
Data –
Switches to a
file-centric
tree, which
is
ideal before
creating
mappings.
Metadata —
Switches to the logical view of DAG summaries.
List/tree
toggle –
Switches
between hierarchical
tree
and flattened
browsing
list.
Step 2 — Scan the Git Repository
Open clusters ending in -git.
Click Start Scanning.
Select
Git Repository Scan, then click
Scan selected.
The repository tree displays
Name
and
Size metadata.
Empty
repositories are acceptable because executions bootstrap directories.
Step 3 — Create a Migration Plan
On
the
Plans
tab,
click Create Plan.
Select a descriptive name aligned with Git branch naming rules
(cma/<planName> prefixes created branches).
Select the -cde source and -git target
clusters.
Select
DAGs to Git
Repository
as transition type, then finalize creation.
Step 4 — Label DAGs on the
Collections tab
Collections act as a filter that controls which DAGs are visible on downstream configuration tabs.
In the
Plan tab,
go to
Collections.
Expand the
hierarchies.
Select DAG rows to migrate.
Click Add to collection, or
click the
+
icon to create a new collection.
Step 5 — Map DAG Metadata
On the
Metadata
tab,
review split panes listing (left) and Git (right) DAG
stubs.
Map individually (Map) or bulk-select unfinished rows
(Copy to Git).
Defaults land at /dags/<dagId>/<dagId>.py plus
/include/<service>/<vc>/<pool>/...
artifact
bundles.
Unmap removes targets while preserving shared
artifacts
when safe.
Step 6 — Verify File Paths
on
the
Data
tab
Go to
Data
to
compare mirrored trees.
Verify that DAG payloads and supporting files have the expected prefixes.
If
you notice any incorrect file paths, go to the
Metadata
tab to unmap or remap those files.
Step 7 — Review DAG Source (Workloads
tab)
Open Workloads whenever duplicate-ID badges block
executions.
Select DAG entries to load Monaco editors with read-only scanned copy displayed in the left pane, editable version in the right pane.
Edit the right pane to rename dag_id, revise connections, or prune
unsupported operators
and
save afterward.
Ensure that warnings clear across every DAG affected by overlaps.
Step 8 — Execute Git Publishing
In
Execution, click
Create Execution.
Monitor the sequential pipeline as it automatically processes the following stages:
Upload
resources –
The retrieve scanned artifacts
locally (skipped when unnecessary).
Prepare
resources –
The merges edited DAG payloads with
staging artifacts.
Create Git
change –
The
Git-role agents clone staging work, publish branch
cma/<planName>, commit files, then open
Pull
Requests, or
Merge
Requests
or fallback pushes depending on
your
Git
configuration.
Step 9 — Inspect Provider Output
Expand the completed
Create Git Change rows to
view
direct
links to your
repository.
Click the outbound links to open the generated Pull Requests or Merge Requests in your Git provider interface.
Merged
repositories
carry DAG
artifacts
on tracked base
branches and
workspaces continue governing runtime workloads.