Deploy Cloudera Migration Assistant, register clusters, and run an HDFS to HDFS migration using Cloudera Replication Manager replication.
This end-to-end workflow combines deployment, platform preparation, discovery, and workload steps. Detailed reference procedures are reused from the Administrator and Migration guides.
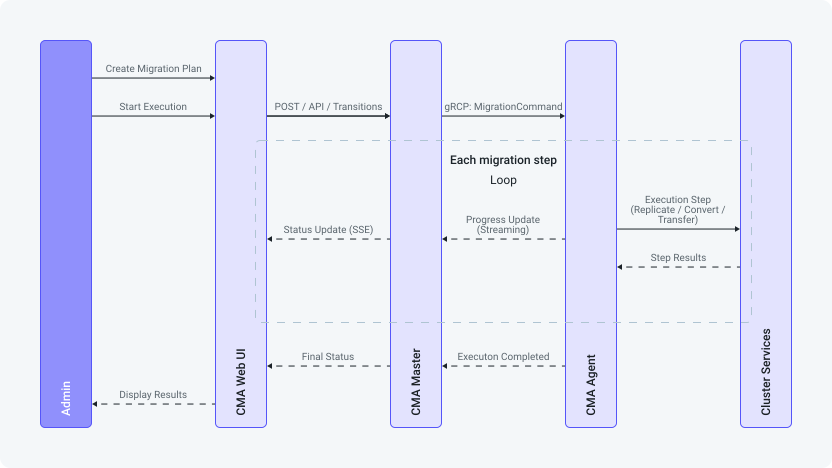
Figure 1. Migration flow
Verify supported platforms and migration paths in Supported platforms and migration paths before you start.
Phase 1 — Deploy the CMA Master and CMA Agents
Download both CSD files to the
/opt/cloudera/csd/ directory on the
Server host.
Click Save & Verify Configuration to commit the
change.
Click Close.
You are redirected to the Parcels page.
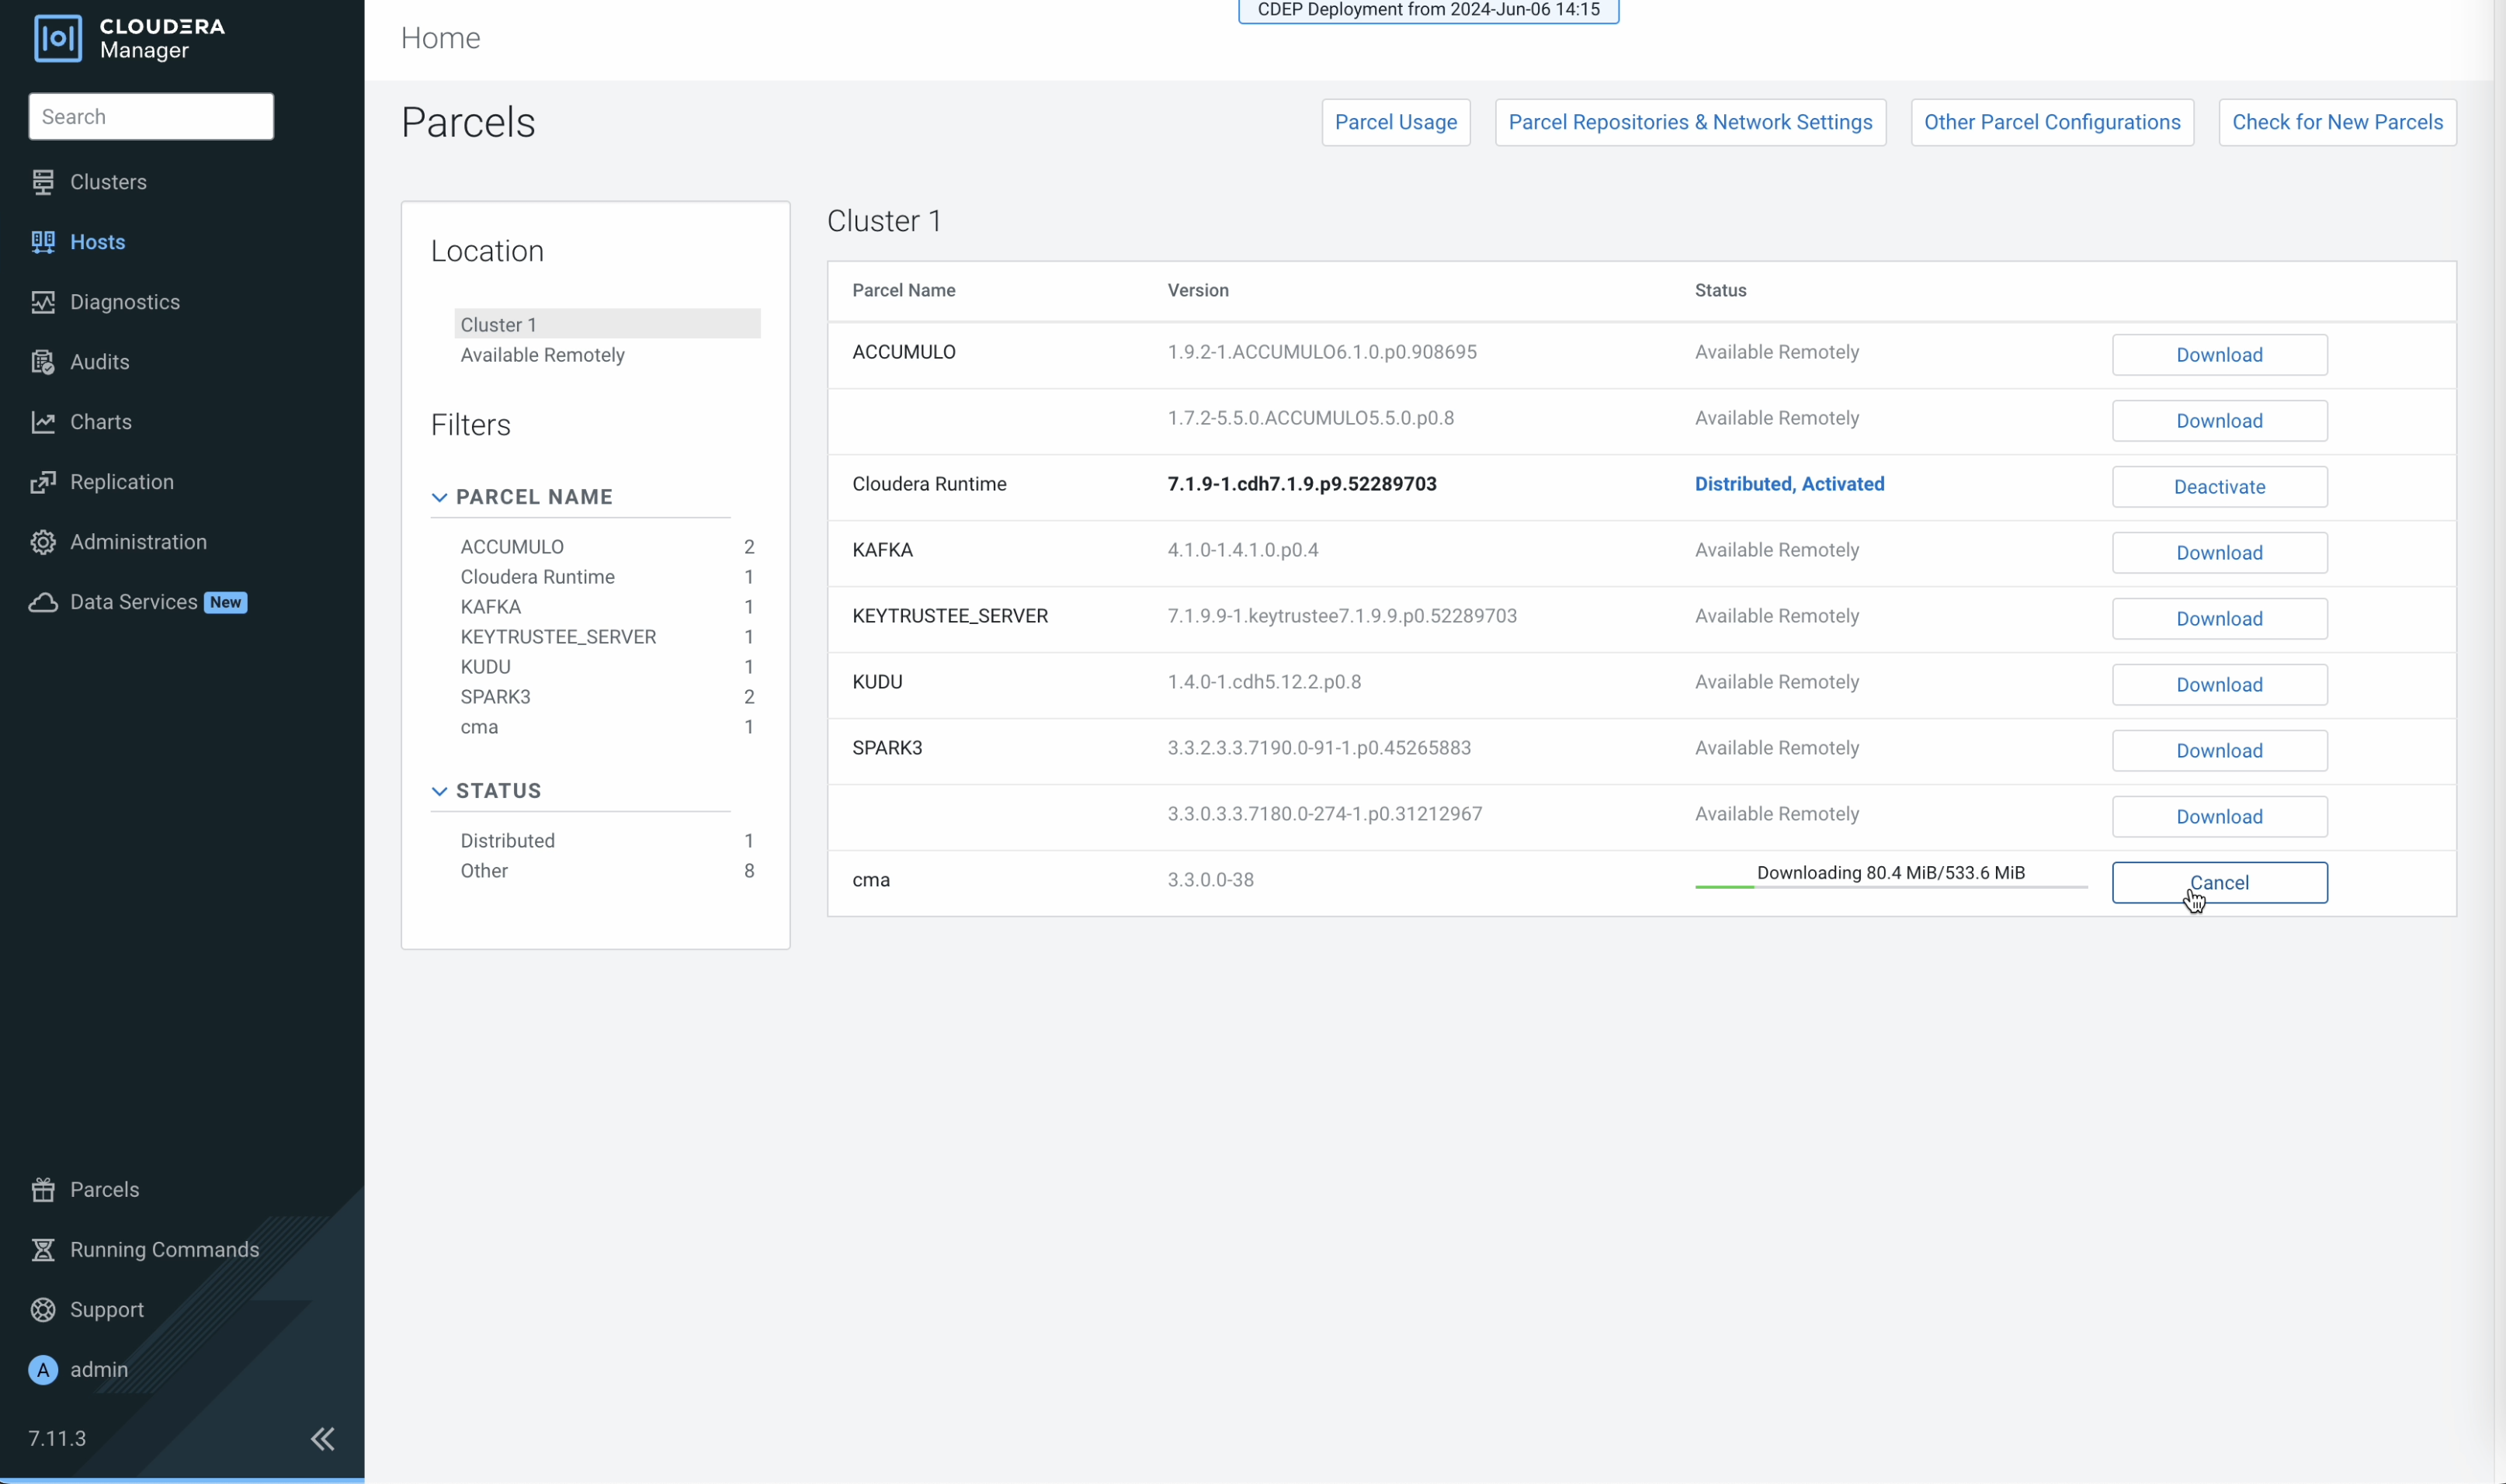
Search for , and click
Download
to download the parcel to the local repository.
After download completes, click Distribute to distribute the
parcel to all clusters.
Figure 2. Distribute the parcel
Click
Activate
to activate the parcel.
Click
OK
when confirmation is required.
Click
Clusters
in
the left navigation pane.
Select
Add
Service from the drop-down menu to the right of your
cluster.
From the list, select the service type to add,
then click Continue. The single
parcel provides two service types: CMA_MASTER (central control node) and
CMA_AGENT (cluster-side executor).
The Add Service wizard opens.
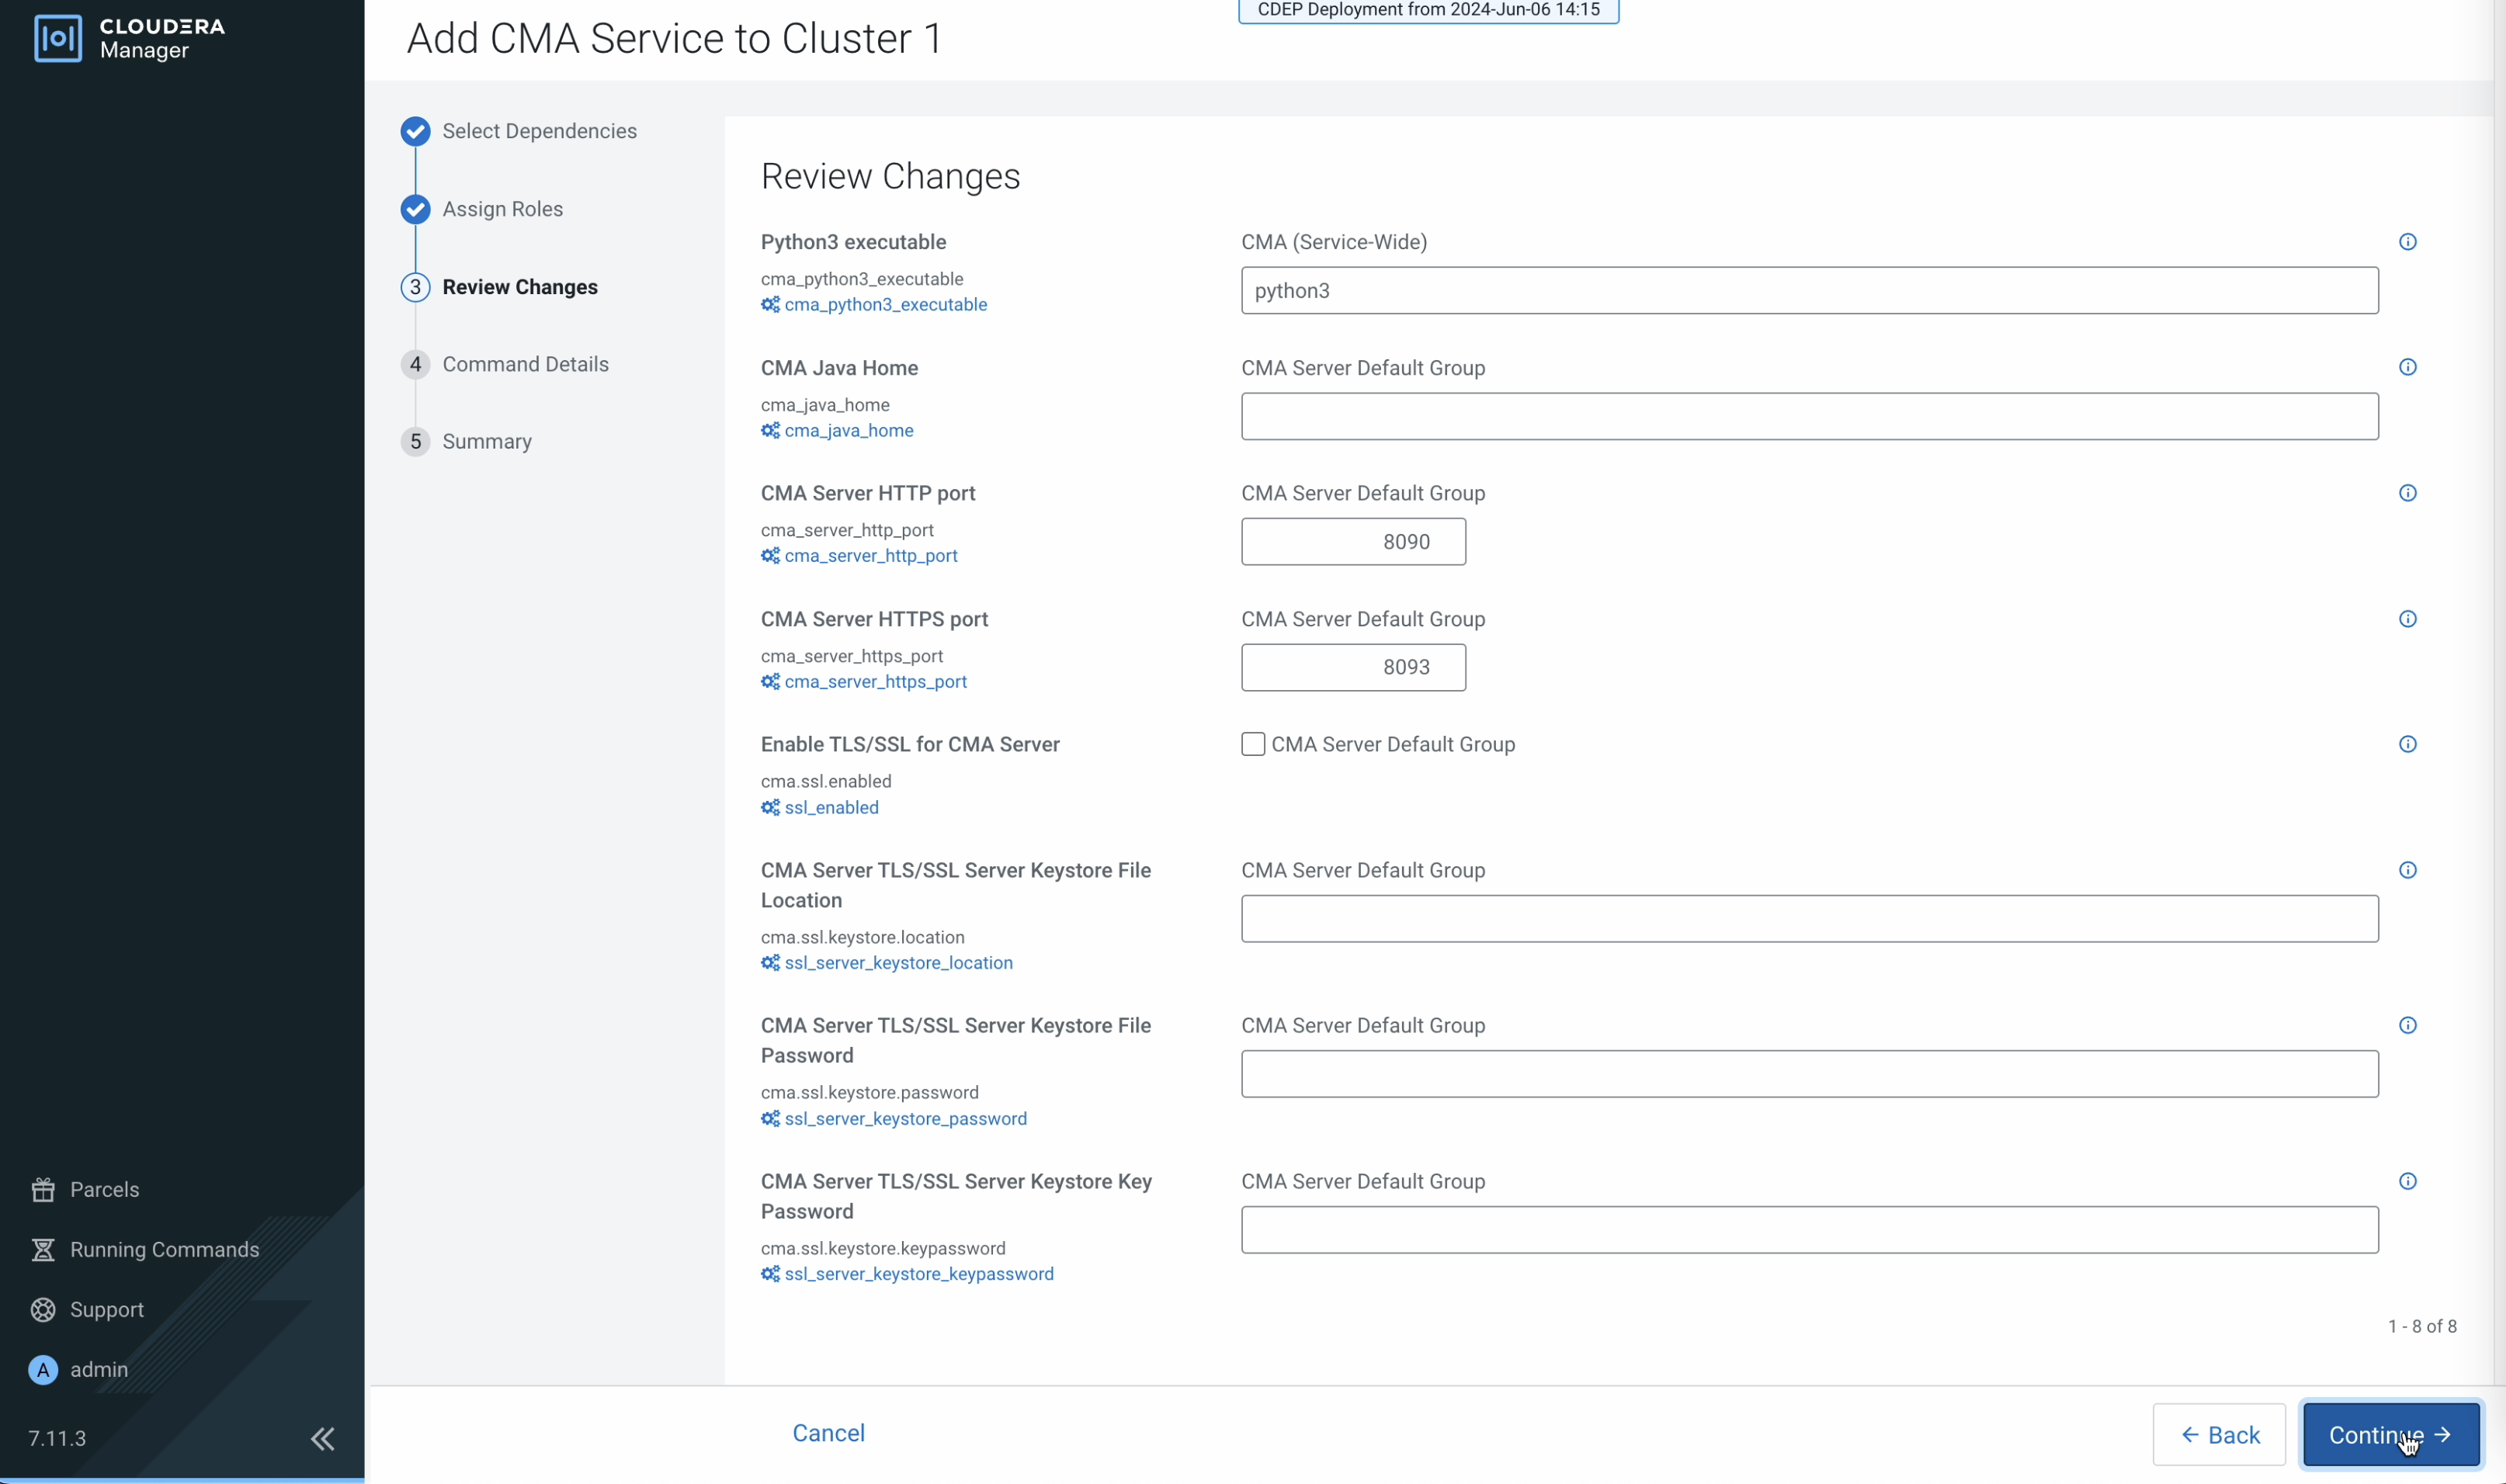
Figure 3. Add service
Assign the service roles to the hosts where Python 3.11 and JDK 17+ are installed, and
click
Continue.
Review service configurations and click Continue. At minimum, set
OAuth2 client credentials (cma_client_secret,
cma_agent_client_secret). If the is on a different cluster from the , also set Gateway URL
(cma_gateway_url).
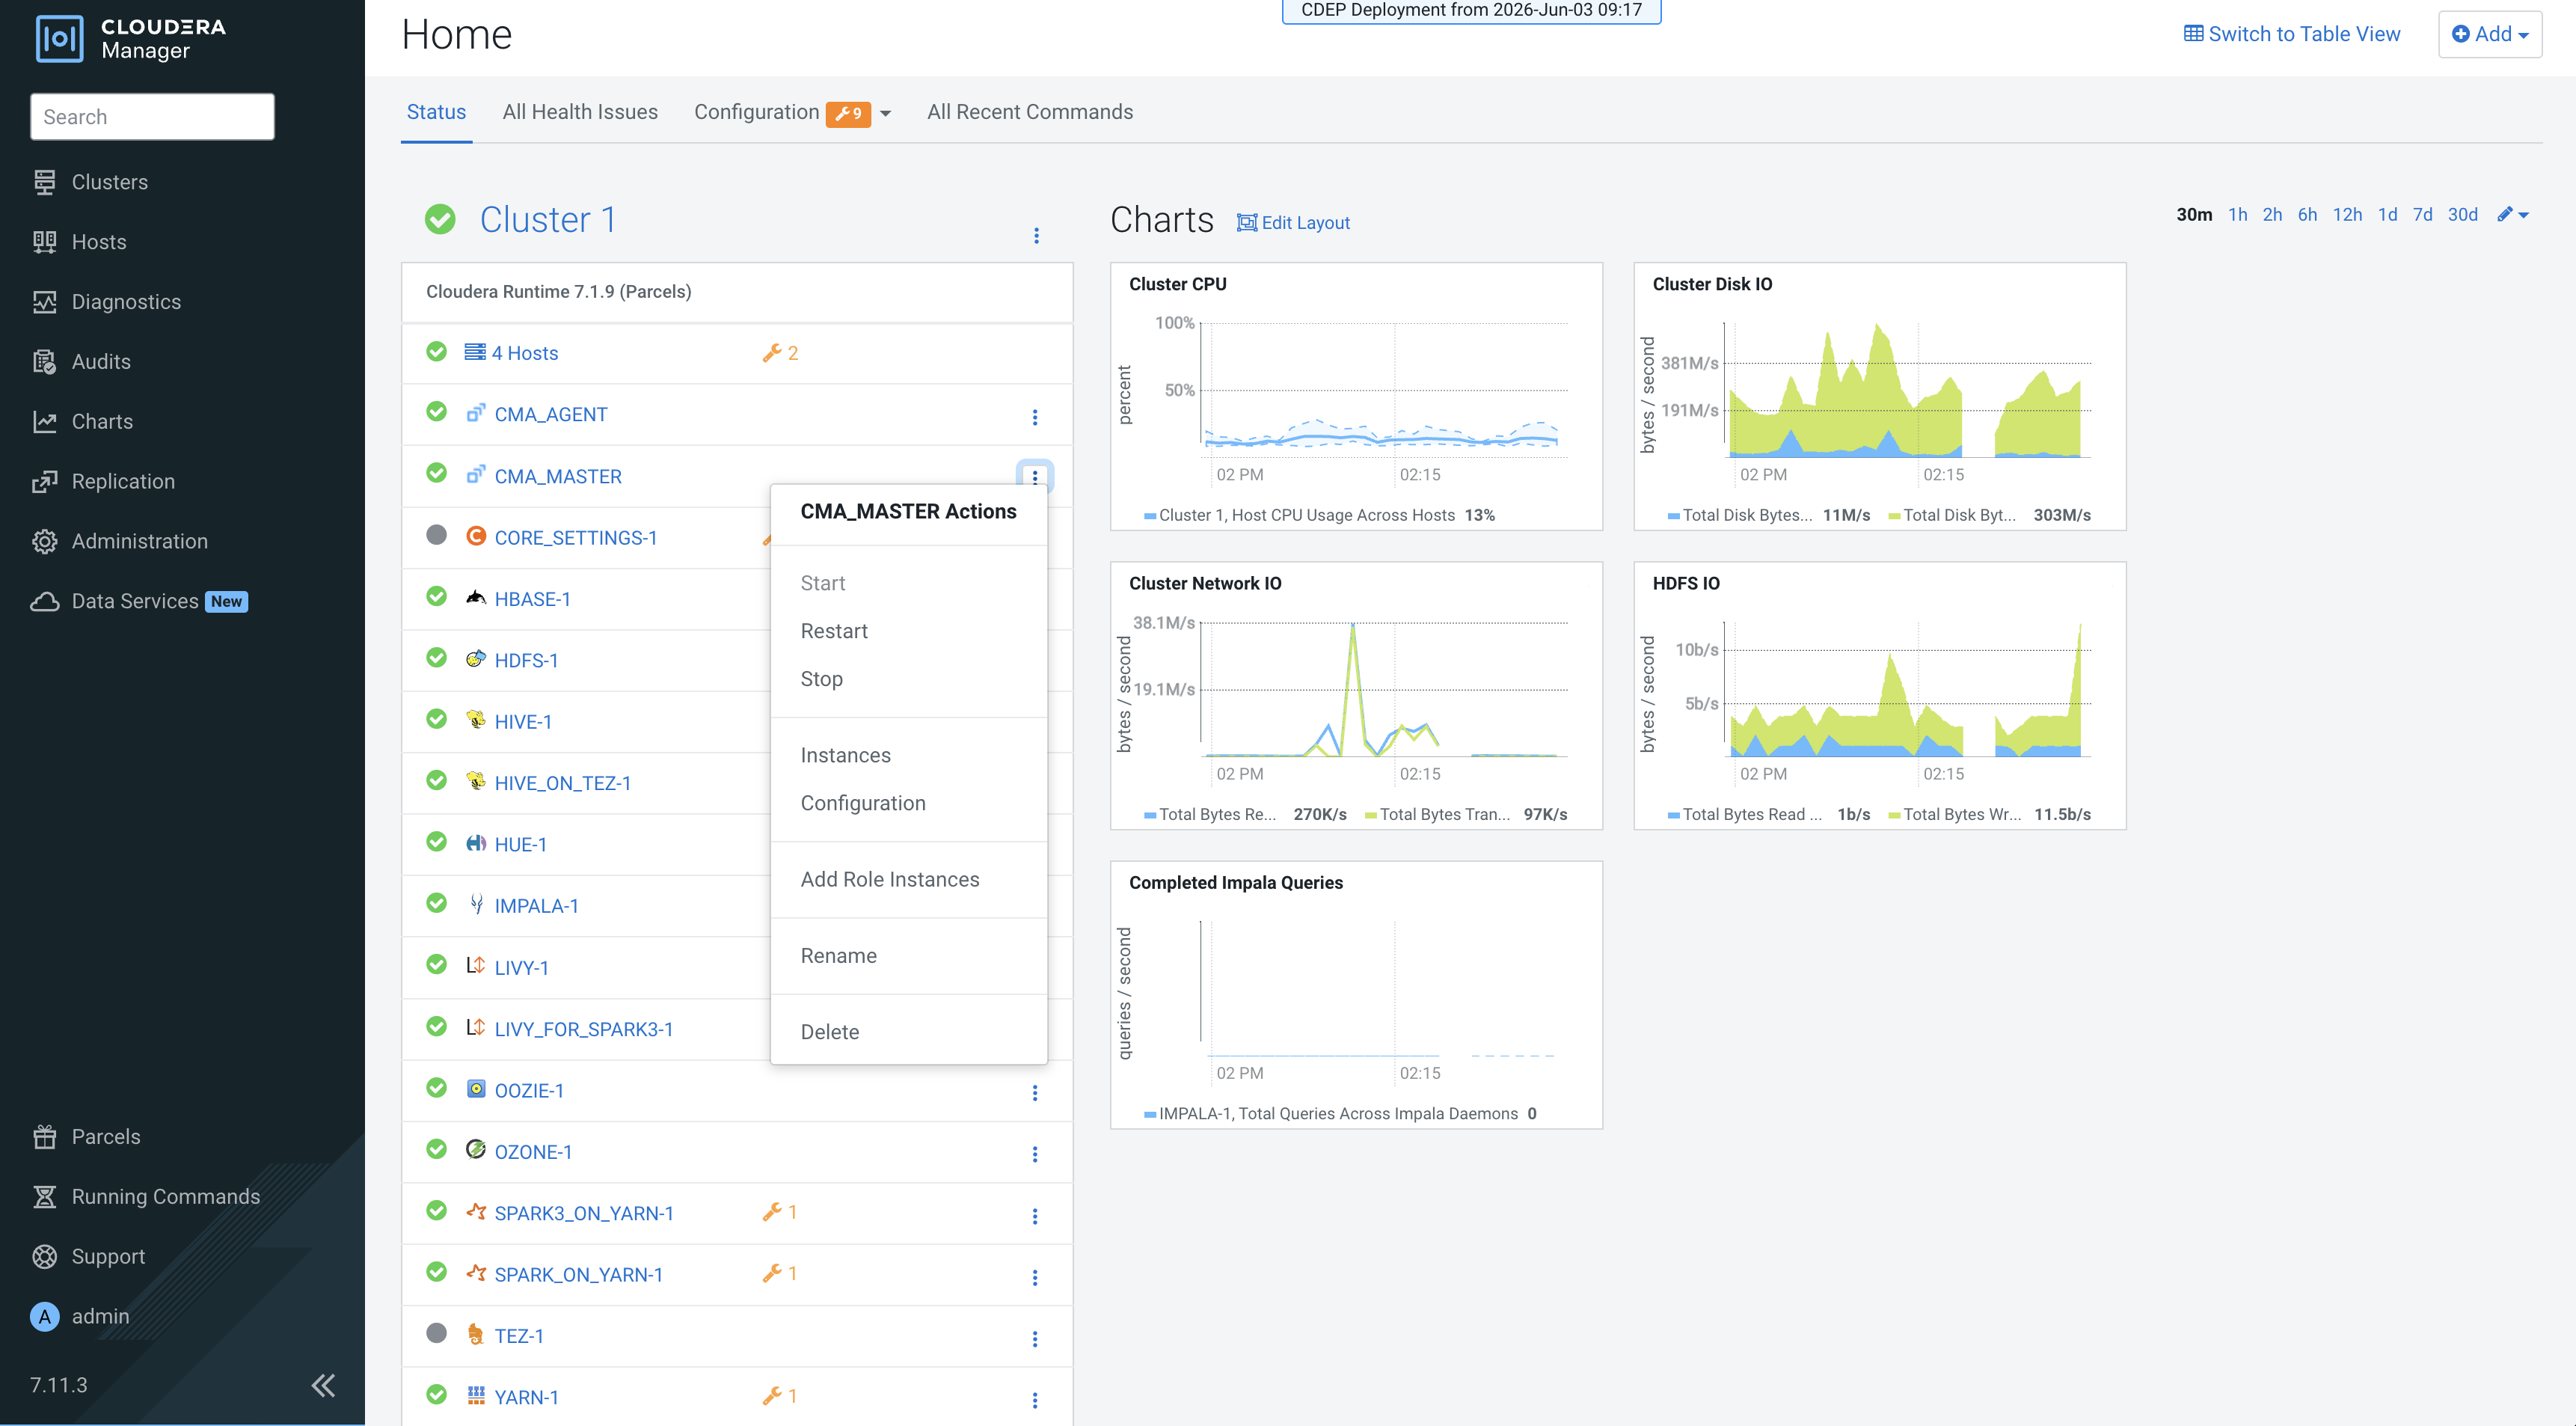
The first run of the service starts. When the command finishes, the service is added to
the cluster.
Figure 4. service started
Repeat steps
16–19
to add the other service type if
needed (for example, add
CMA_AGENT after CMA_MASTER, or vice
versa).
Go back to the cluster homepage, open the
service page, and click the Server UI tab to open the UI.
Figure 5. landing page
Set the
service dependency to
none
in the service configuration in Cloudera
Manager
because
Cloudera
Manager
cannot
discover the
Master automatically
across
clusters.
Set the Gateway URL
to
cma_gateway_url
in the service configuration.
Phase 2 — Configure Cloudera Replication Manager on the target cluster
Enable the HDFS to Ozone flag on the Server host.
For HDFS to Ozone migrations, requires the
CMF_FF_API_H2O_REPLICATION feature flag to be enabled. Without this
flag, the API endpoints for HDFS to Ozone replication
are not available.
Append the following line to /etc/default/cloudera-scm-server on
the Server host:
export CMF_FF_API_H2O_REPLICATION=true
Restart the Server.
sudo systemctl restart cloudera-scm-server
Wait for to become available again on port 7180 before proceeding
with the setup.
Register the instance in the UI to allow to locate and communicate with the replication service.
In the Web UI, go to
Settings.
Go to the App Access section.
Configure your connection fields using one of the following validation methods:
If has already detected a service on one of the registered clusters,
select it from the Suggestions drop-down list to
auto-fill the form.
Manually enter your target replication parameters in the following fields:
App URL — The full URL of the REST
API, including protocol, host, and port, for example,
https://rm-host.example.com:9011.
App username — The username for
authenticating with the API.
App password — The password for
authenticating with the API.
Click Save and Push to Agents.
Phase 3 — Register source and target clusters
In on the source cluster, select Add
Service and select
CMA_AGENT.
Configure the required properties.
Table 1. configuration properties
Property
Description
cma_gateway_url
URL of the Gateway,
for
example,
https://master-host:8093.
Required when the is on a different cluster
than
the . The agent uses this URL
to discover the Master host, gRPC port, and Auth Server URI automatically
through
the discovery endpoint (GET /api/agent/config). When connecting
from a different
cluster,
set the service dependency to
none
in .
cm_username
administrator user name.
cm_password
administrator password.
cma_user_home
Home directory for the cma-agent
user,
for
example,
/var/lib/cma-agent.
Set cma_gateway_url when the is on a different cluster than the .
Start the service.
Wait for the agent to connect to the
and finish
the
registration automatically.
Phase 4 — Scan clusters
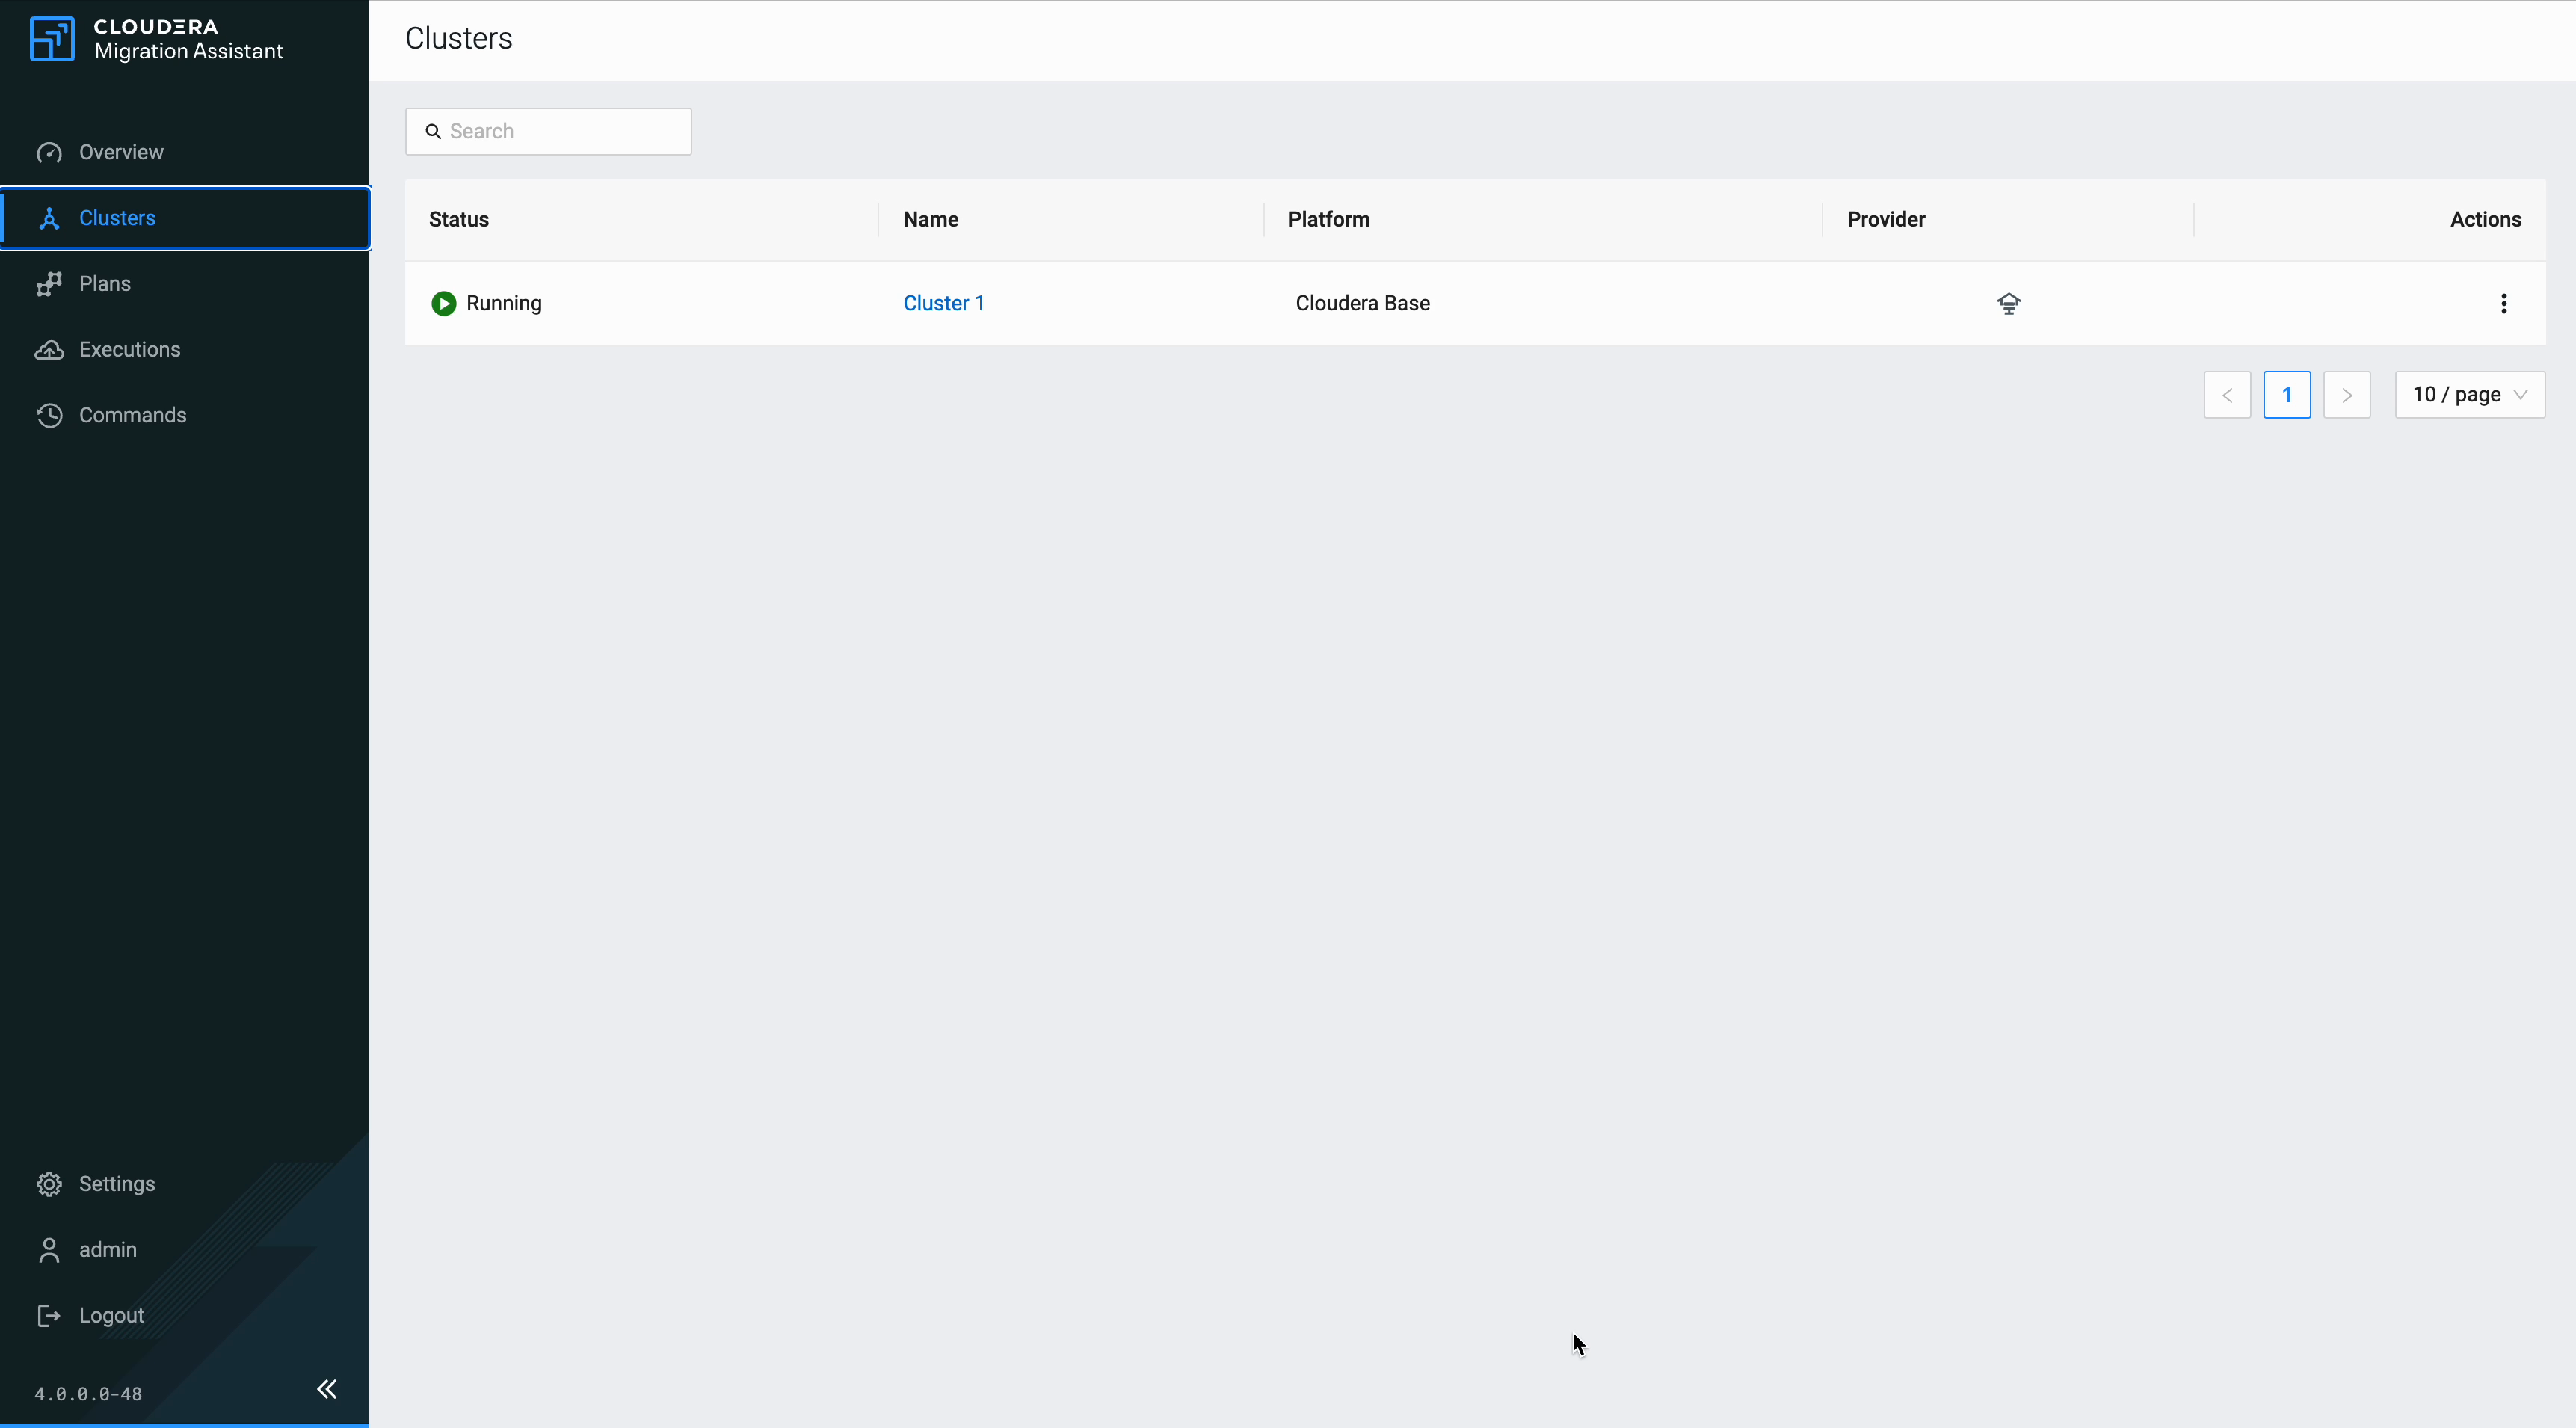
Navigate to the Clusters page and click the cluster you want to scan.
Figure 6. Clusters page
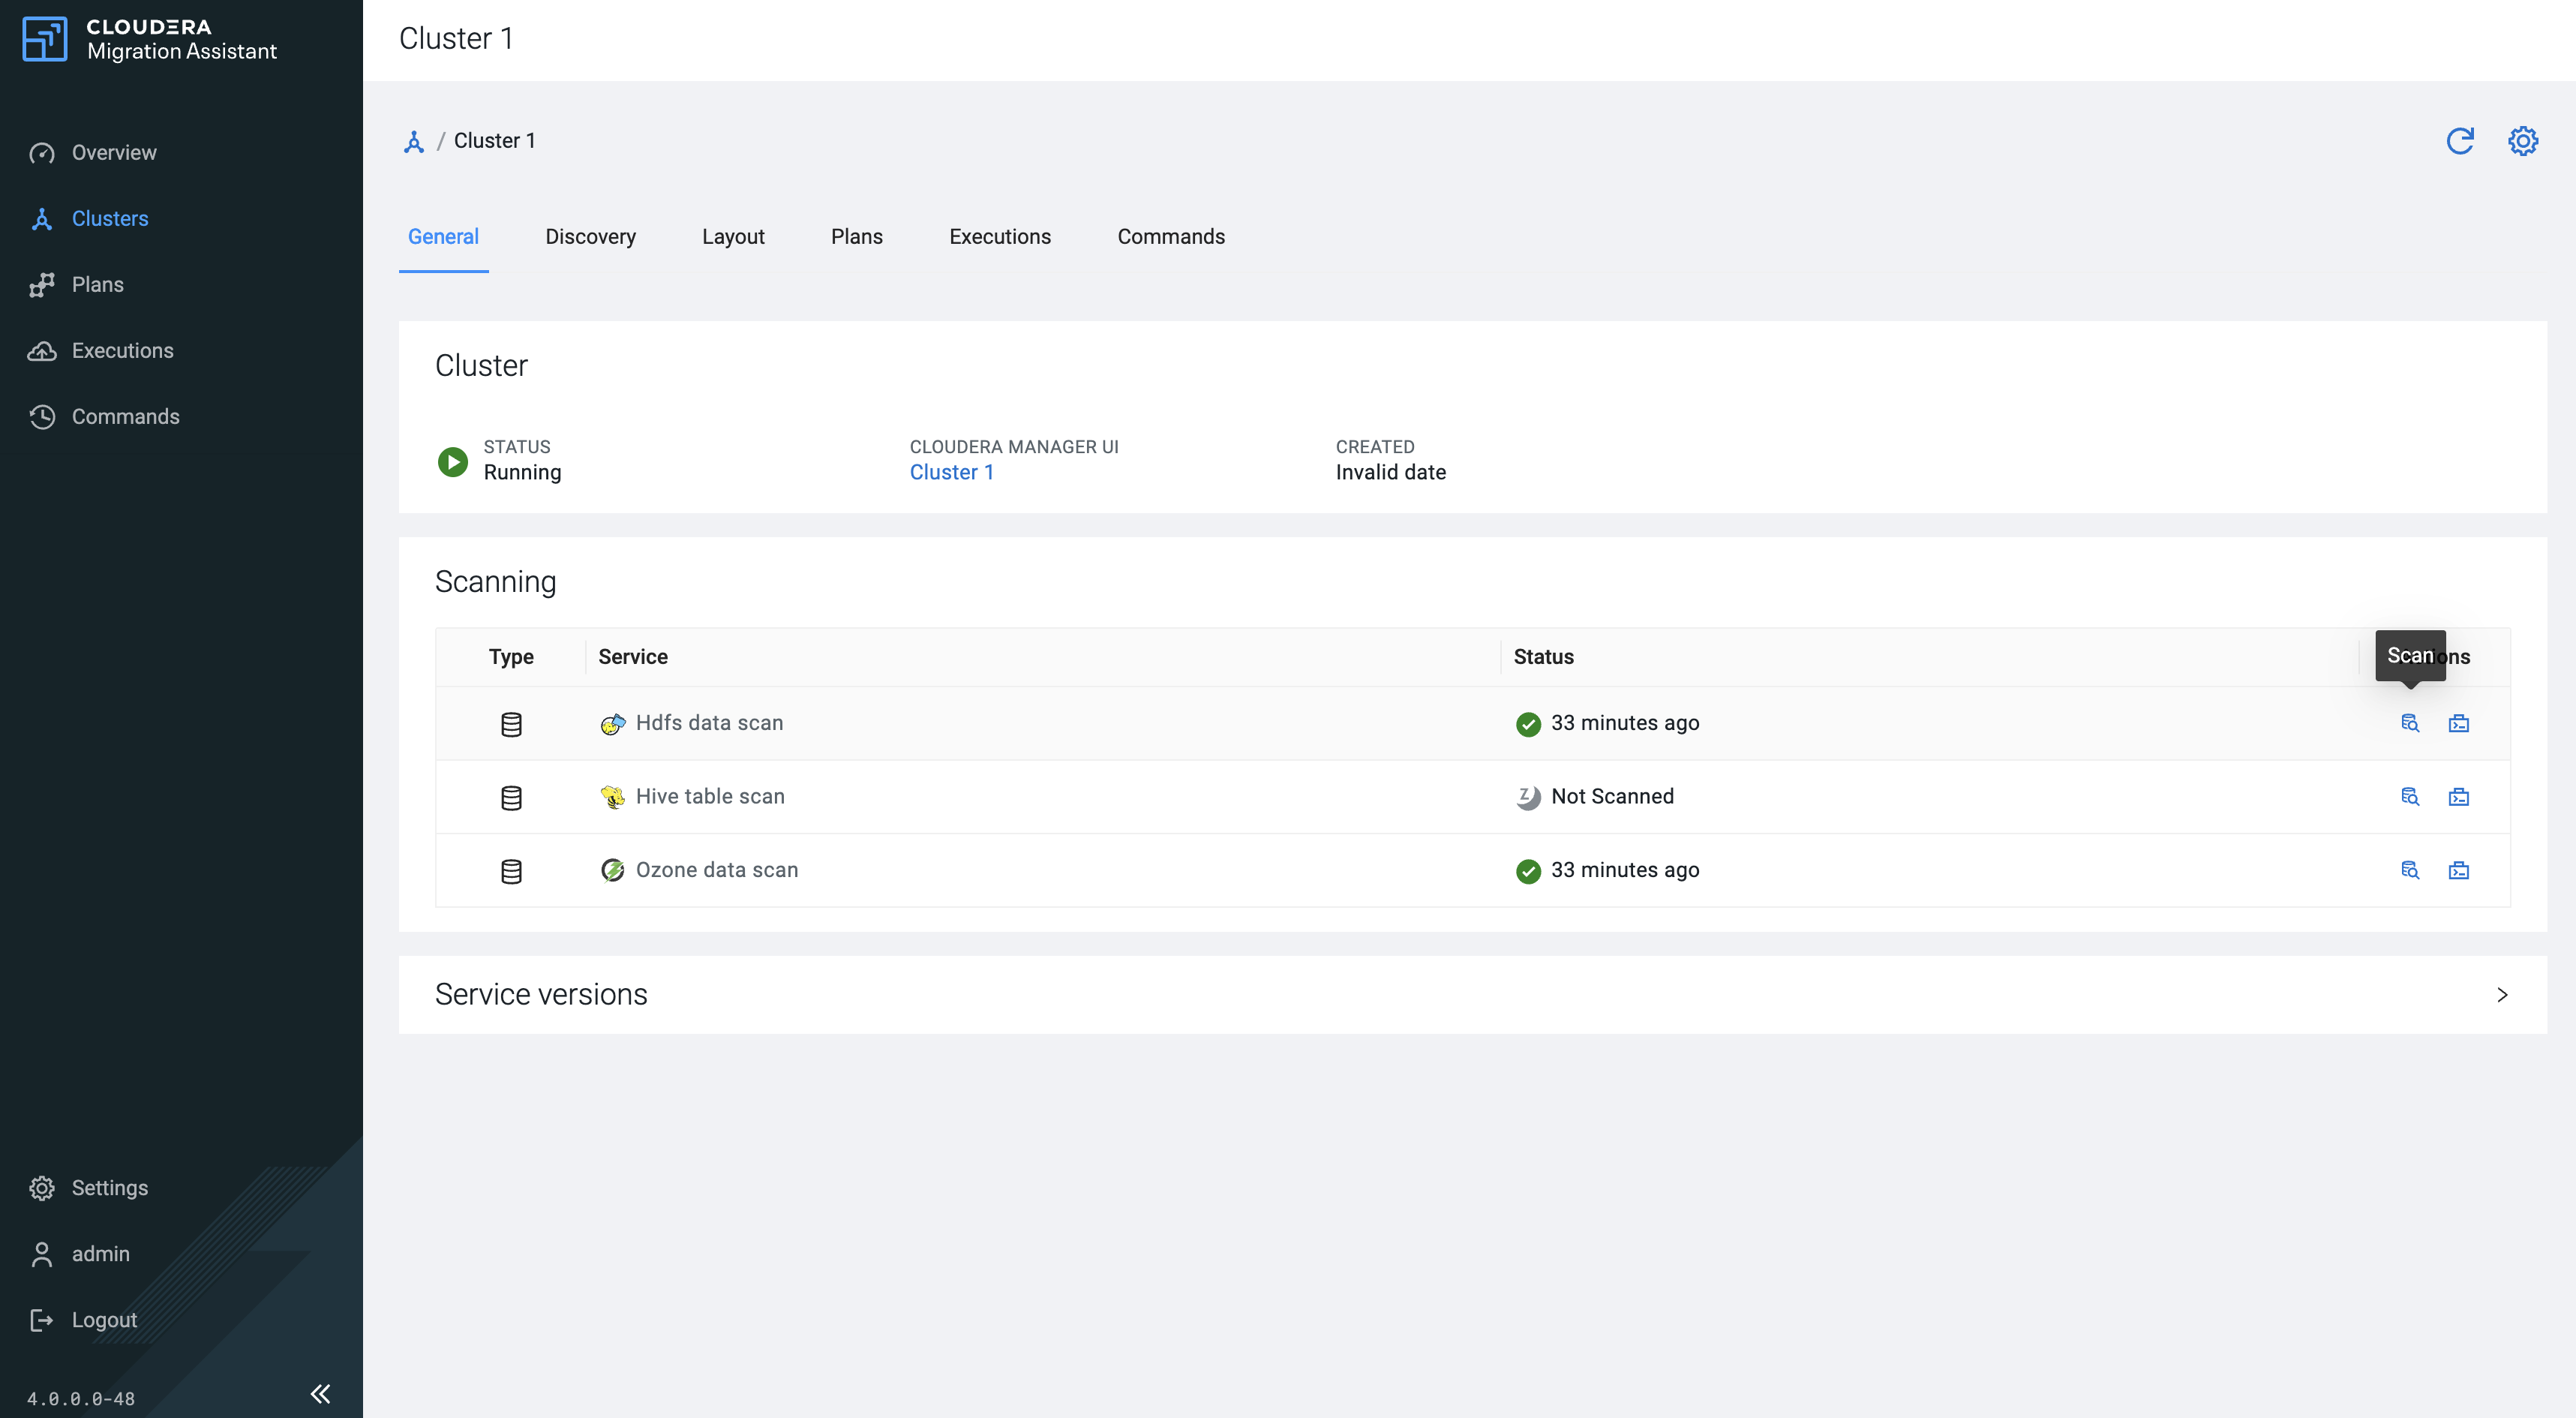
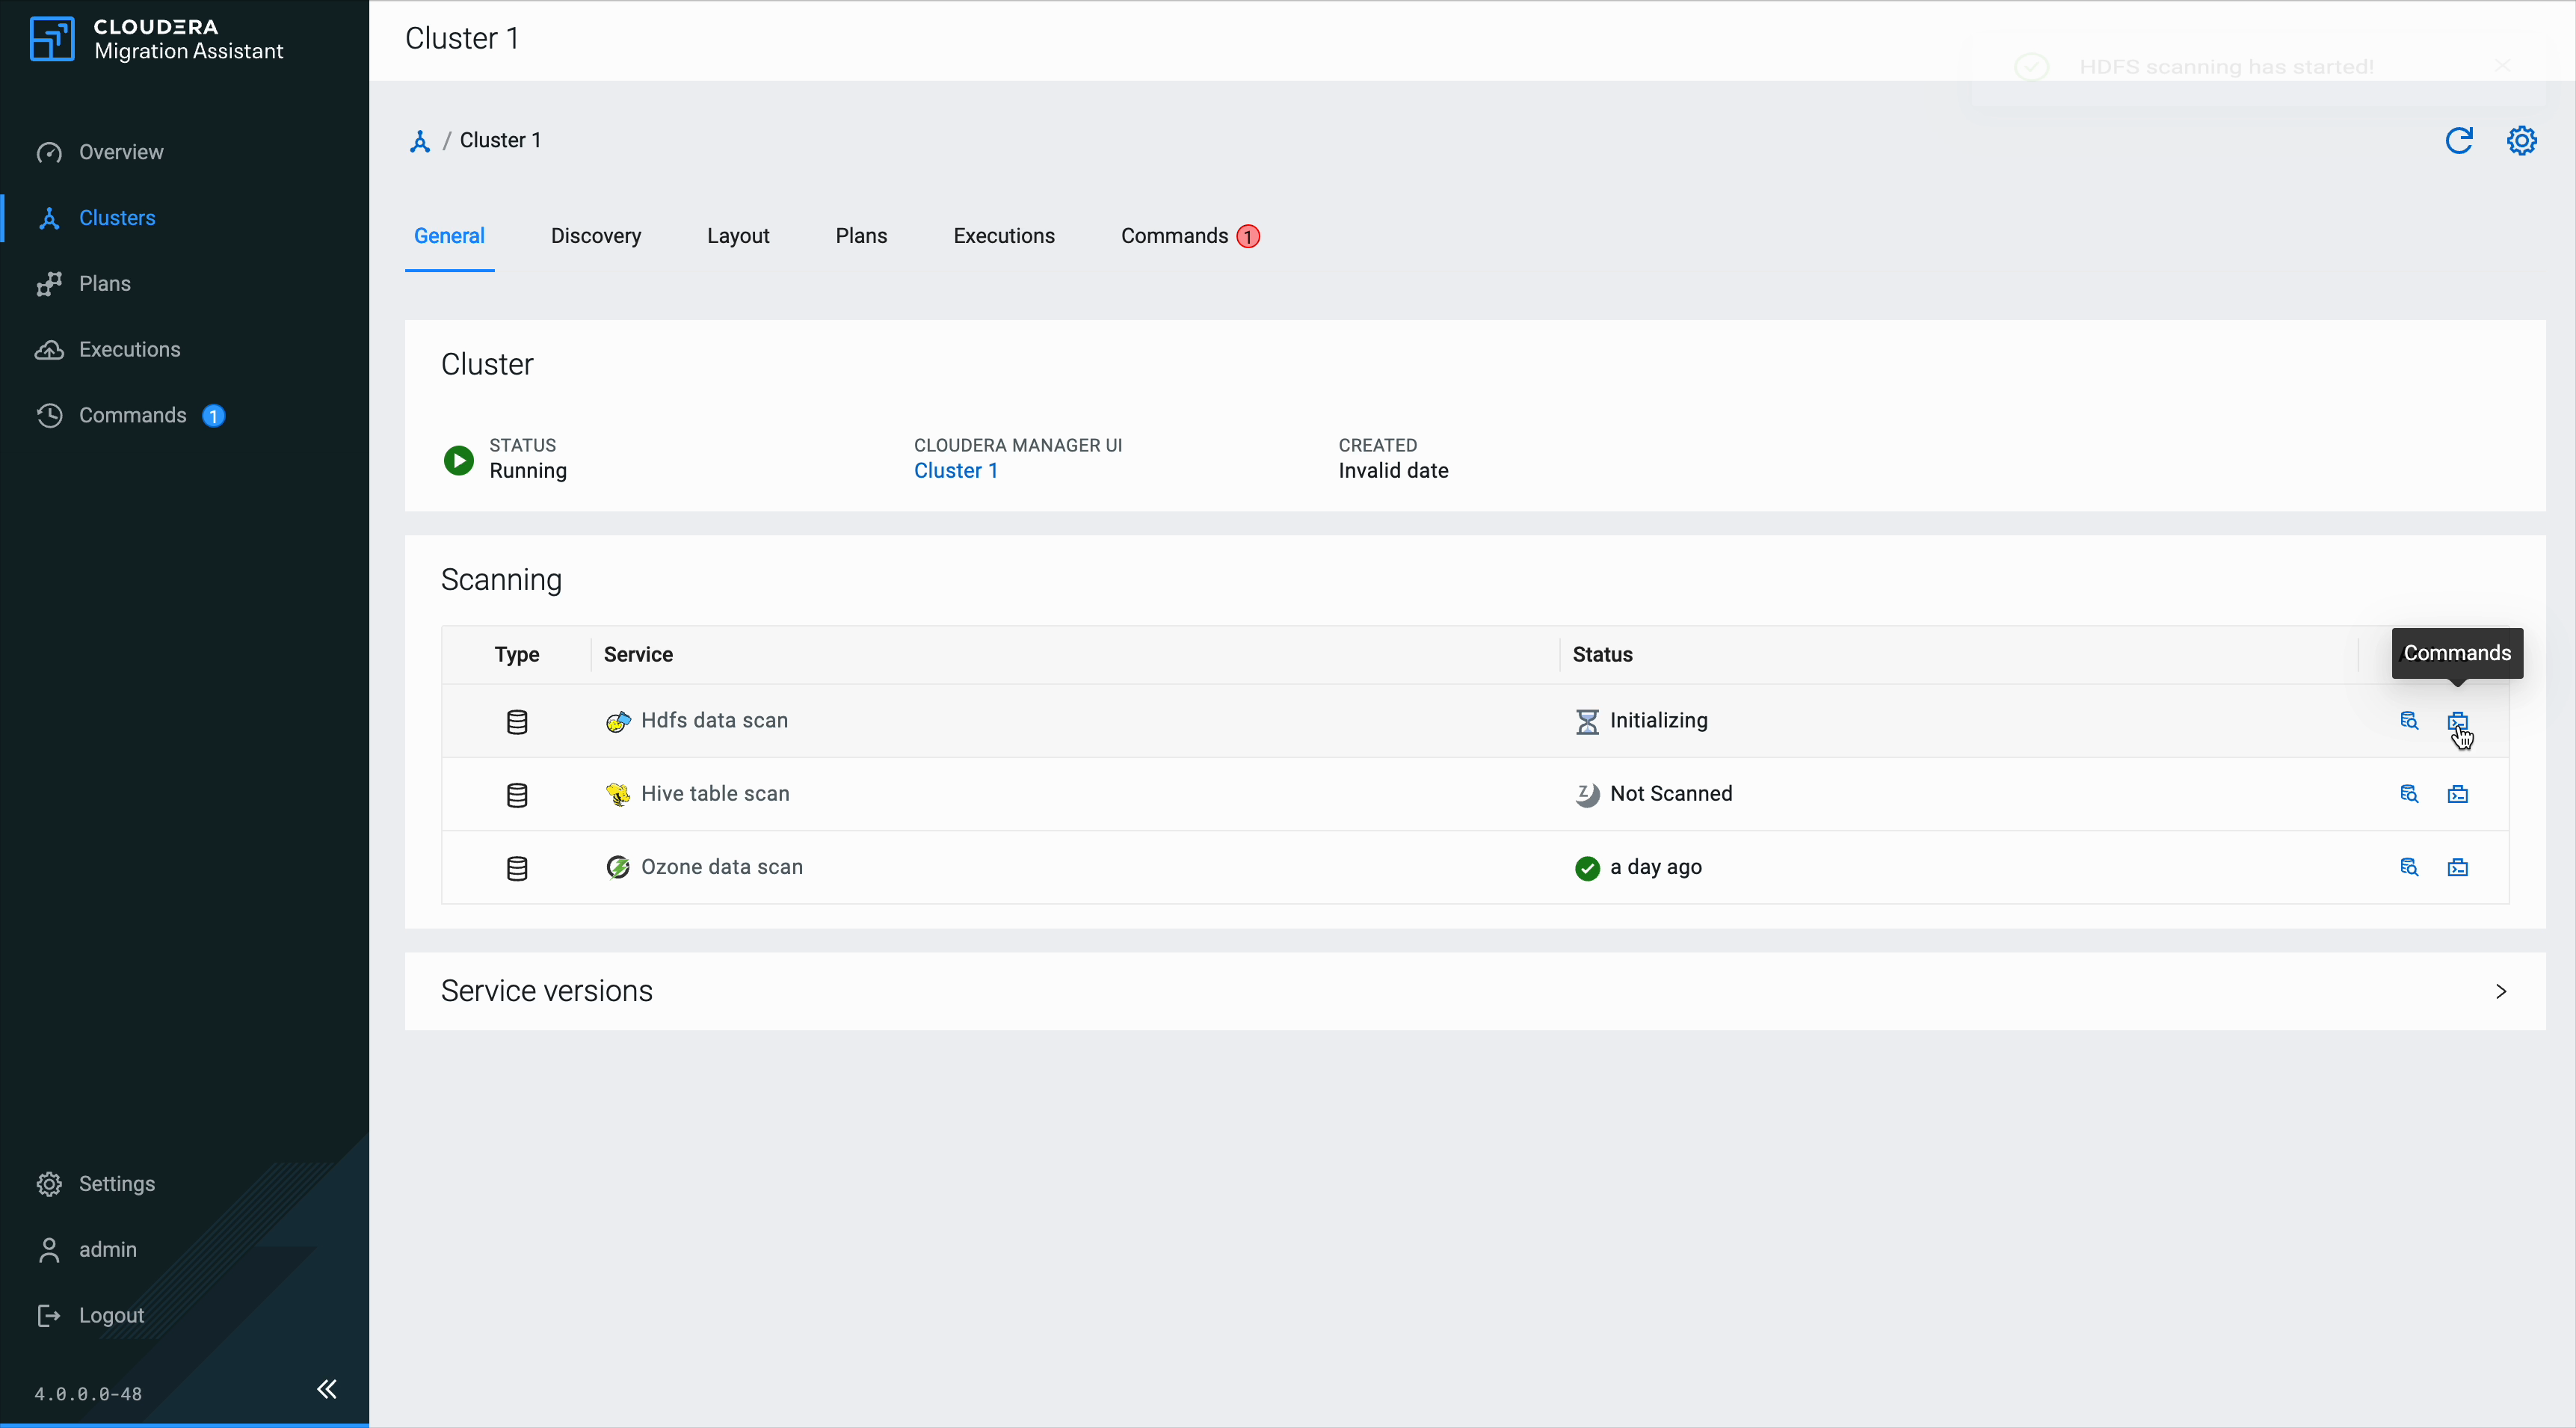
On the cluster detail page, find the Scanning section, which lists the available scan types for your cluster. Click the configuration icon on the right side of the scan type you want to trigger.
Figure 7. cluster scanning
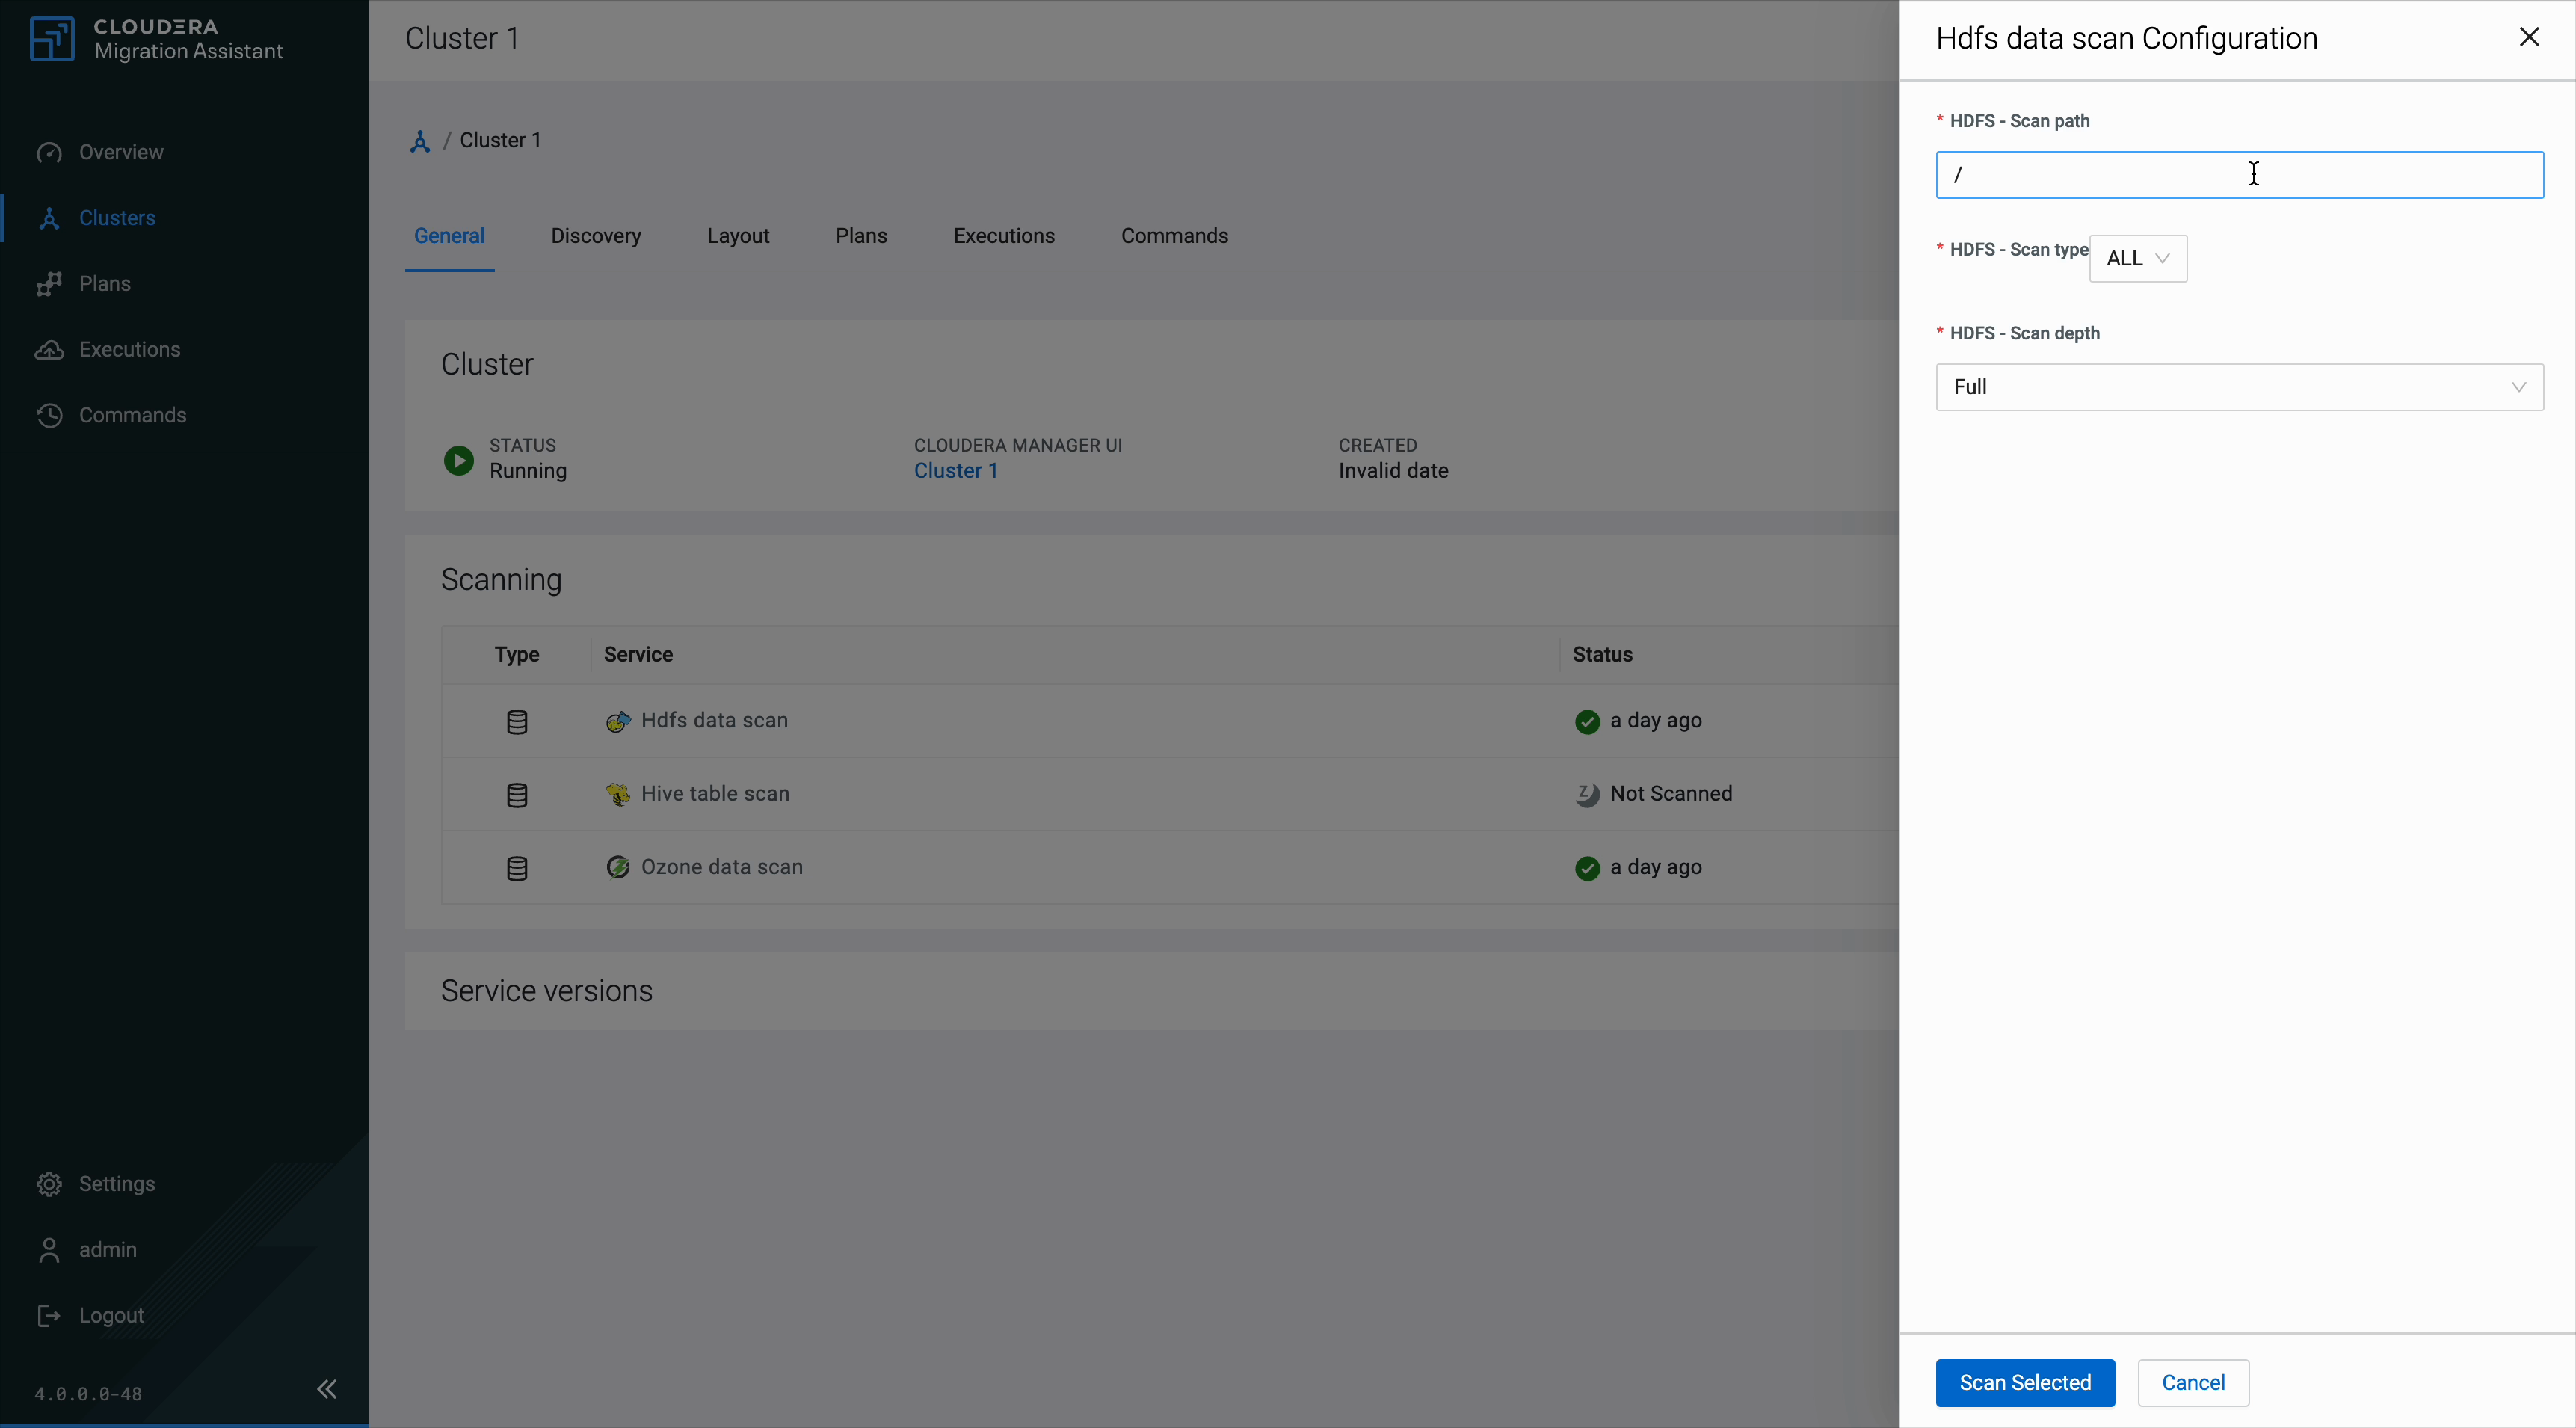
In the scan configuration drawer, configure the scan parameters (for example, scan path, scan type, scan depth) and click Scan Selected.
Figure 8. scan configuration
The scan starts and the status changes to Initializing. Track scan progress by clicking the Commands tab, which shows a badge with the number of active commands.
Figure 9. scan in progress
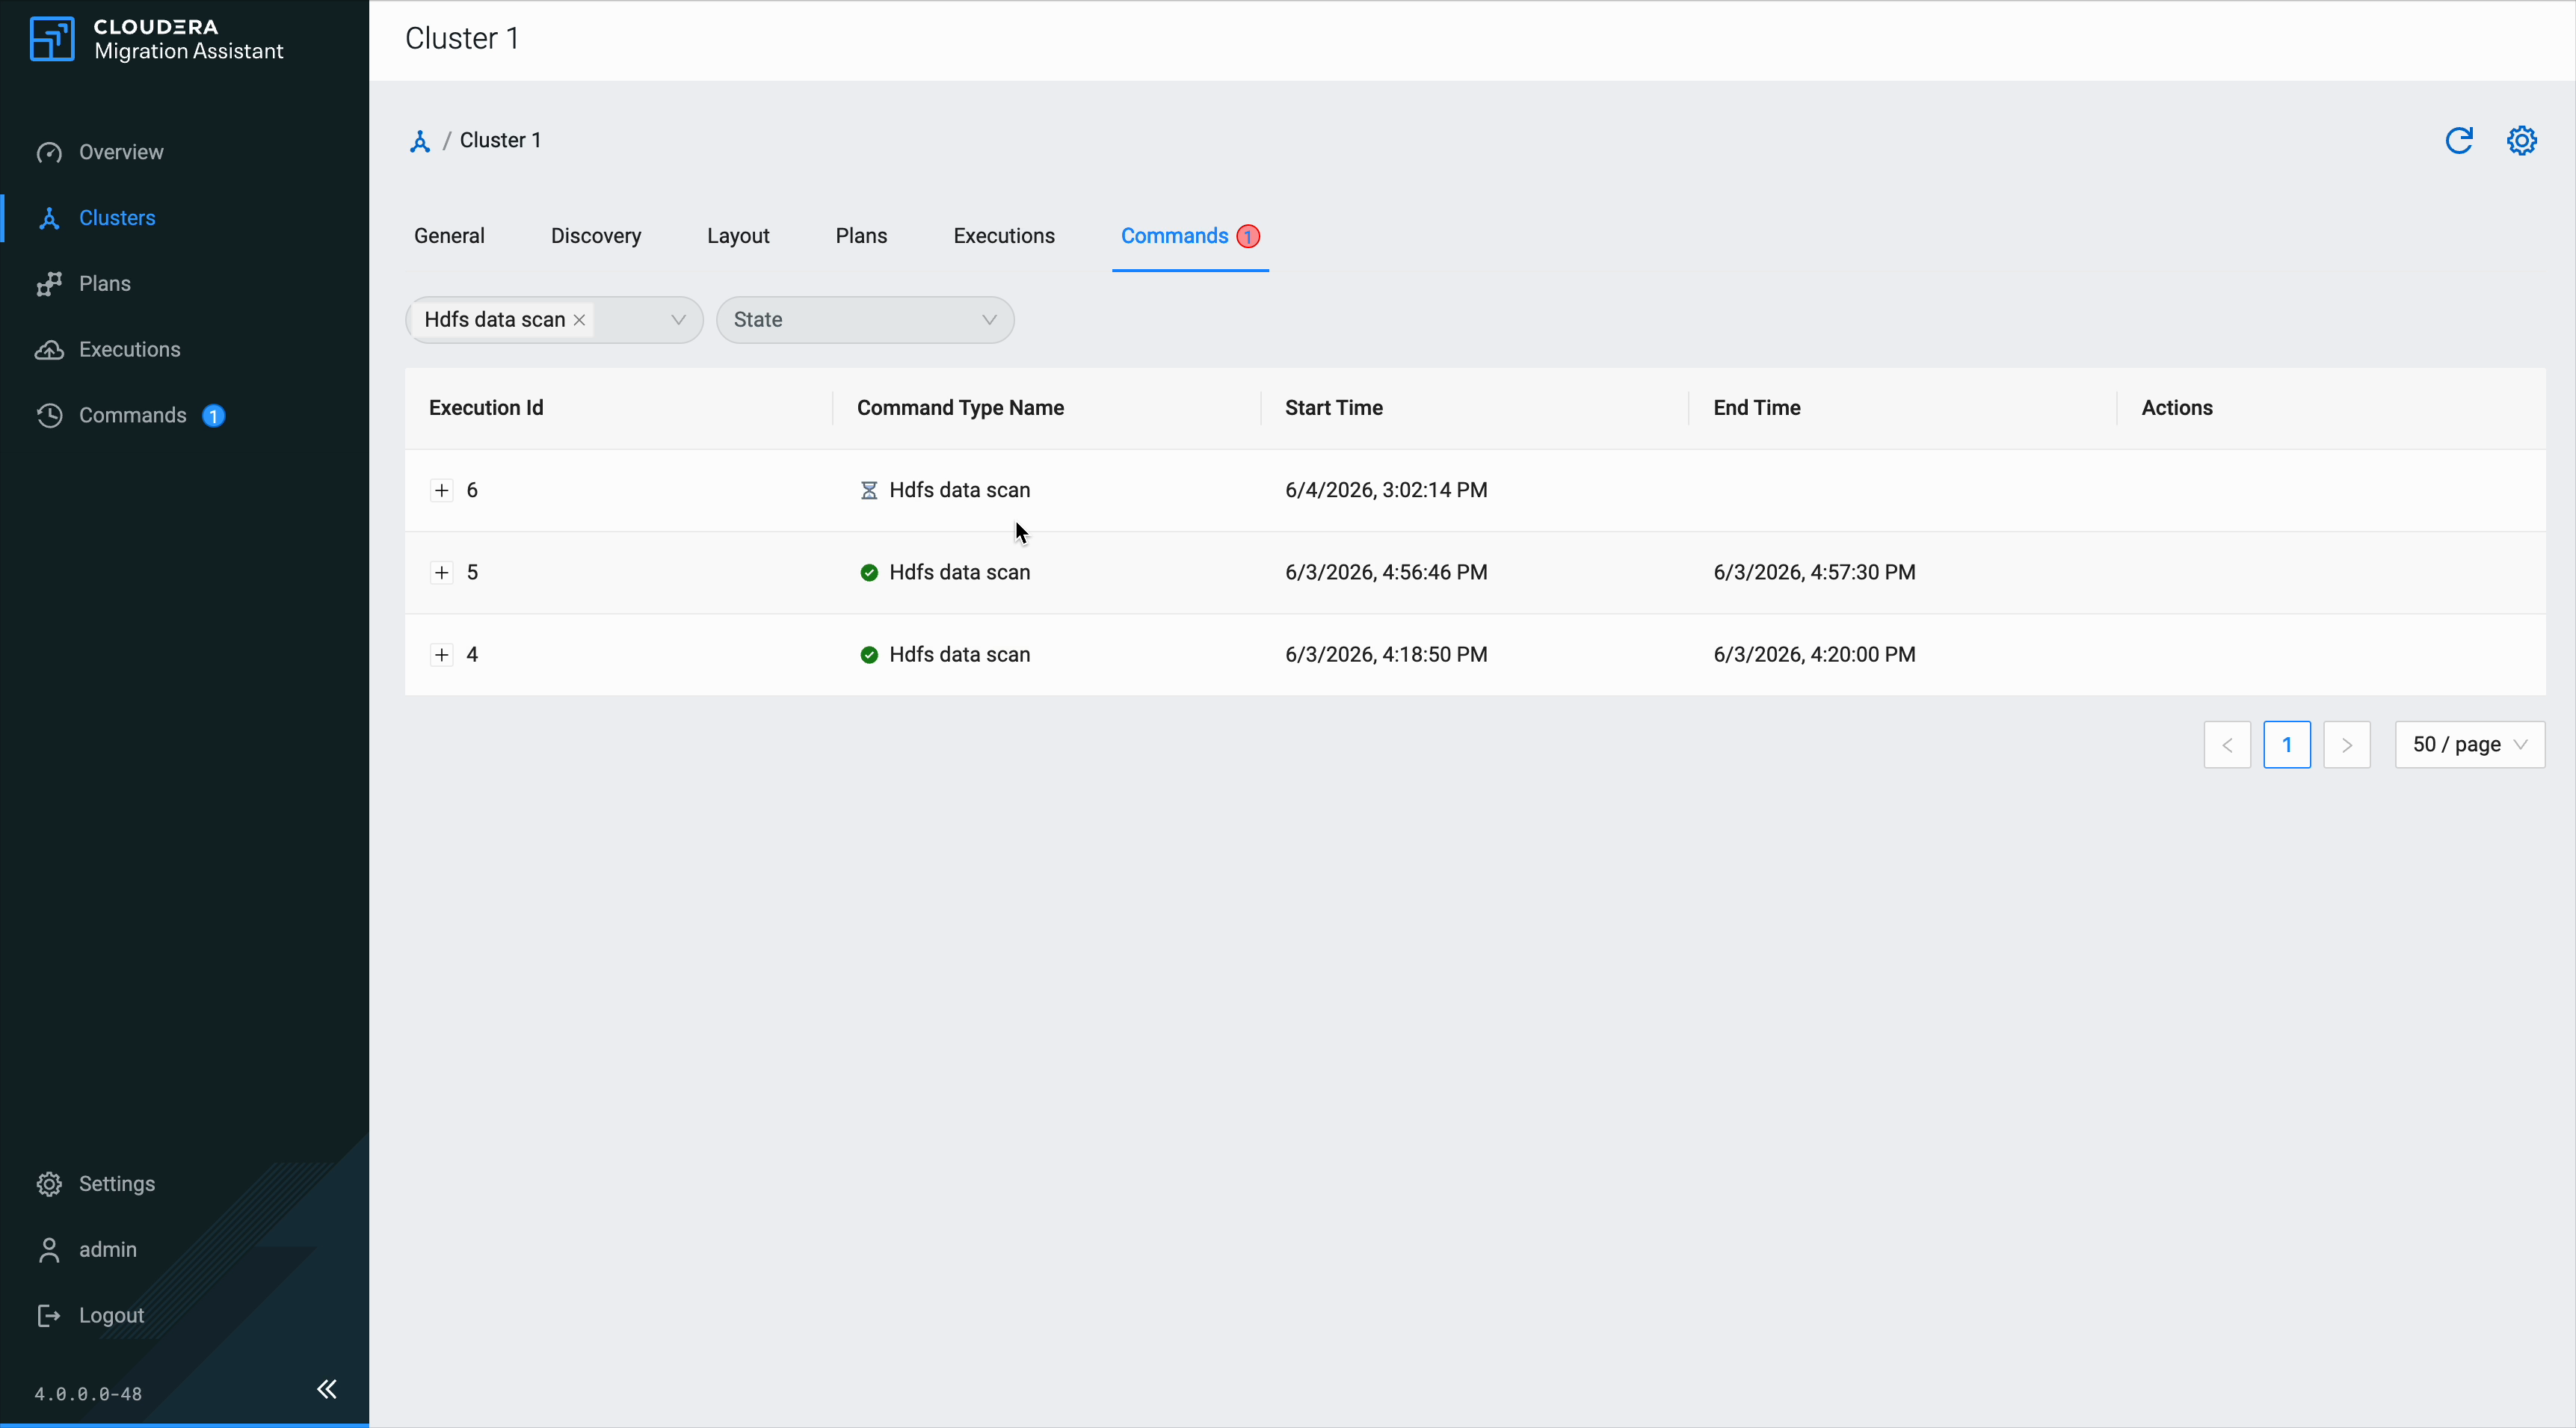
On the Commands tab, expand a command to view its Output Log, Error Log, and Configuration.
Figure 10. scan commands
Phase 5 — Create collections (optional)
Click the + icon next to Collections in the sidebar.
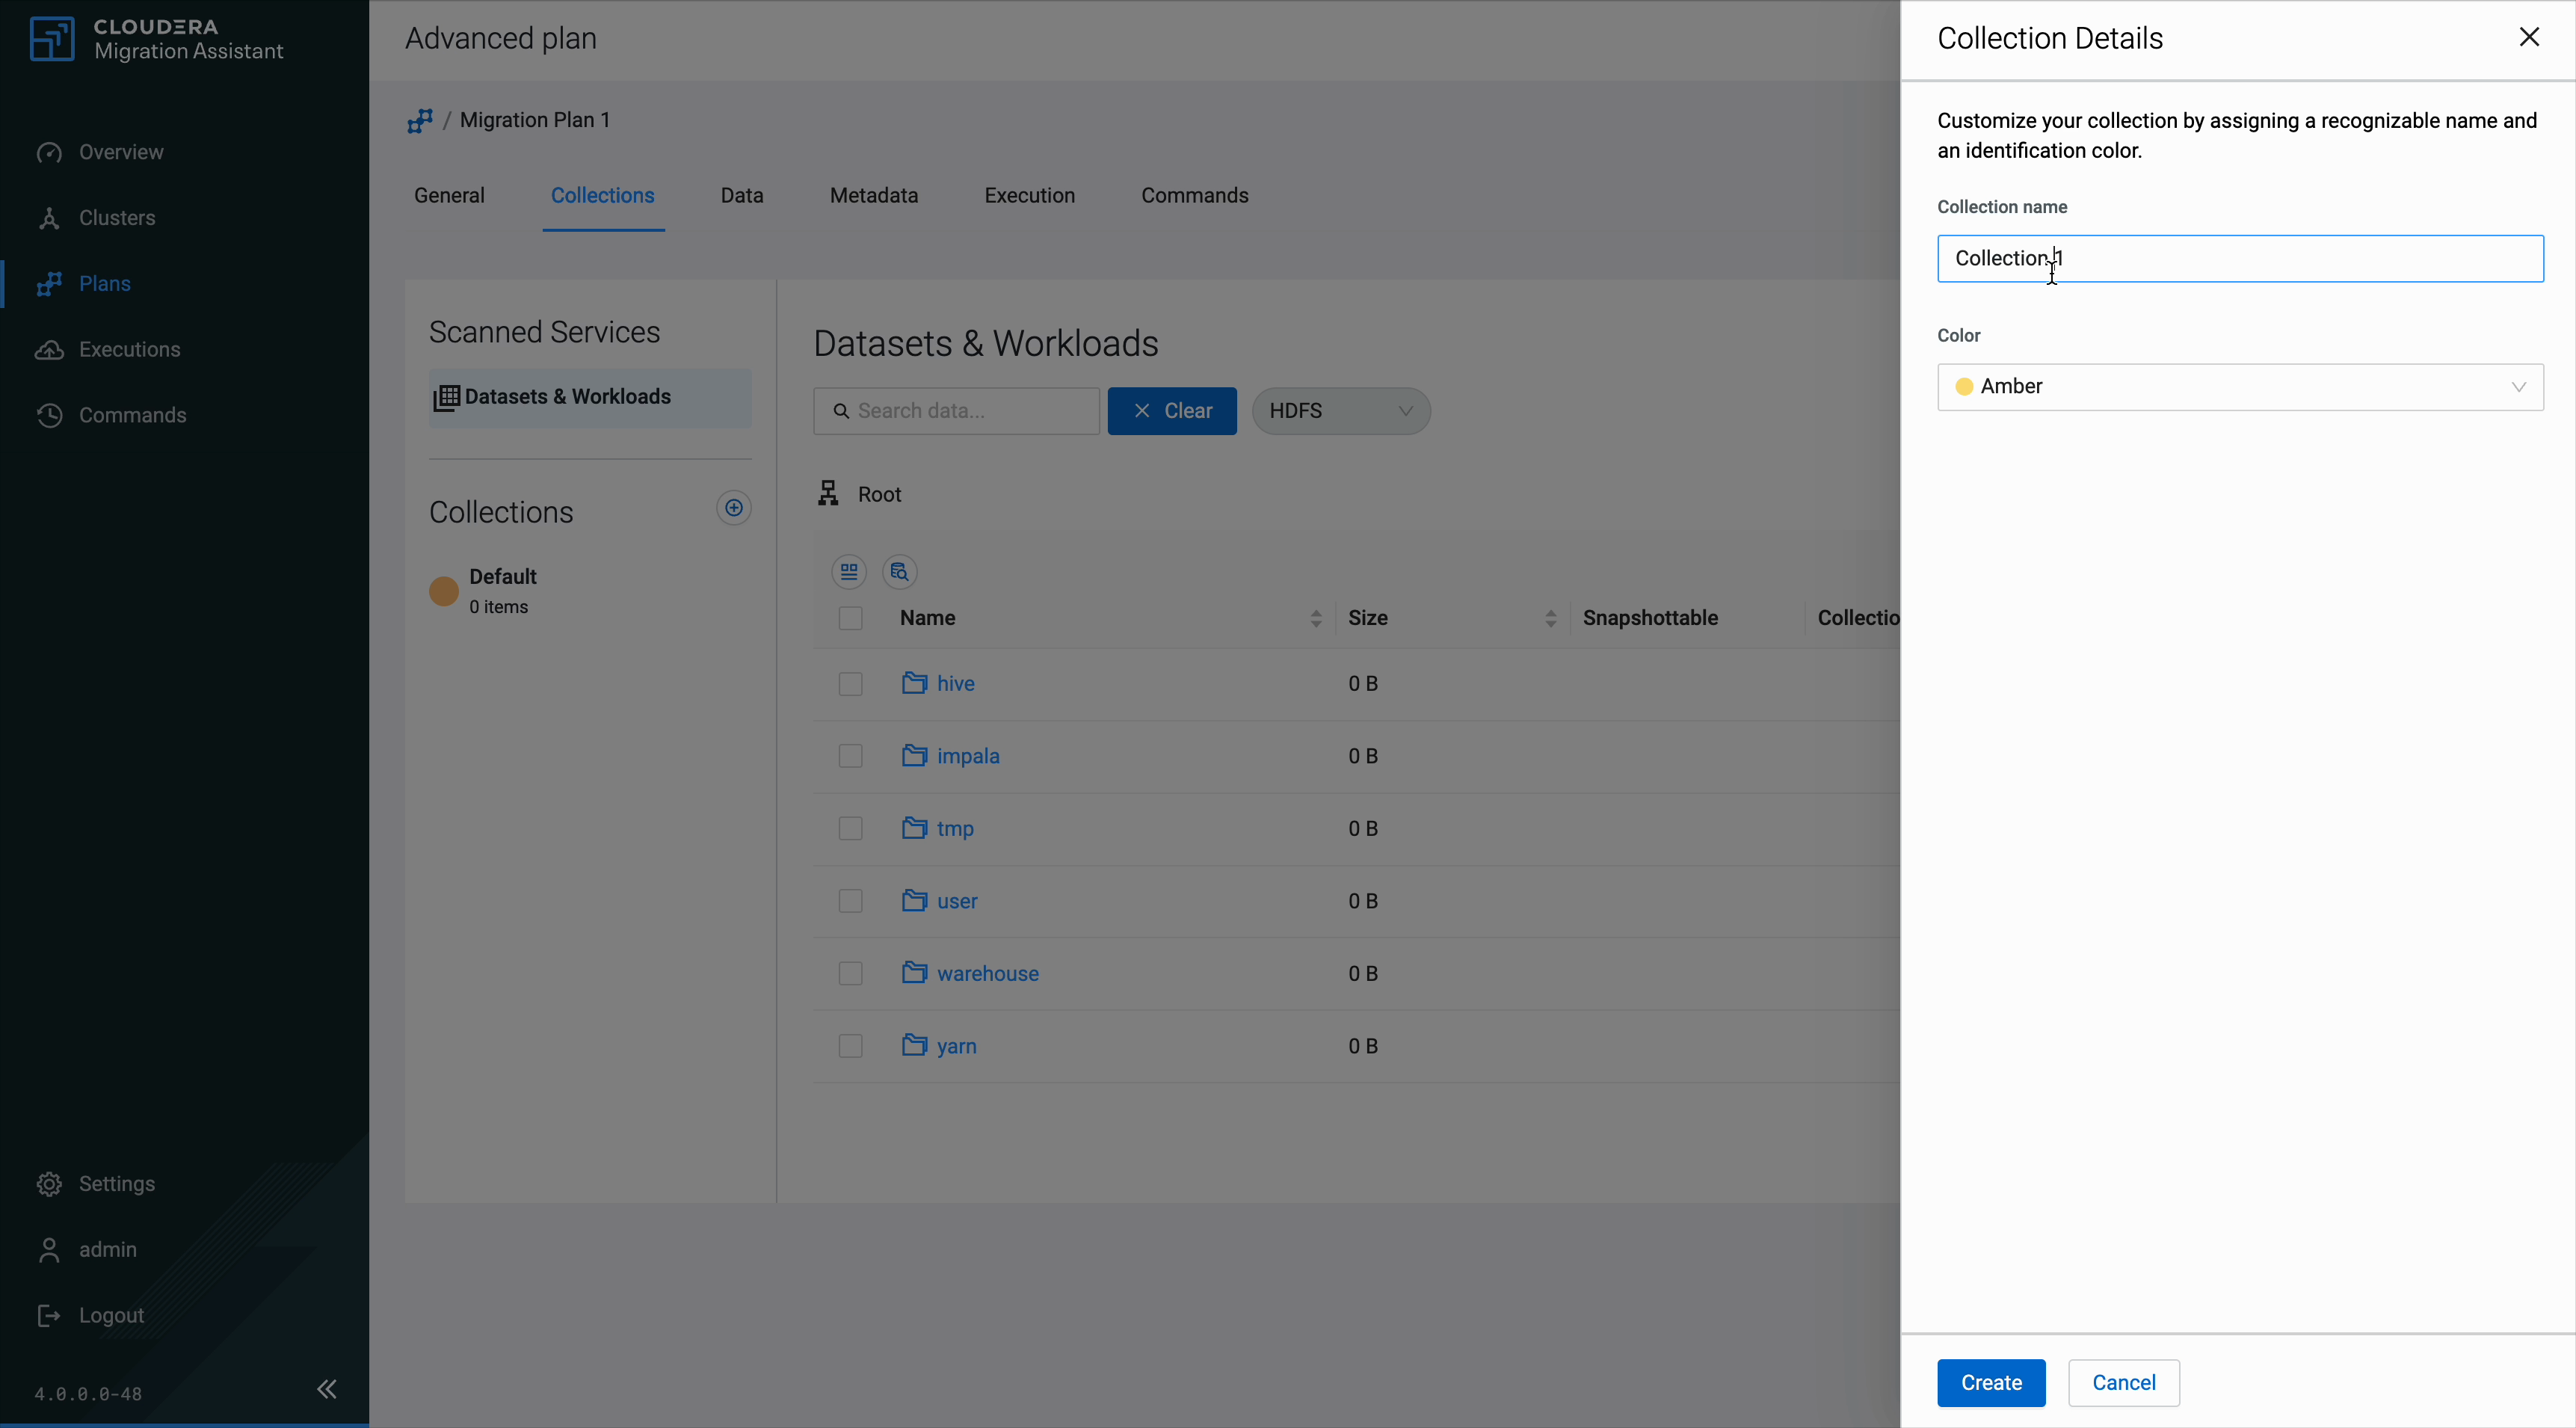
In the Collection Details drawer, enter a Collection name and select a Color for identification.
Figure 11. create collection
Click Create.
The new collection appears in the sidebar with 0 items.
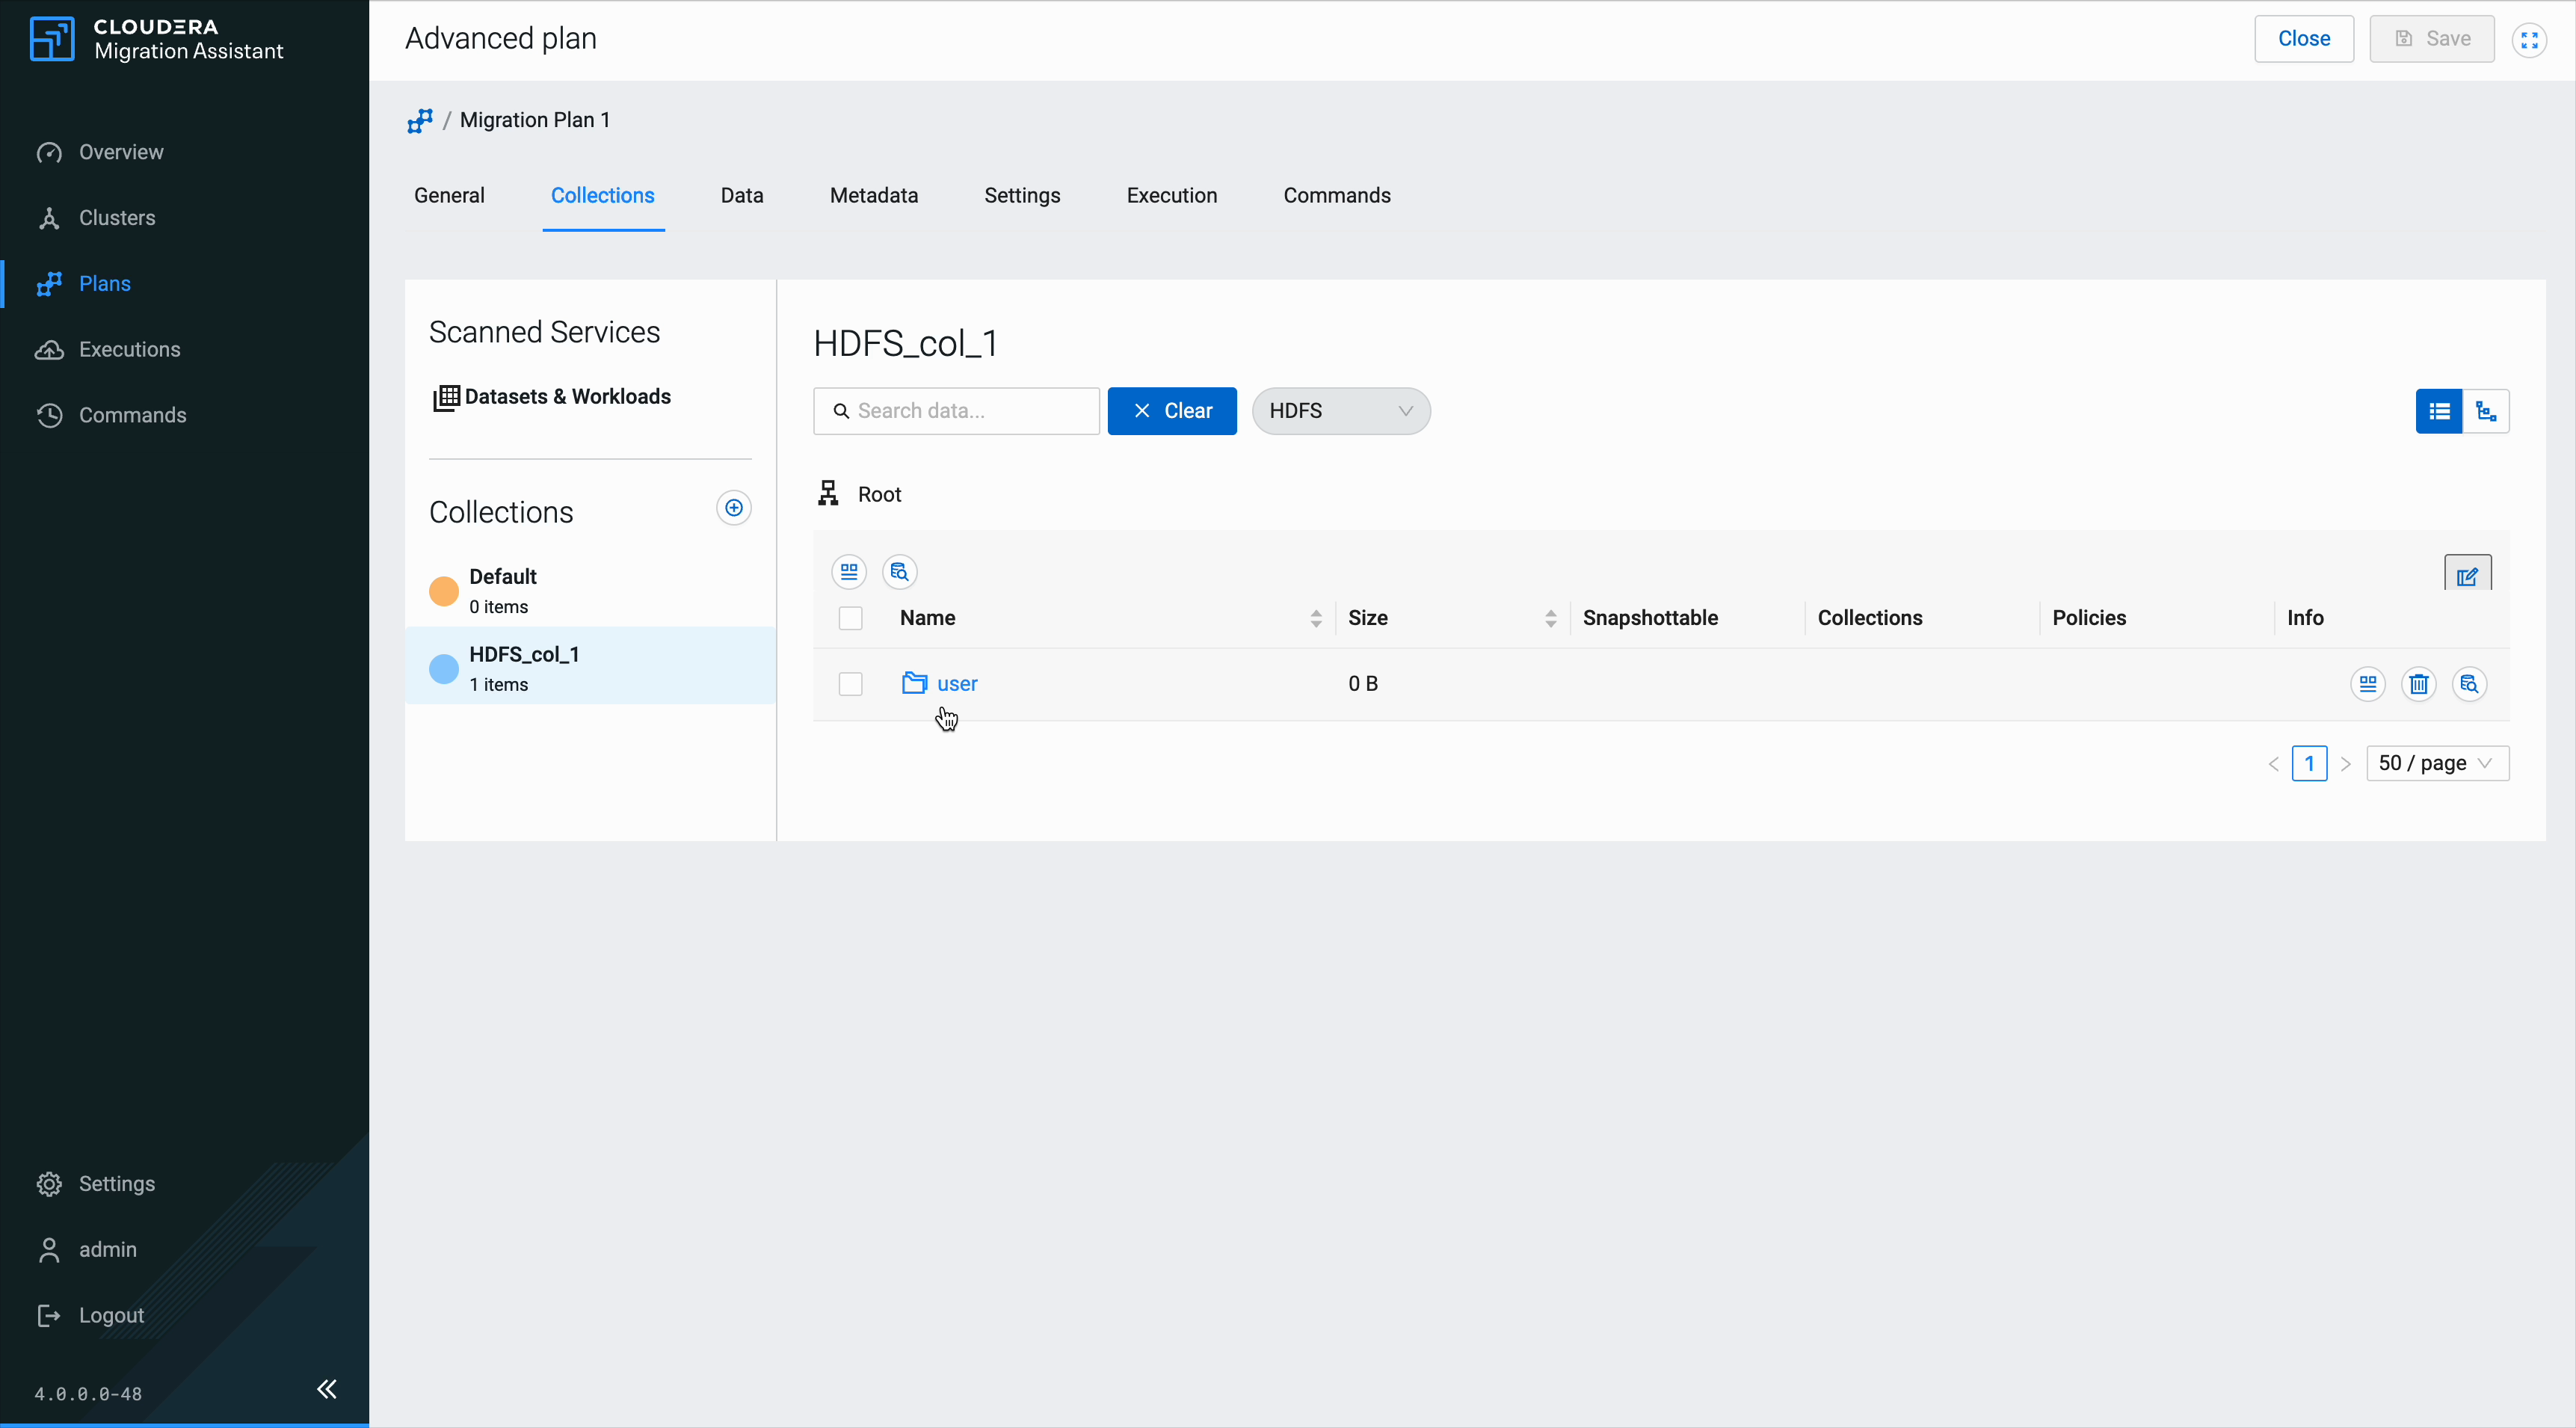
Browse the data tree to find the items you want to migrate. Click folder names to navigate deeper into the hierarchy.
Select items using the checkboxes next to each item.
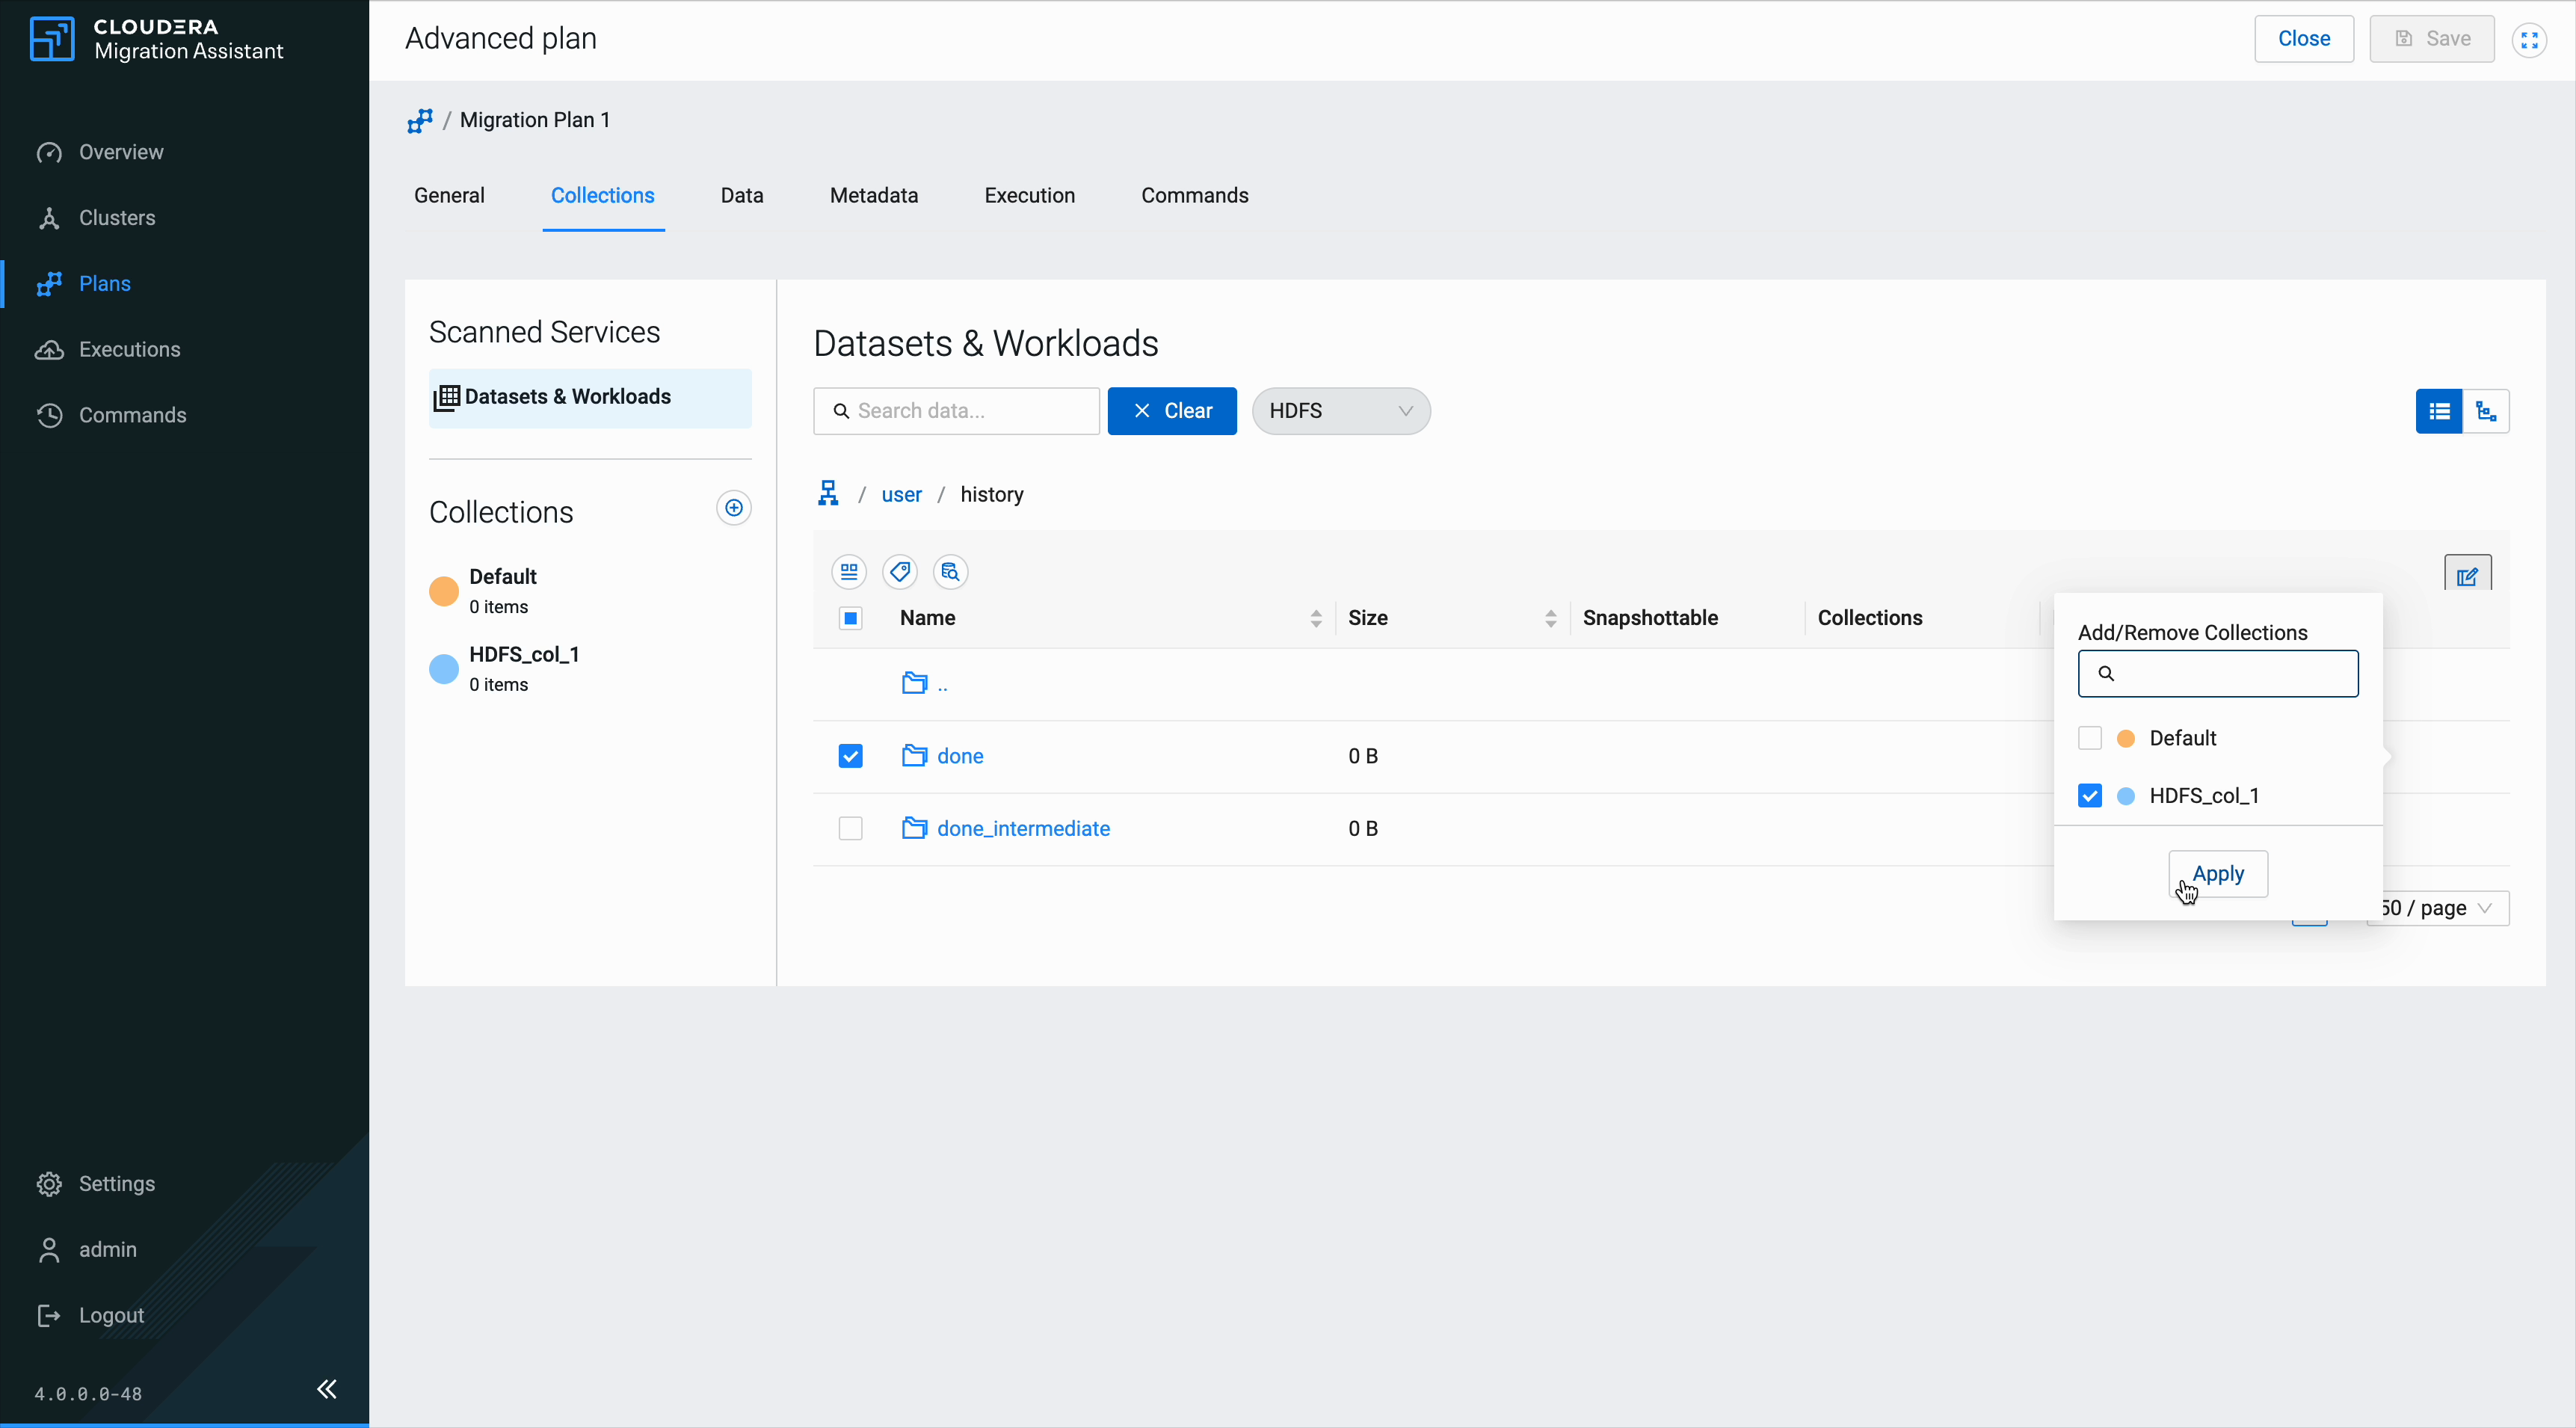
Click the collection icon that appears on the selected item row.
In the Add/Remove Collections popup, check the collections you want to assign the item to.
Click Apply.
Figure 12. assign to collection
Click a collection name in the sidebar to view its contents. The data browser switches to show only the items assigned to that collection.
Figure 13. view collection
Phase 6 — Run the migration workload
Step 1 — Scan the
source
cluster
(HDFS)
Open Clusters, then
select
the source cluster.
Click Start Scanning.
Select
Hdfs data scan.
Optional: Constrain
the scan path,
for example,
/tmp or
/user,
to shorten runs on massive namespaces.
Click Scan selected and watch the progress drawer until
completion.
After success,
Discovery lists HDFS trees with
sizing and ownership snapshots.
Step 2 — Scan the
target
cluster
(HDFS)
From
Clusters,
open the target cluster.
Click Start Scanning.
Select Hdfs data scan.
Click Scan selected and wait until the status turns green.
Set Name, select the source HDFS cluster, and the target HDFS
cluster.
Complete the wizard
(Create) and land on the plan detail
surface.
Step 4 — Map HDFS
directories
to HDFS
paths
on the
Data
tab
The
Data tab
displays
source HDFS on the left and target HDFS on the right.
Go to
Plan > Data.
On the target side, browse to the parent directory that should receive migrated data.
On the source side, go to the parent directory that contains data you want to migrate.
Hover the directory and click
Copy.
persists a structural mapping.
Switch to
the Review
view any
time to
view a list of your
current
structure
mappings.
Repeat the mapping workflow for additional directories whenever you broaden scope.
You can
map
each directory to
separate
target prefixes or combine
them
under shared parents.
The
layout must
meet the
requirements for your tenancy model.
Step 5 — Create and
run
an
execution
Open Execution.
Select
Create Execution.
Complete
the steps in the
configuration
wizard (General, Scope,
Review),
and
then click
Finish.