Deploy Cloudera Migration Assistant, prepare Ozone layout, and run an HDFS to Ozone migration.
This end-to-end workflow combines deployment, platform preparation, discovery, and workload steps. Detailed reference procedures are reused from the Administrator and Migration guides.
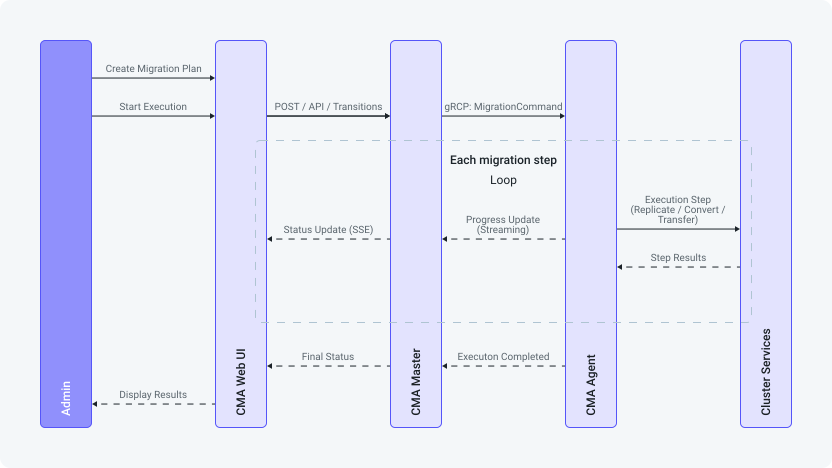
Figure 1. Migration flow
Verify supported platforms and migration paths in Supported platforms and migration paths before you start.
Phase 1 — Deploy the CMA Master and CMA Agents
Download both CSD files to the
/opt/cloudera/csd/ directory on the
Server host.
Click Save & Verify Configuration to commit the
change.
Click Close.
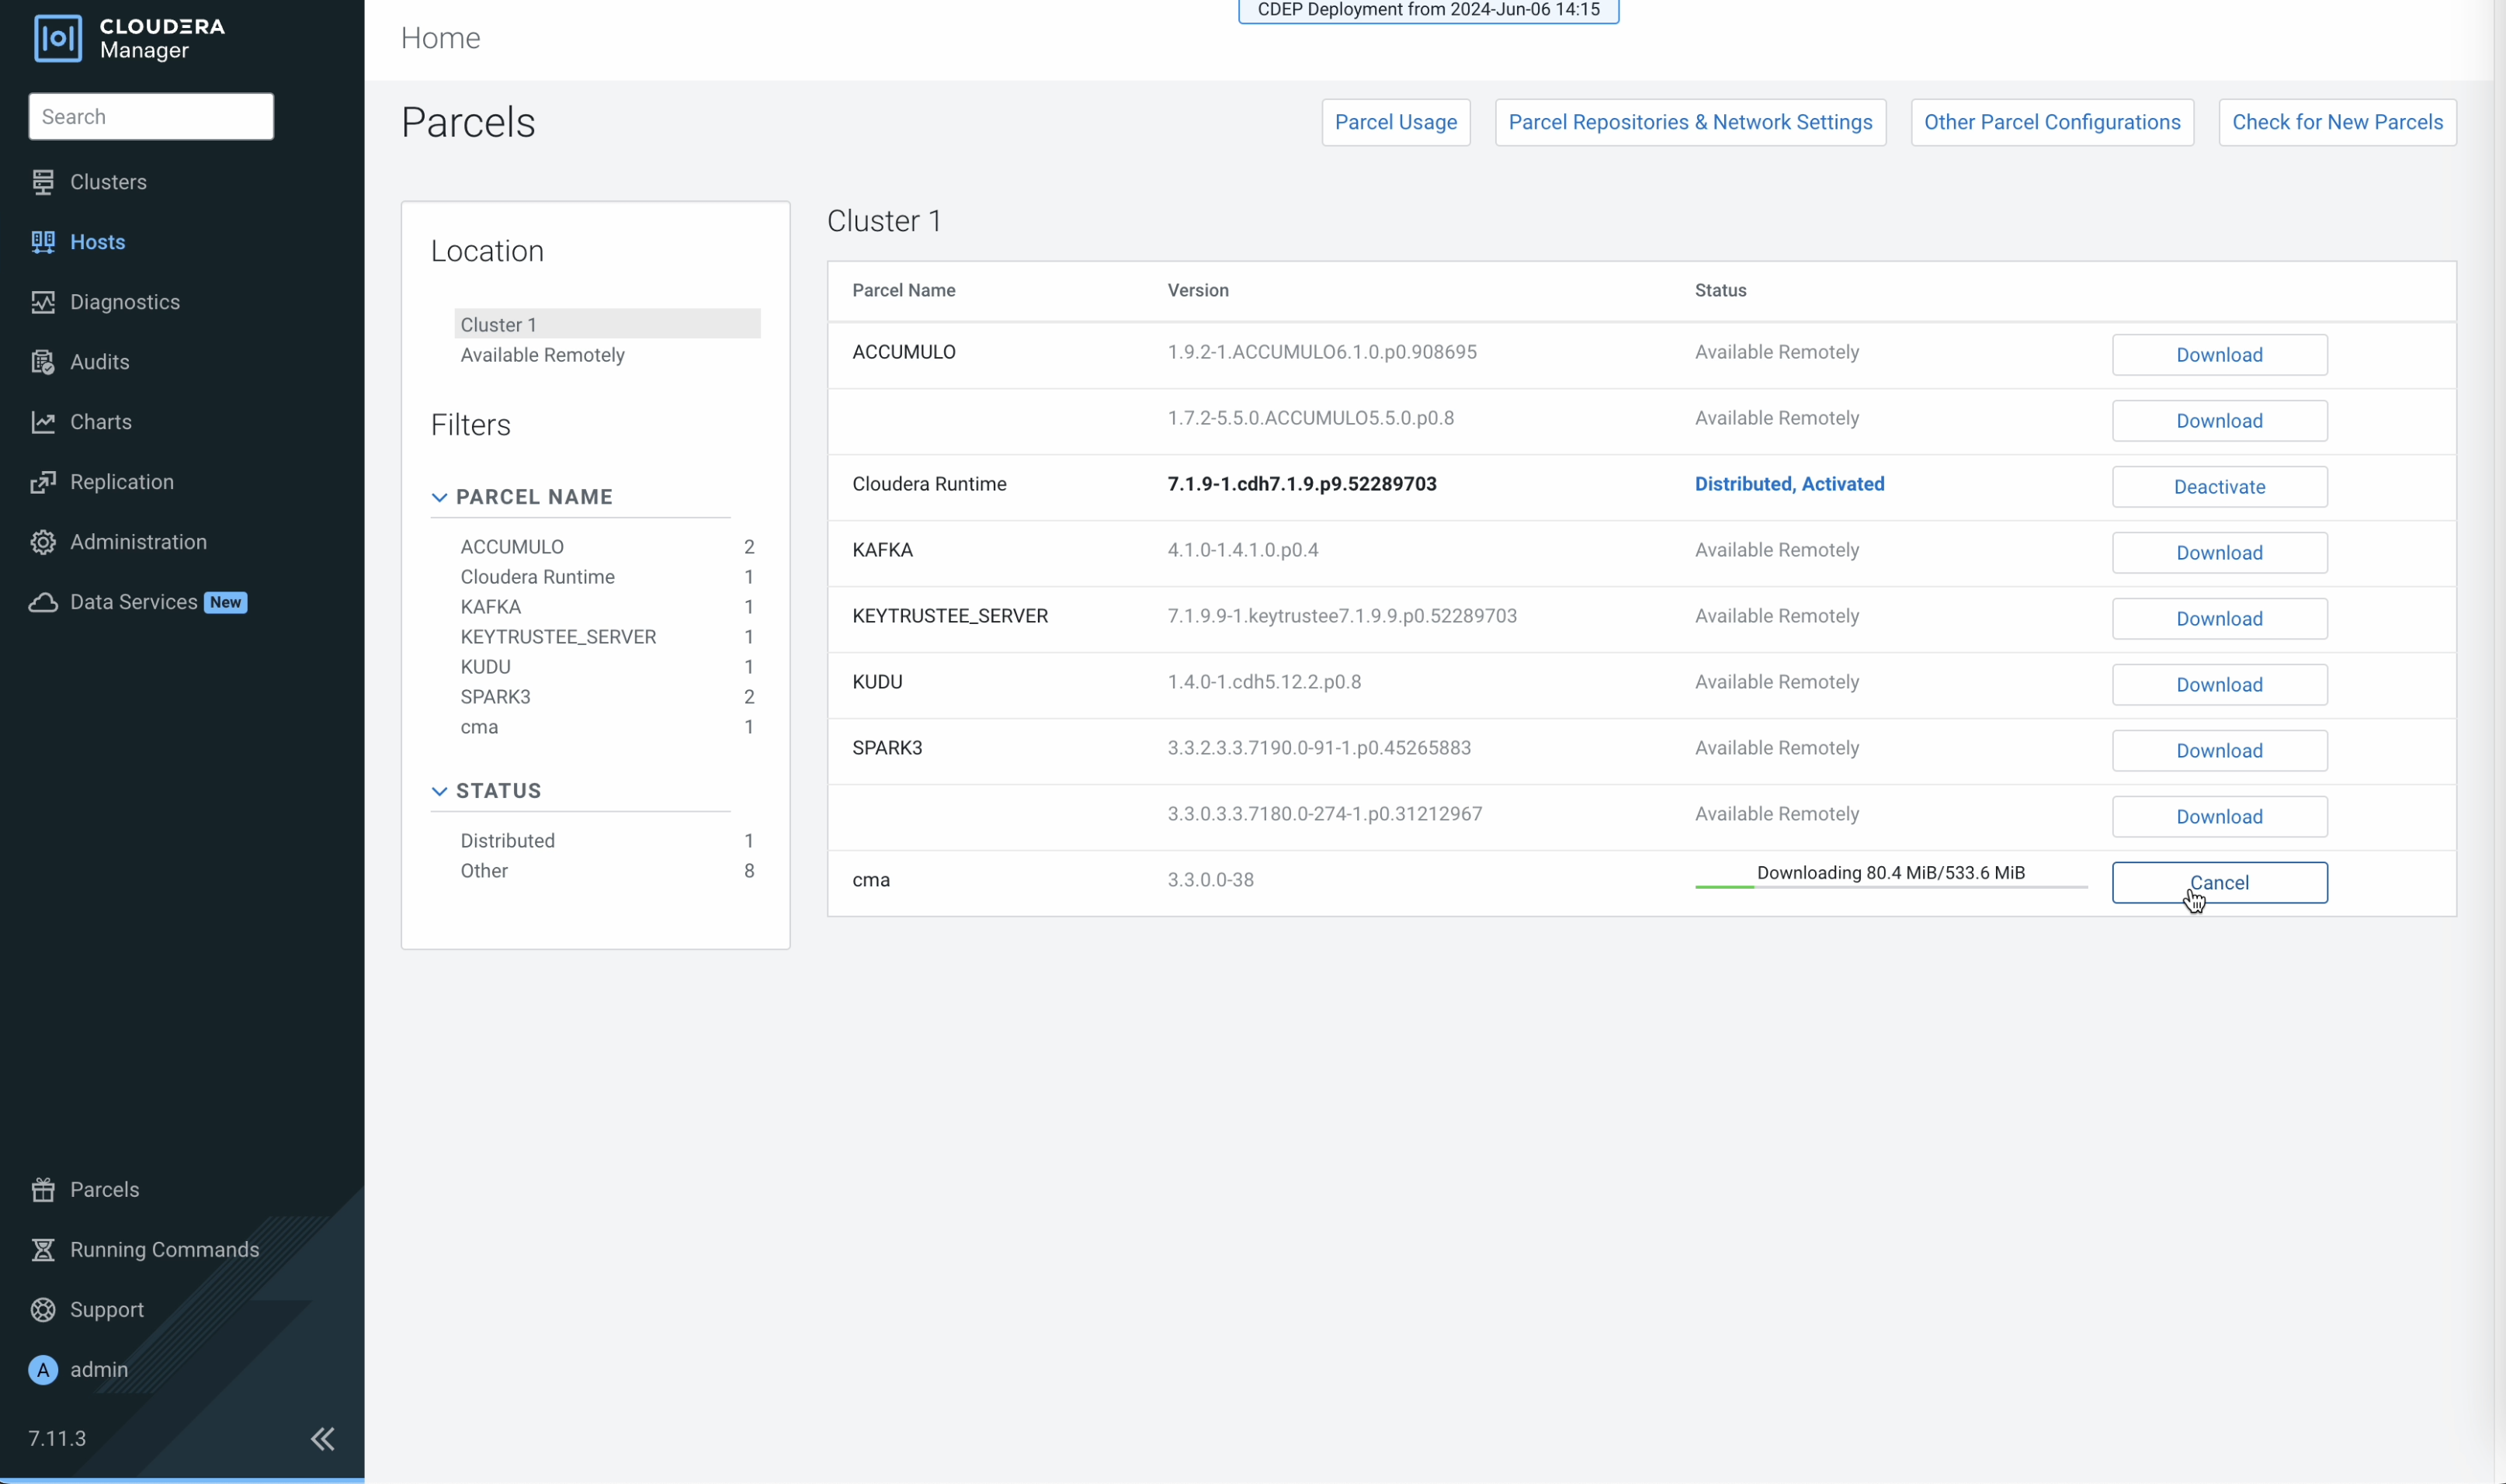
You are redirected to the Parcels page.
Search for , and click
Download
to download the parcel to the local repository.
After download completes, click Distribute to distribute the
parcel to all clusters.
Figure 2. Distribute the parcel
Click
Activate
to activate the parcel.
Click
OK
when confirmation is required.
Click
Clusters
in
the left navigation pane.
Select
Add
Service from the drop-down menu to the right of your
cluster.
From the list, select the service type to add,
then click Continue. The single
parcel provides two service types: CMA_MASTER (central control node) and
CMA_AGENT (cluster-side executor).
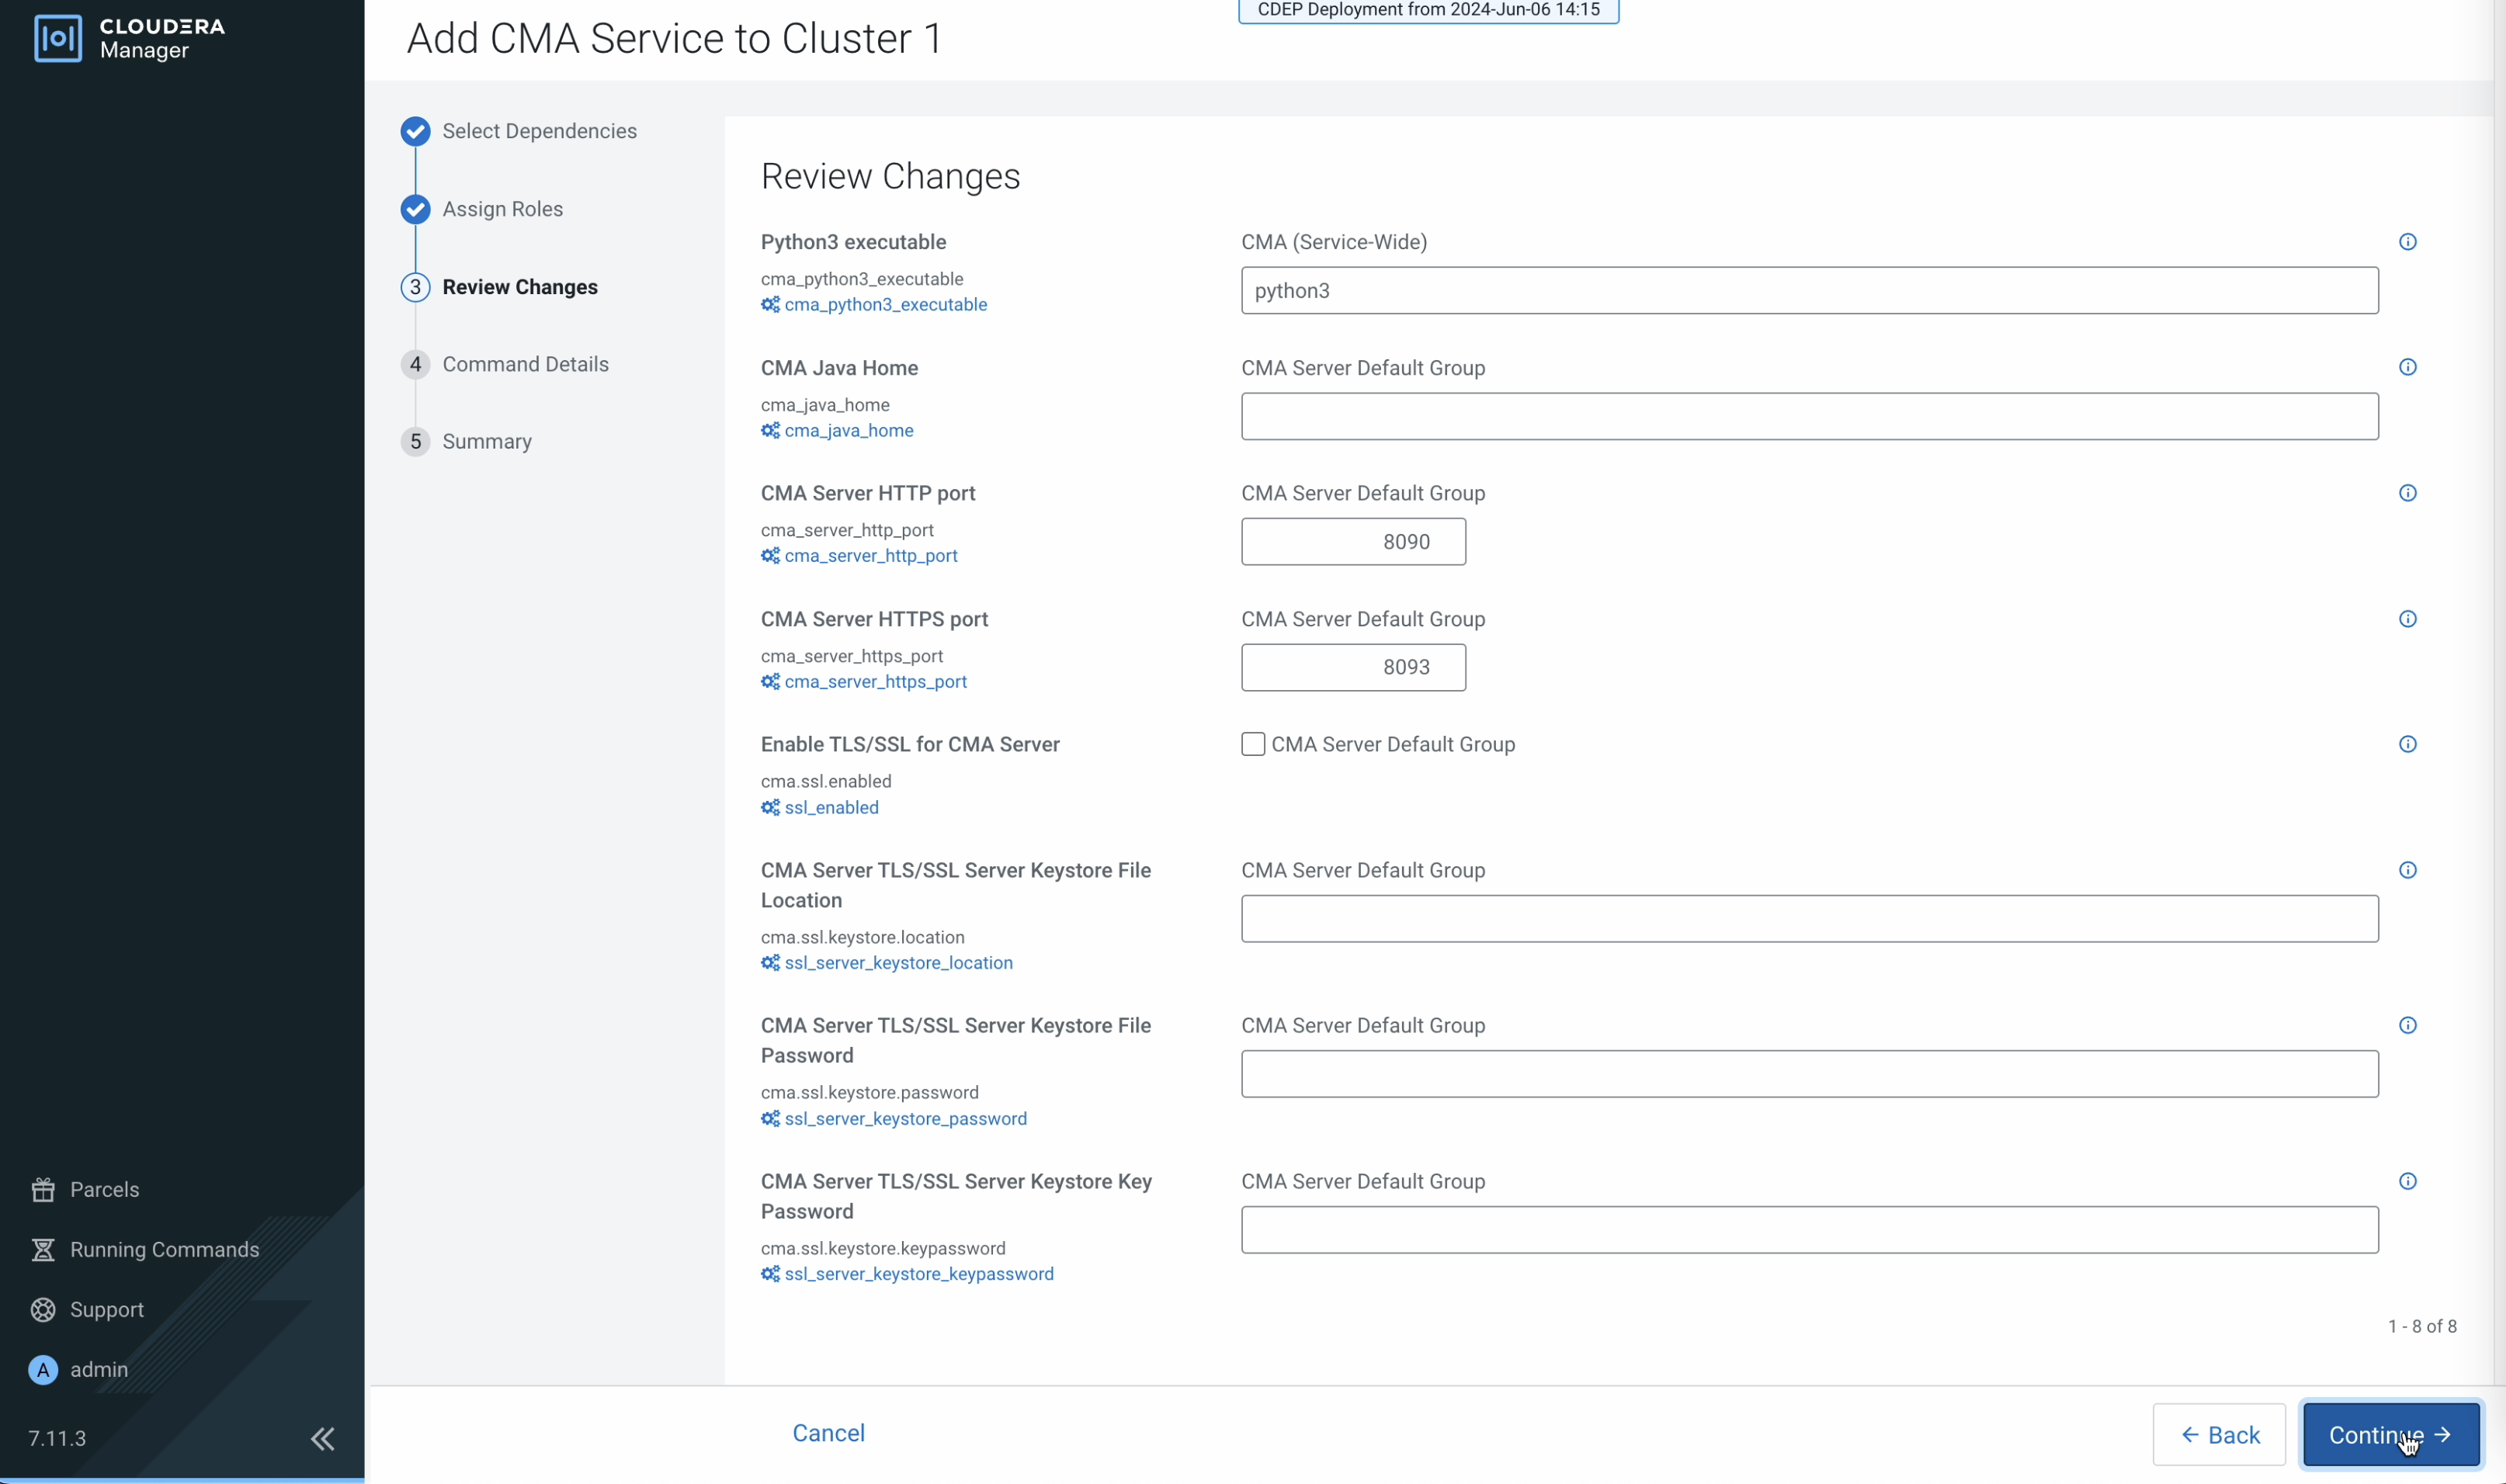
The Add Service wizard opens.
Figure 3. Add service
Assign the service roles to the hosts where Python 3.11 and JDK 17+ are installed, and
click
Continue.
Review service configurations and click Continue. At minimum, set
OAuth2 client credentials (cma_client_secret,
cma_agent_client_secret). If the is on a different cluster from the , also set Gateway URL
(cma_gateway_url).
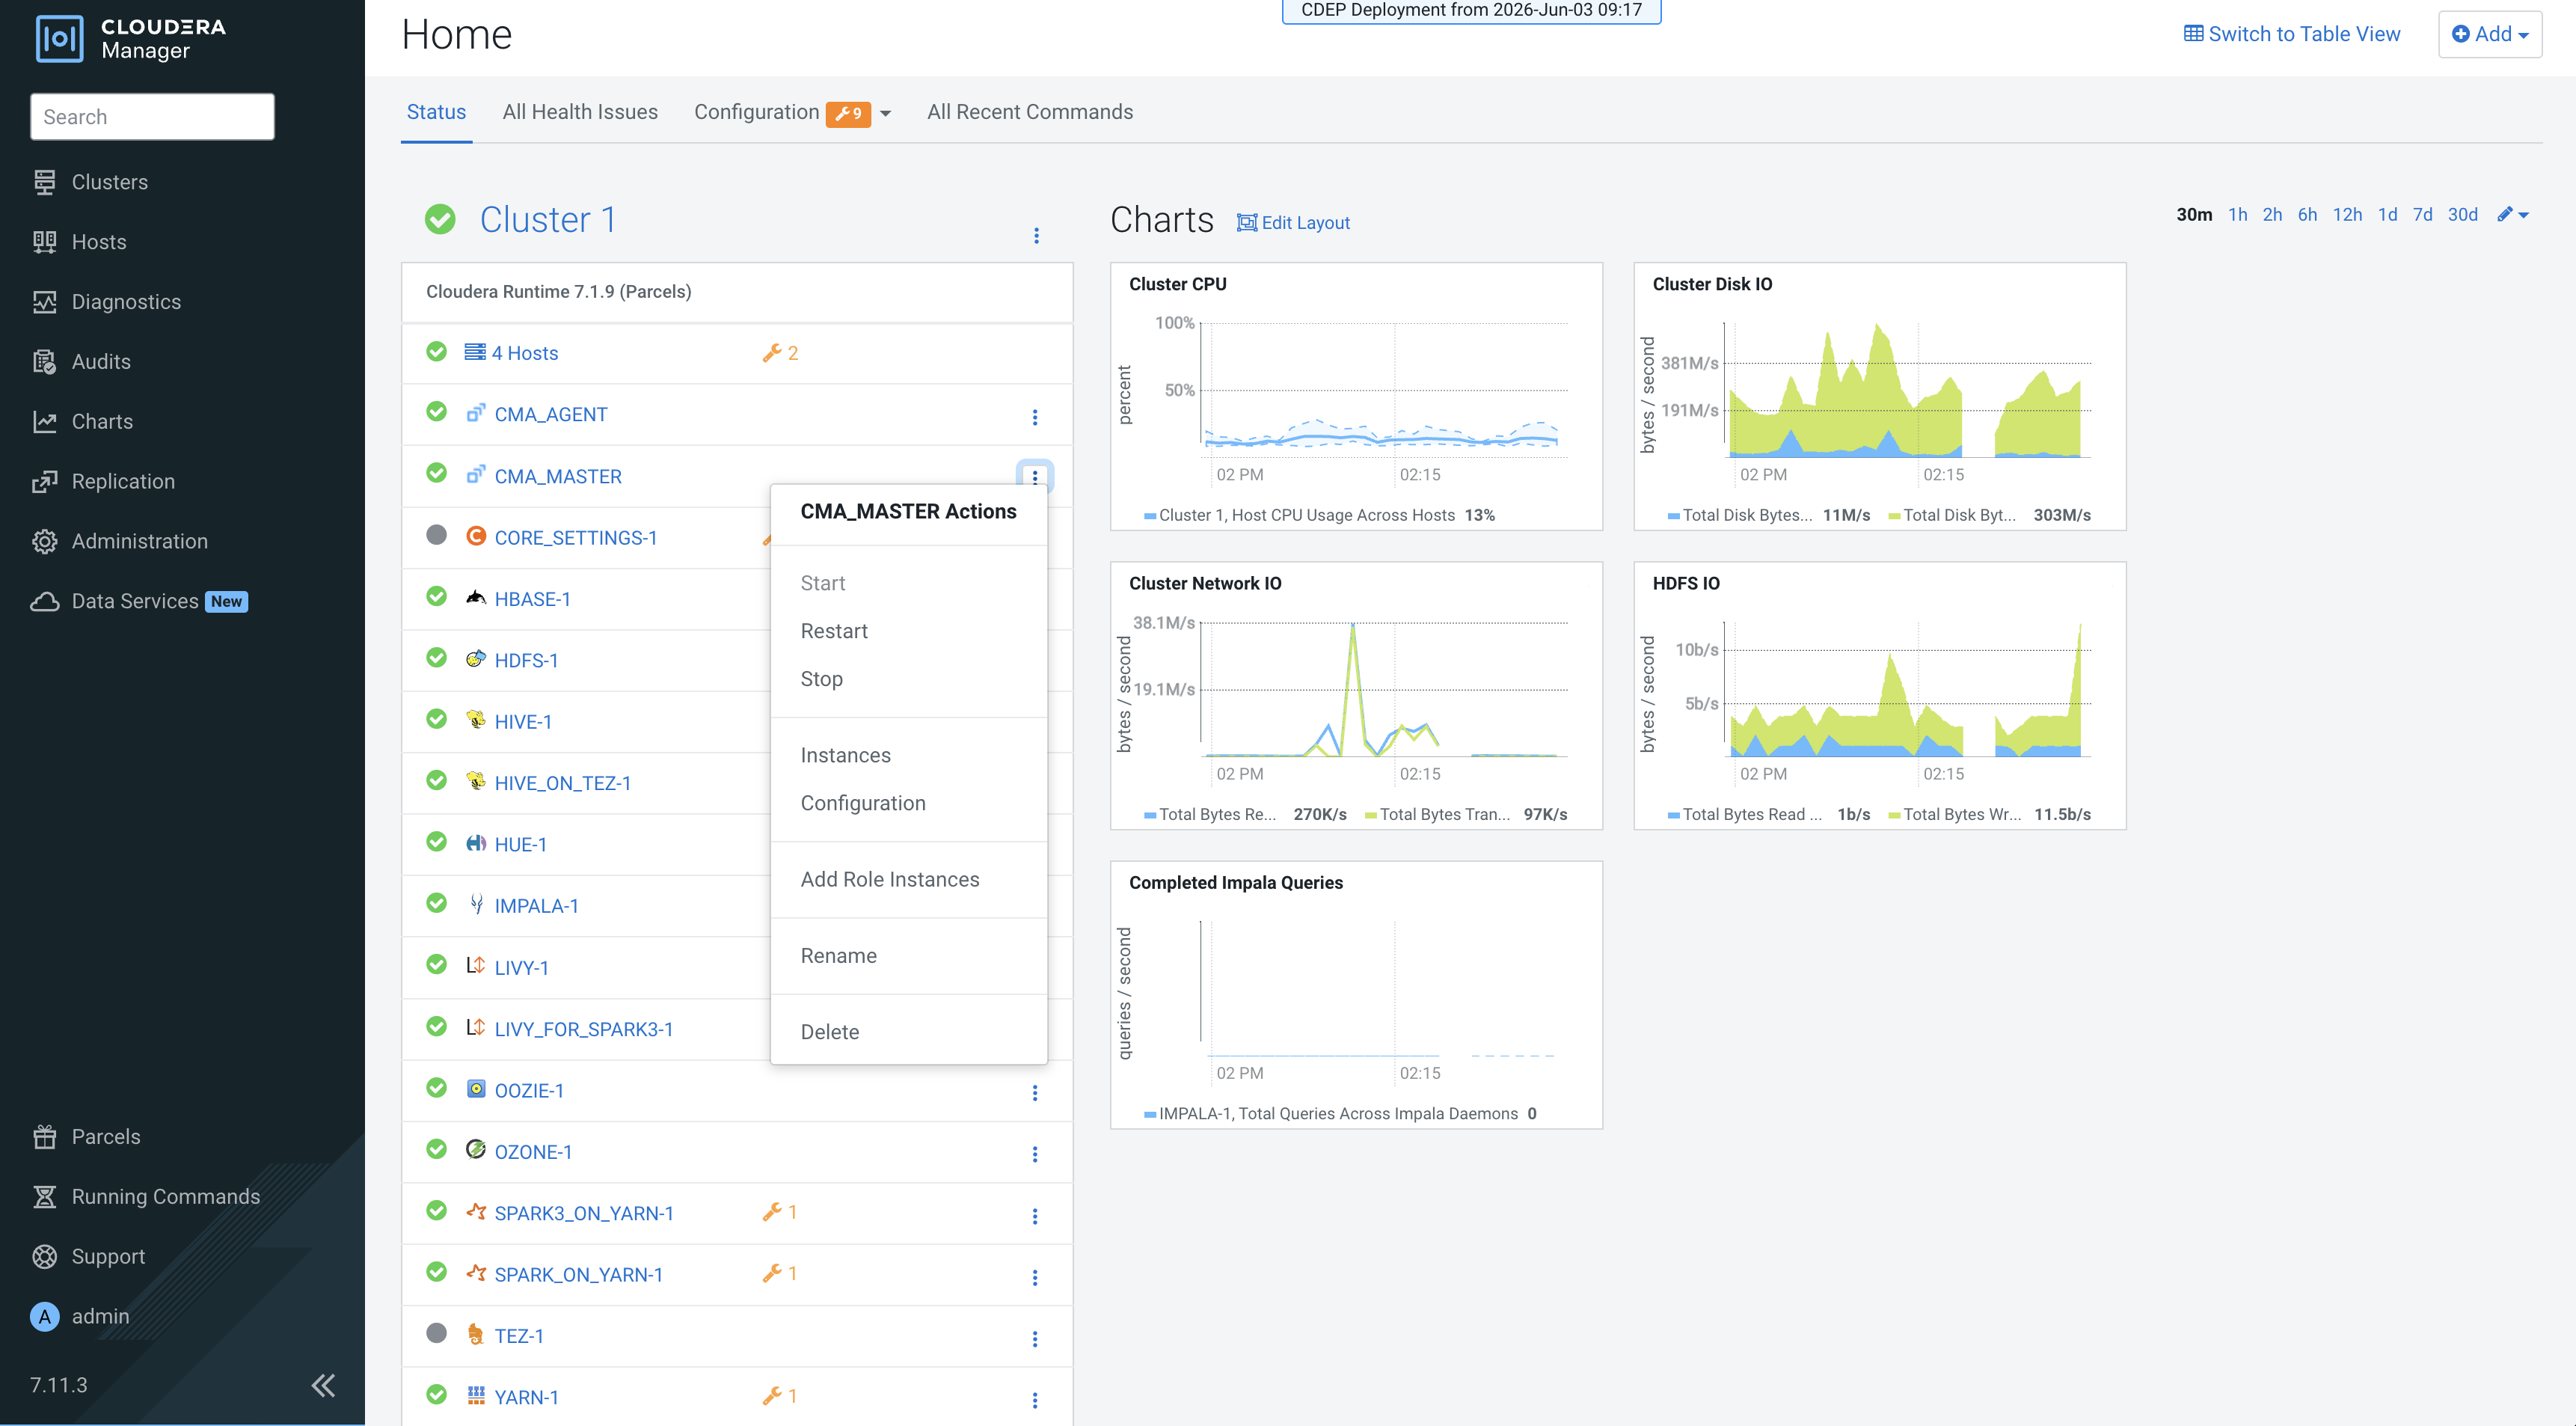
The first run of the service starts. When the command finishes, the service is added to
the cluster.
Figure 4. service started
Repeat steps
16–19
to add the other service type if
needed (for example, add
CMA_AGENT after CMA_MASTER, or vice
versa).
Go back to the cluster homepage, open the
service page, and click the Server UI tab to open the UI.
Figure 5. landing page
Set the
service dependency to
none
in the service configuration in Cloudera
Manager
because
Cloudera
Manager
cannot
discover the
Master automatically
across
clusters.
Set the Gateway URL
to
cma_gateway_url
in the service configuration.
Phase 2 — Configure Cloudera Replication Manager on the target cluster
Enable the HDFS to Ozone flag on the Server host.
For HDFS to Ozone migrations, requires the
CMF_FF_API_H2O_REPLICATION feature flag to be enabled. Without this
flag, the API endpoints for HDFS to Ozone replication
are not available.
Append the following line to /etc/default/cloudera-scm-server on
the Server host:
export CMF_FF_API_H2O_REPLICATION=true
Restart the Server.
sudo systemctl restart cloudera-scm-server
Wait for to become available again on port 7180 before proceeding
with the setup.
Register the instance in the UI to allow to locate and communicate with the replication service.
In the Web UI, go to
Settings.
Go to the App Access section.
Configure your connection fields using one of the following validation methods:
If has already detected a service on one of the registered clusters,
select it from the Suggestions drop-down list to
auto-fill the form.
Manually enter your target replication parameters in the following fields:
App URL — The full URL of the REST
API, including protocol, host, and port, for example,
https://rm-host.example.com:9011.
App username — The username for
authenticating with the API.
App password — The password for
authenticating with the API.
Click Save and Push to Agents.
Prepare Ozone storage on the target (before Phase 6)
Known limitations
No input validation
does not validate layout definitions for
volumes, buckets, or quotas.
No feasibility pre-check
does not verify whether the specified
settings are feasible on the target cluster.
Limited migration testing
Ozone Layout Provisioning has not been tested as part of the end-to-end migration
workflow.
Use this feature for evaluation purposes only. Behavior and APIs may change in future
releases.
provides a Storage Layout
Editor for designing and deploying Ozone storage structures.
Both the Storage Layout Editor and the Ozone
browser use colors and text styles to indicate the status of volumes,
buckets, and folders. The two views display different stages of the same lifecycle.
The Storage Layout Editor displays both unsaved (local) changes and
changes that were saved to the database but not yet deployed to the cluster.
Table 1. Storage Layout Editor statuses
Status
Color
Style
Description
New or locally modified (unsaved)
Light red
Normal
Node was created or edited in the editor but not yet saved to the database.
Locally deleted (unsaved)
Light red
Strikethrough
Node was deleted in the editor but the deletion has not been saved yet.
Saved, pending CREATE
Red
Normal
Node was saved to the database and is queued for deployment to the cluster.
Saved, pending MODIFY
Default
Italic
Node was saved to the database and is queued for deployment to the cluster.
Saved, pending DELETE
Default
Strikethrough
Node was saved as a deletion and is queued for removal from the cluster.
Saved, no pending event
Default
Normal
Node is deployed and up to date.
The Ozone browser only displays nodes that have been saved to the
database. Unsaved editor changes are not visible here. If you have unsaved changes in the
editor, the browser shows the last saved state of those nodes until you save.
Table 2. Ozone browser statuses
Status
Color
Style
Description
Pending CREATE (saved, not yet deployed)
Red
Normal
Node was created and saved, awaiting deployment to the cluster.
Pending MODIFY (saved, not yet deployed)
Default
Italic
Node was modified and saved, awaiting deployment to the cluster.
Pending DELETE (saved, not yet deployed)
Default
Strikethrough
Node is queued for deletion. All children of a pending-delete node are also displayed with strikethrough.
No pending event
Default
Normal
Node is deployed and up to date.
Plan and deploy an Ozone storage layout using the Storage Layout
Editor.
Go to the Layout tab in the cluster view to access the
Storage Layout Editor.
Design the layout structure in the Plan tab and apply the
layout to the cluster in the Deploy tab.
The Plan tab displays the following panels.
Left panel (Available Templates) — Contains reusable
volume structures you can drag into the editor.
Right panel (Editor) — Is the working area where you build
the target Ozone structure.
Add volumes and buckets manually.
Select the cluster on the Clusters page.
Go to the Layout tab.
In the Plan tab, click the
Add
Volume button at the top of the editor panel.
Provide the volume properties in the drawer that opens, then click
Create.
To add buckets to a volume, select the volume node and click Add
Bucket.
To add folders to a bucket, select the bucket node and click Add
Folder.
Click Save Plan in the toolbar to save all pending changes
to the database.
The Available Templates panel on the left displays reusable volume
structures. You can use the following template types:
System templates — Built-in templates provided by .
These cannot be deleted.
User templates — Templates you create from volumes in the editor. These can be
deleted.
Search and filter templates.
Use the Search field at the top of the Available
Templates panel to filter templates by name. Use the
Type drop-down list to filter by template type.
Drag a template into the editor.
In the Available Templates panel, click the template name to
expand it and see its volumes, buckets, and folders.
Drag the node you want (volume, bucket, or folder) by its drag handle into the editor panel on the right.
You can drag any node from a template directly into the editor to add it to the
layout. Volumes, buckets, and folders can all be dragged individually using the drag
handle (the grip icon on the right side of each node). When you drag a node, the
full subtree (all its children) moves with it.
Save a volume as a template.
You can save any volume in the editor as a template to reuse it later. Saving a volume
as a template stores the entire volume structure, including its buckets and folders, in
the Available Templates panel.
In the editor, hover over the volume node you want to save.
Click Add to Template that is the download icon that is
displayed on hover.
Provide a name for the template.
Click Save.
The template is displayed in the Available Templates panel and
is stored in the database.
Delete a user template.
In the Available Templates panel, hover over the template
name.
Click the icon next to the template name.
Click Delete to confirm the deletion.
Import a layout from YAML or JSON.
You can define a complete Ozone storage structure in a YAML or JSON file and import it
into the editor.
This example shows a YAML file defining volumes, buckets, and folders in a
hierarchical structure.
In the Plan tab, click Import
Structure in the toolbar.
Upload the YAML or JSON file or paste the YAML or JSON content.
Click Upload.
validates the structure and loads the
volumes, buckets, and folders into the editor. Validation errors are displayed if
the YAML or JSON is malformed or contains invalid values.
Click Save Plan to save the imported structure to the
database.
Deploy the layout to the cluster.
Click the Deploy tab in the Layout
page.
The Deployment Queue table displays all saved volumes,
buckets, and folders that have pending changes. The CREATE, MODIFY, or DELETE events
are not yet applied to the cluster.
Review the pending changes in the Volumes,
Buckets, and Folders tables.
Click Deploy to Ozone.
sends the deploy command to the on the cluster. Monitor progress in the
Commands tab on the cluster view. The agent processes the
changes in the following order:
Create, update, or delete volumes.
Create, update, or delete buckets.
Create, update, or delete folders.
Phase 3 — Register source and target clusters
In on the source cluster, select Add
Service and select
CMA_AGENT.
Configure the required properties.
Table 3. configuration properties
Property
Description
cma_gateway_url
URL of the Gateway,
for
example,
https://master-host:8093.
Required when the is on a different cluster
than
the . The agent uses this URL
to discover the Master host, gRPC port, and Auth Server URI automatically
through
the discovery endpoint (GET /api/agent/config). When connecting
from a different
cluster,
set the service dependency to
none
in .
cm_username
administrator user name.
cm_password
administrator password.
cma_user_home
Home directory for the cma-agent
user,
for
example,
/var/lib/cma-agent.
Set cma_gateway_url when the is on a different cluster than the .
Start the service.
Wait for the agent to connect to the
and finish
the
registration automatically.
Phase 4 — Scan clusters
Navigate to the Clusters page and click the cluster you want to scan.
Figure 6. Clusters page
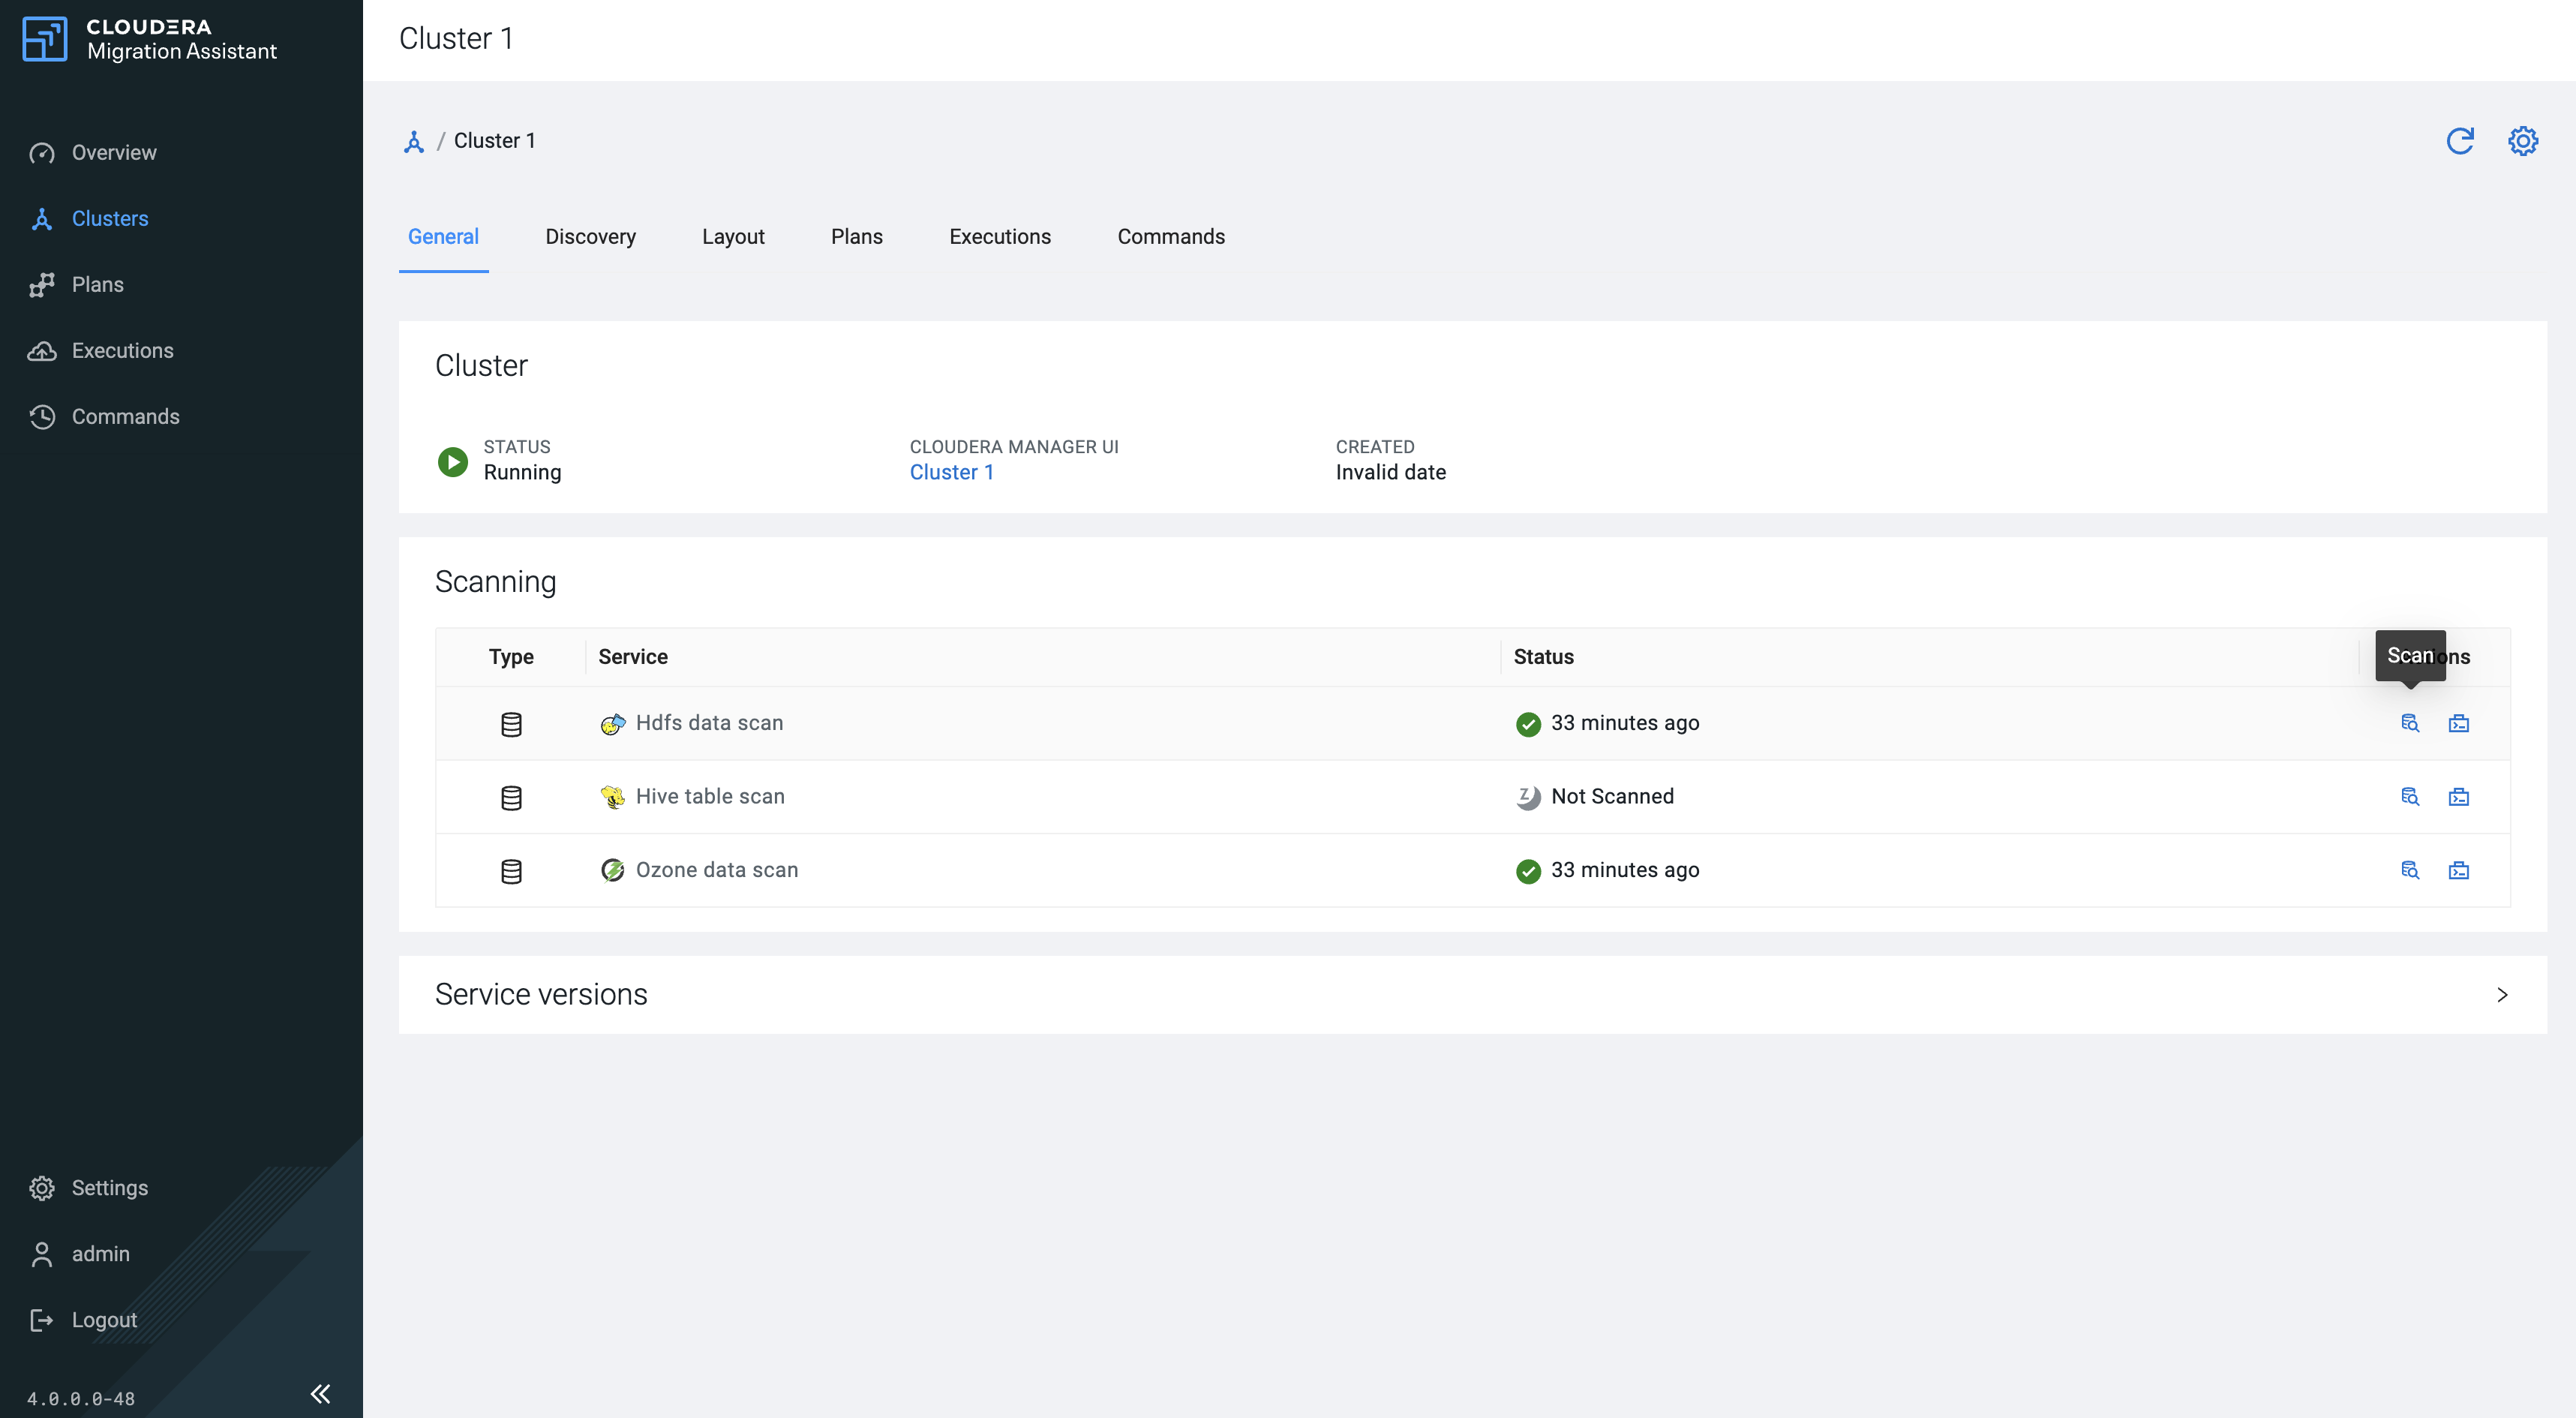
On the cluster detail page, find the Scanning section, which lists the available scan types for your cluster. Click the configuration icon on the right side of the scan type you want to trigger.
Figure 7. cluster scanning
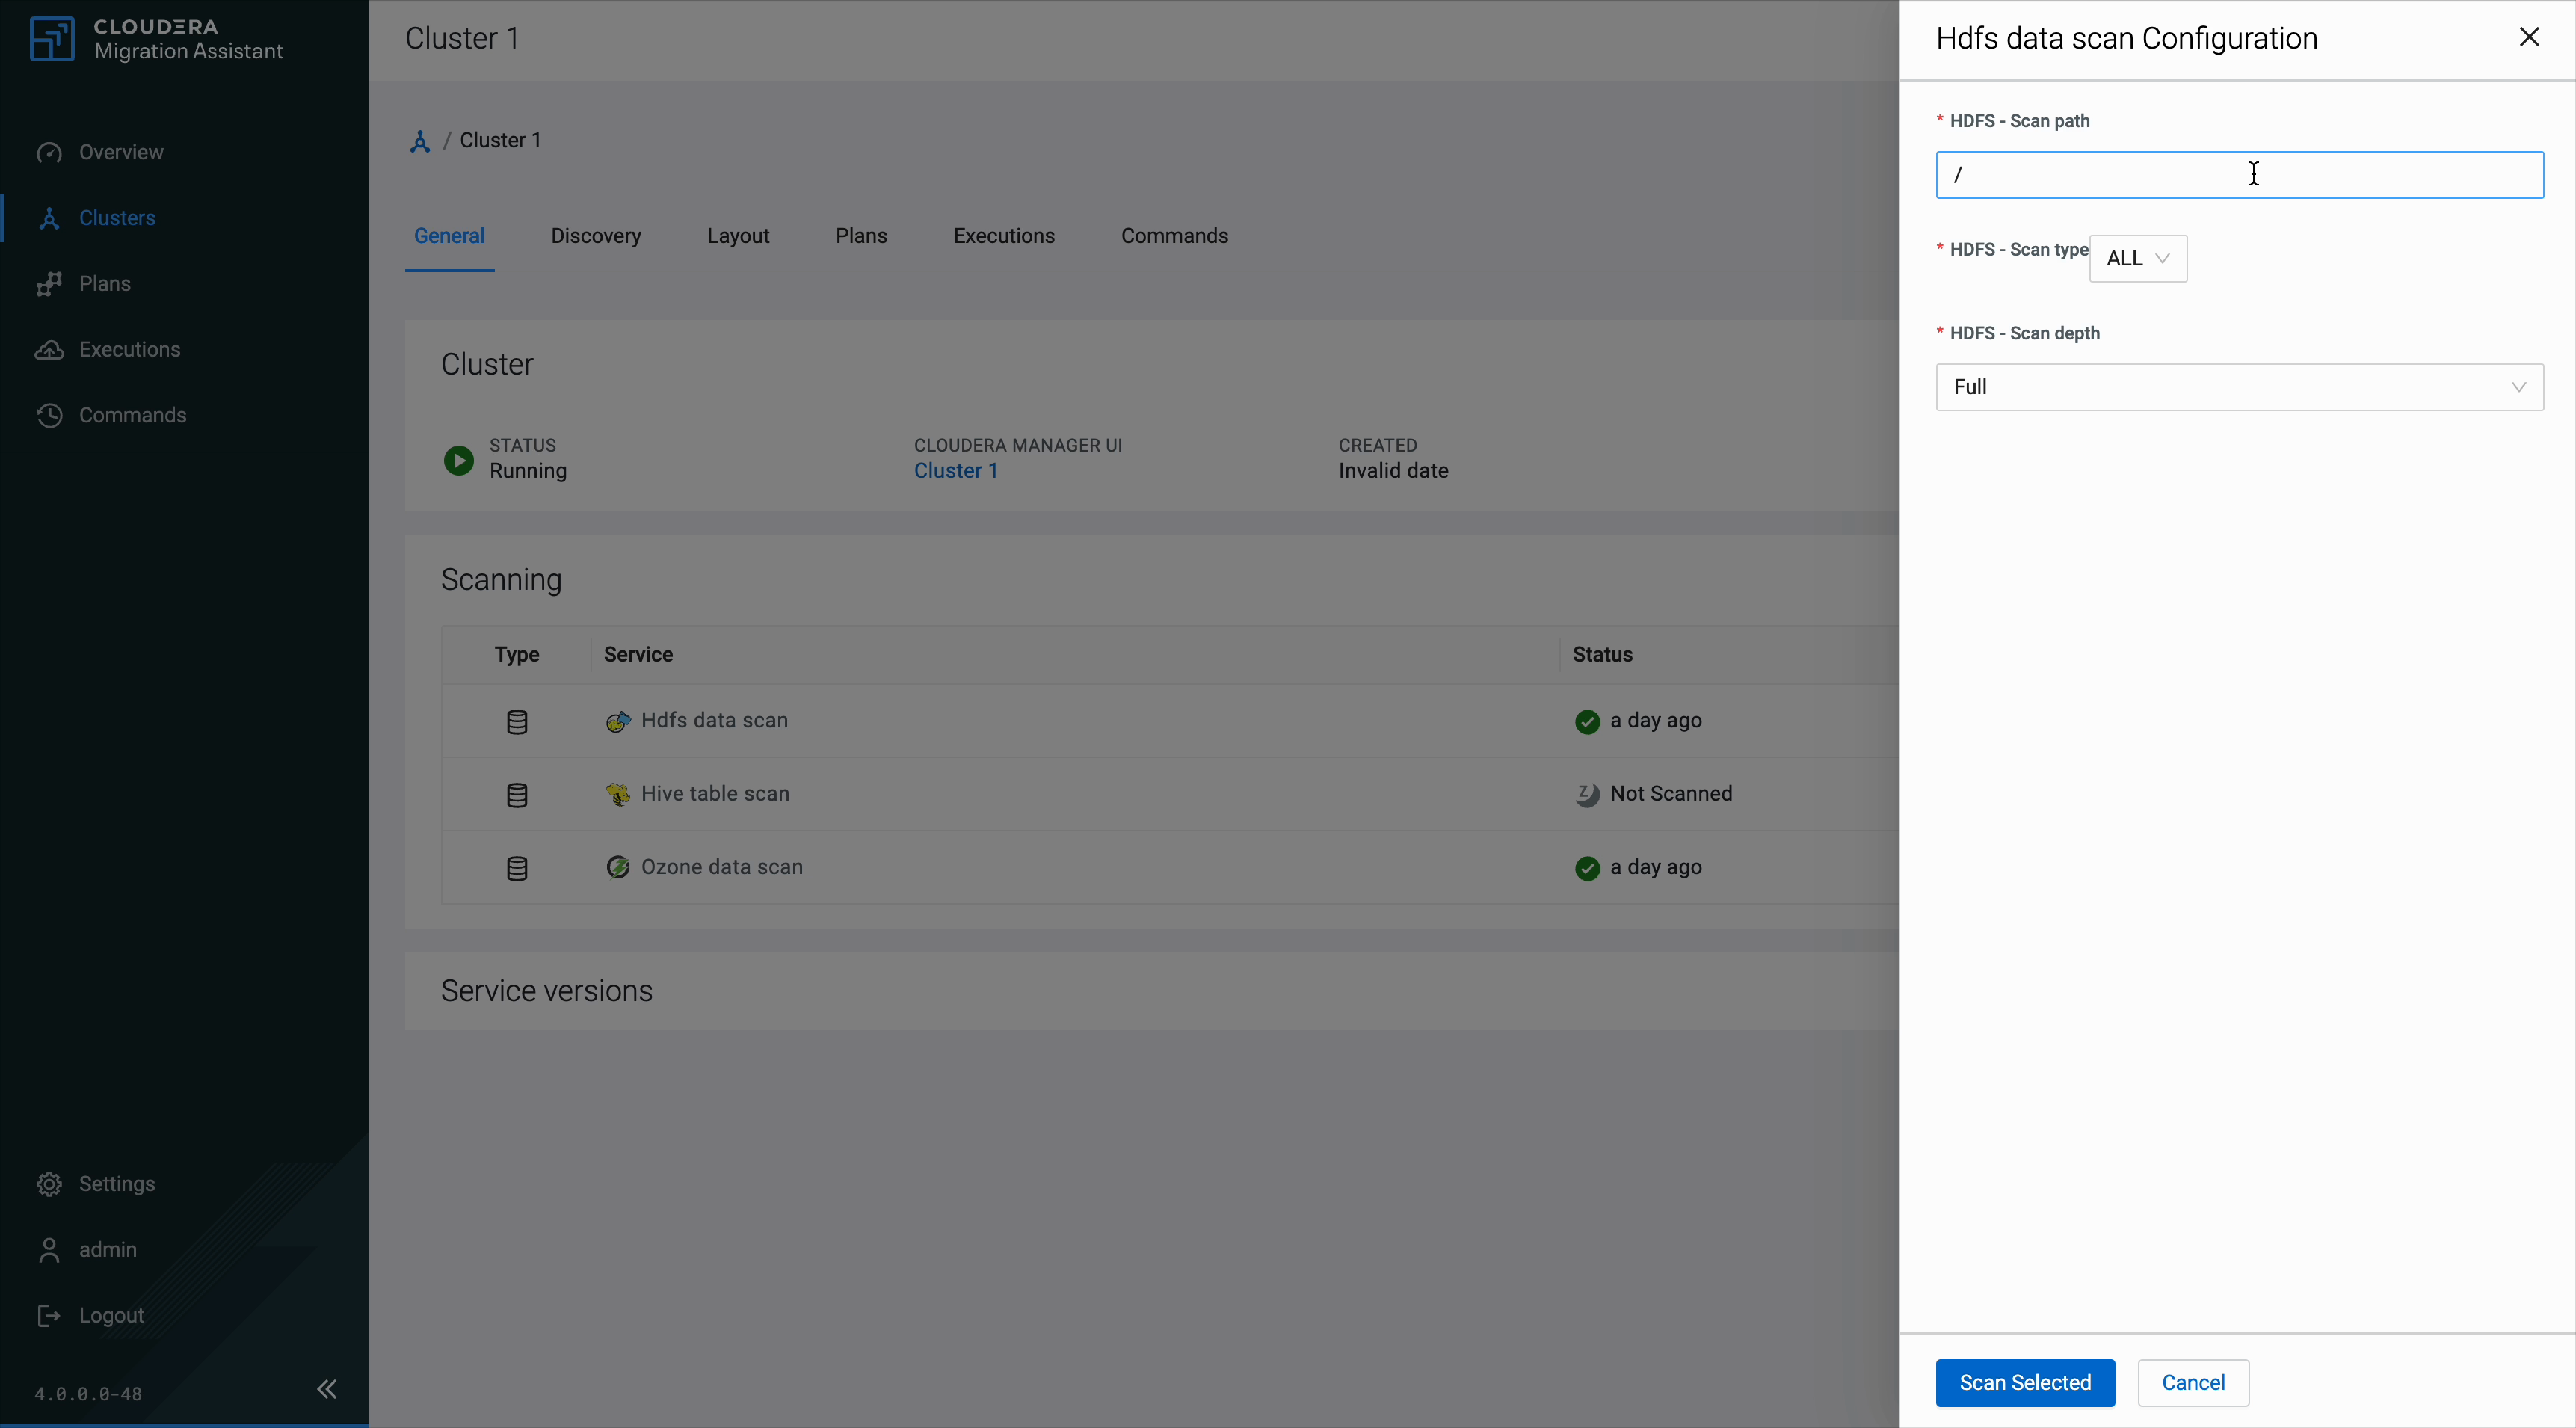
In the scan configuration drawer, configure the scan parameters (for example, scan path, scan type, scan depth) and click Scan Selected.
Figure 8. scan configuration
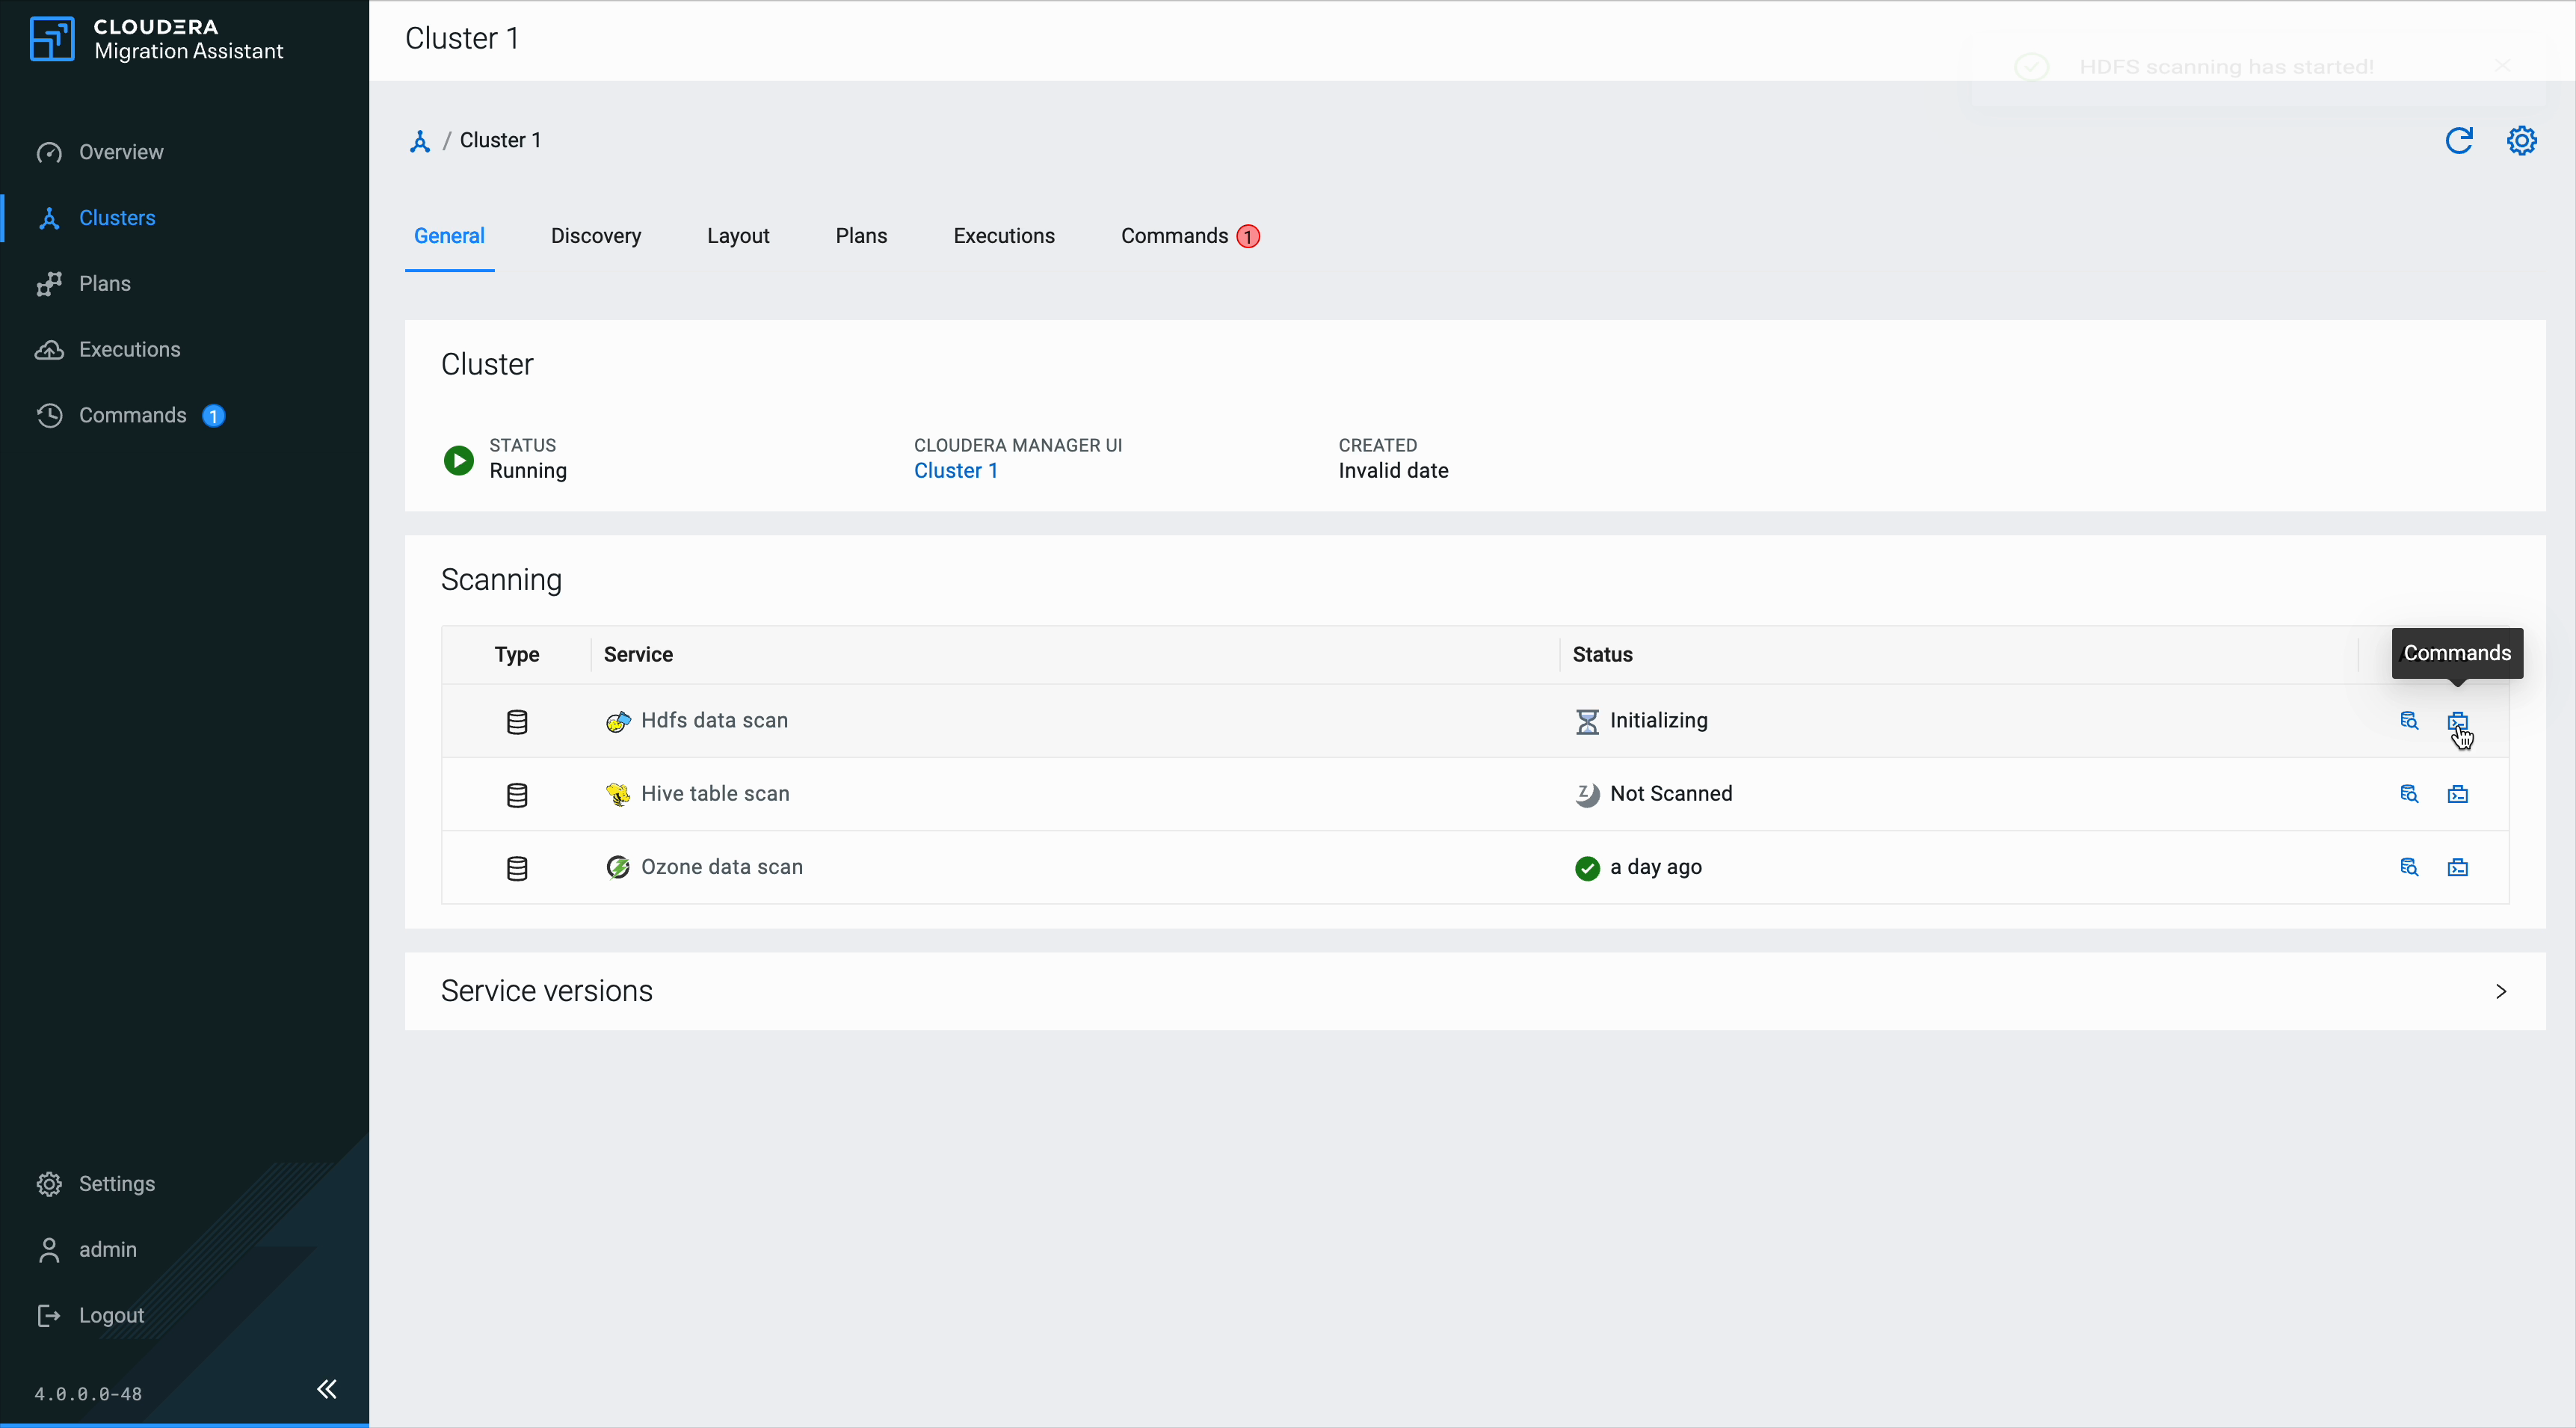
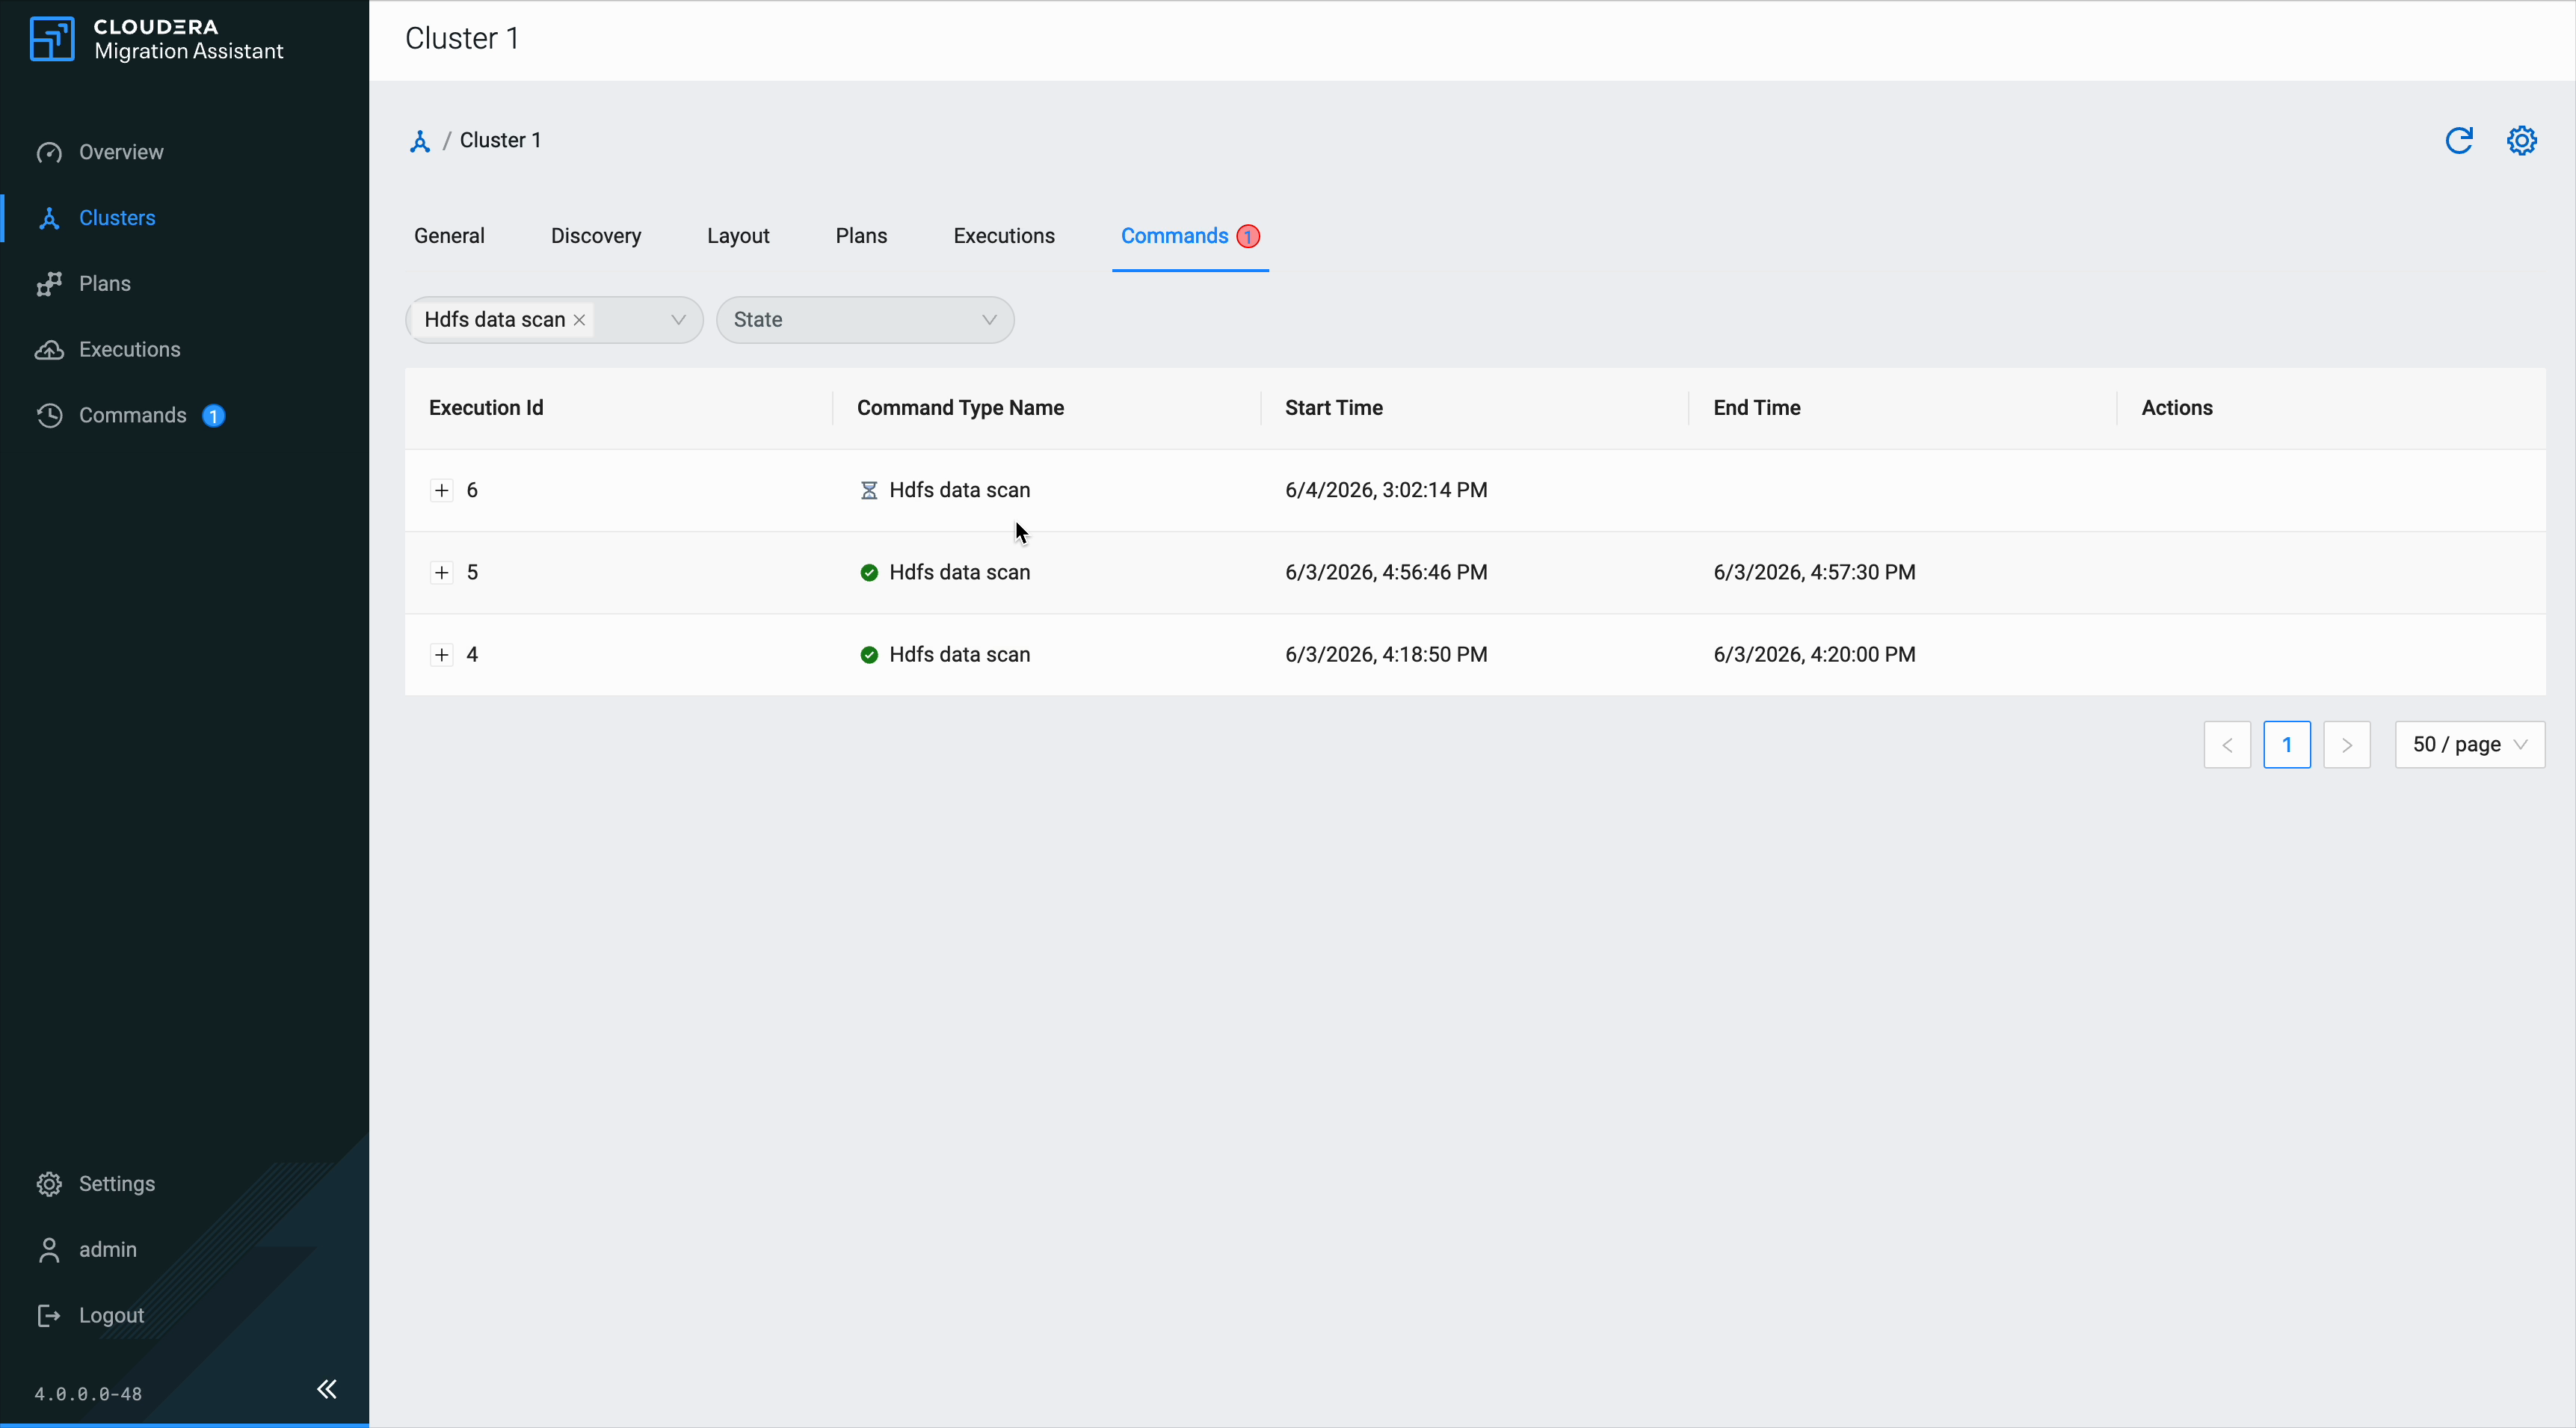
The scan starts and the status changes to Initializing. Track scan progress by clicking the Commands tab, which shows a badge with the number of active commands.
Figure 9. scan in progress
On the Commands tab, expand a command to view its Output Log, Error Log, and Configuration.
Figure 10. scan commands
Phase 5 — Create collections (optional)
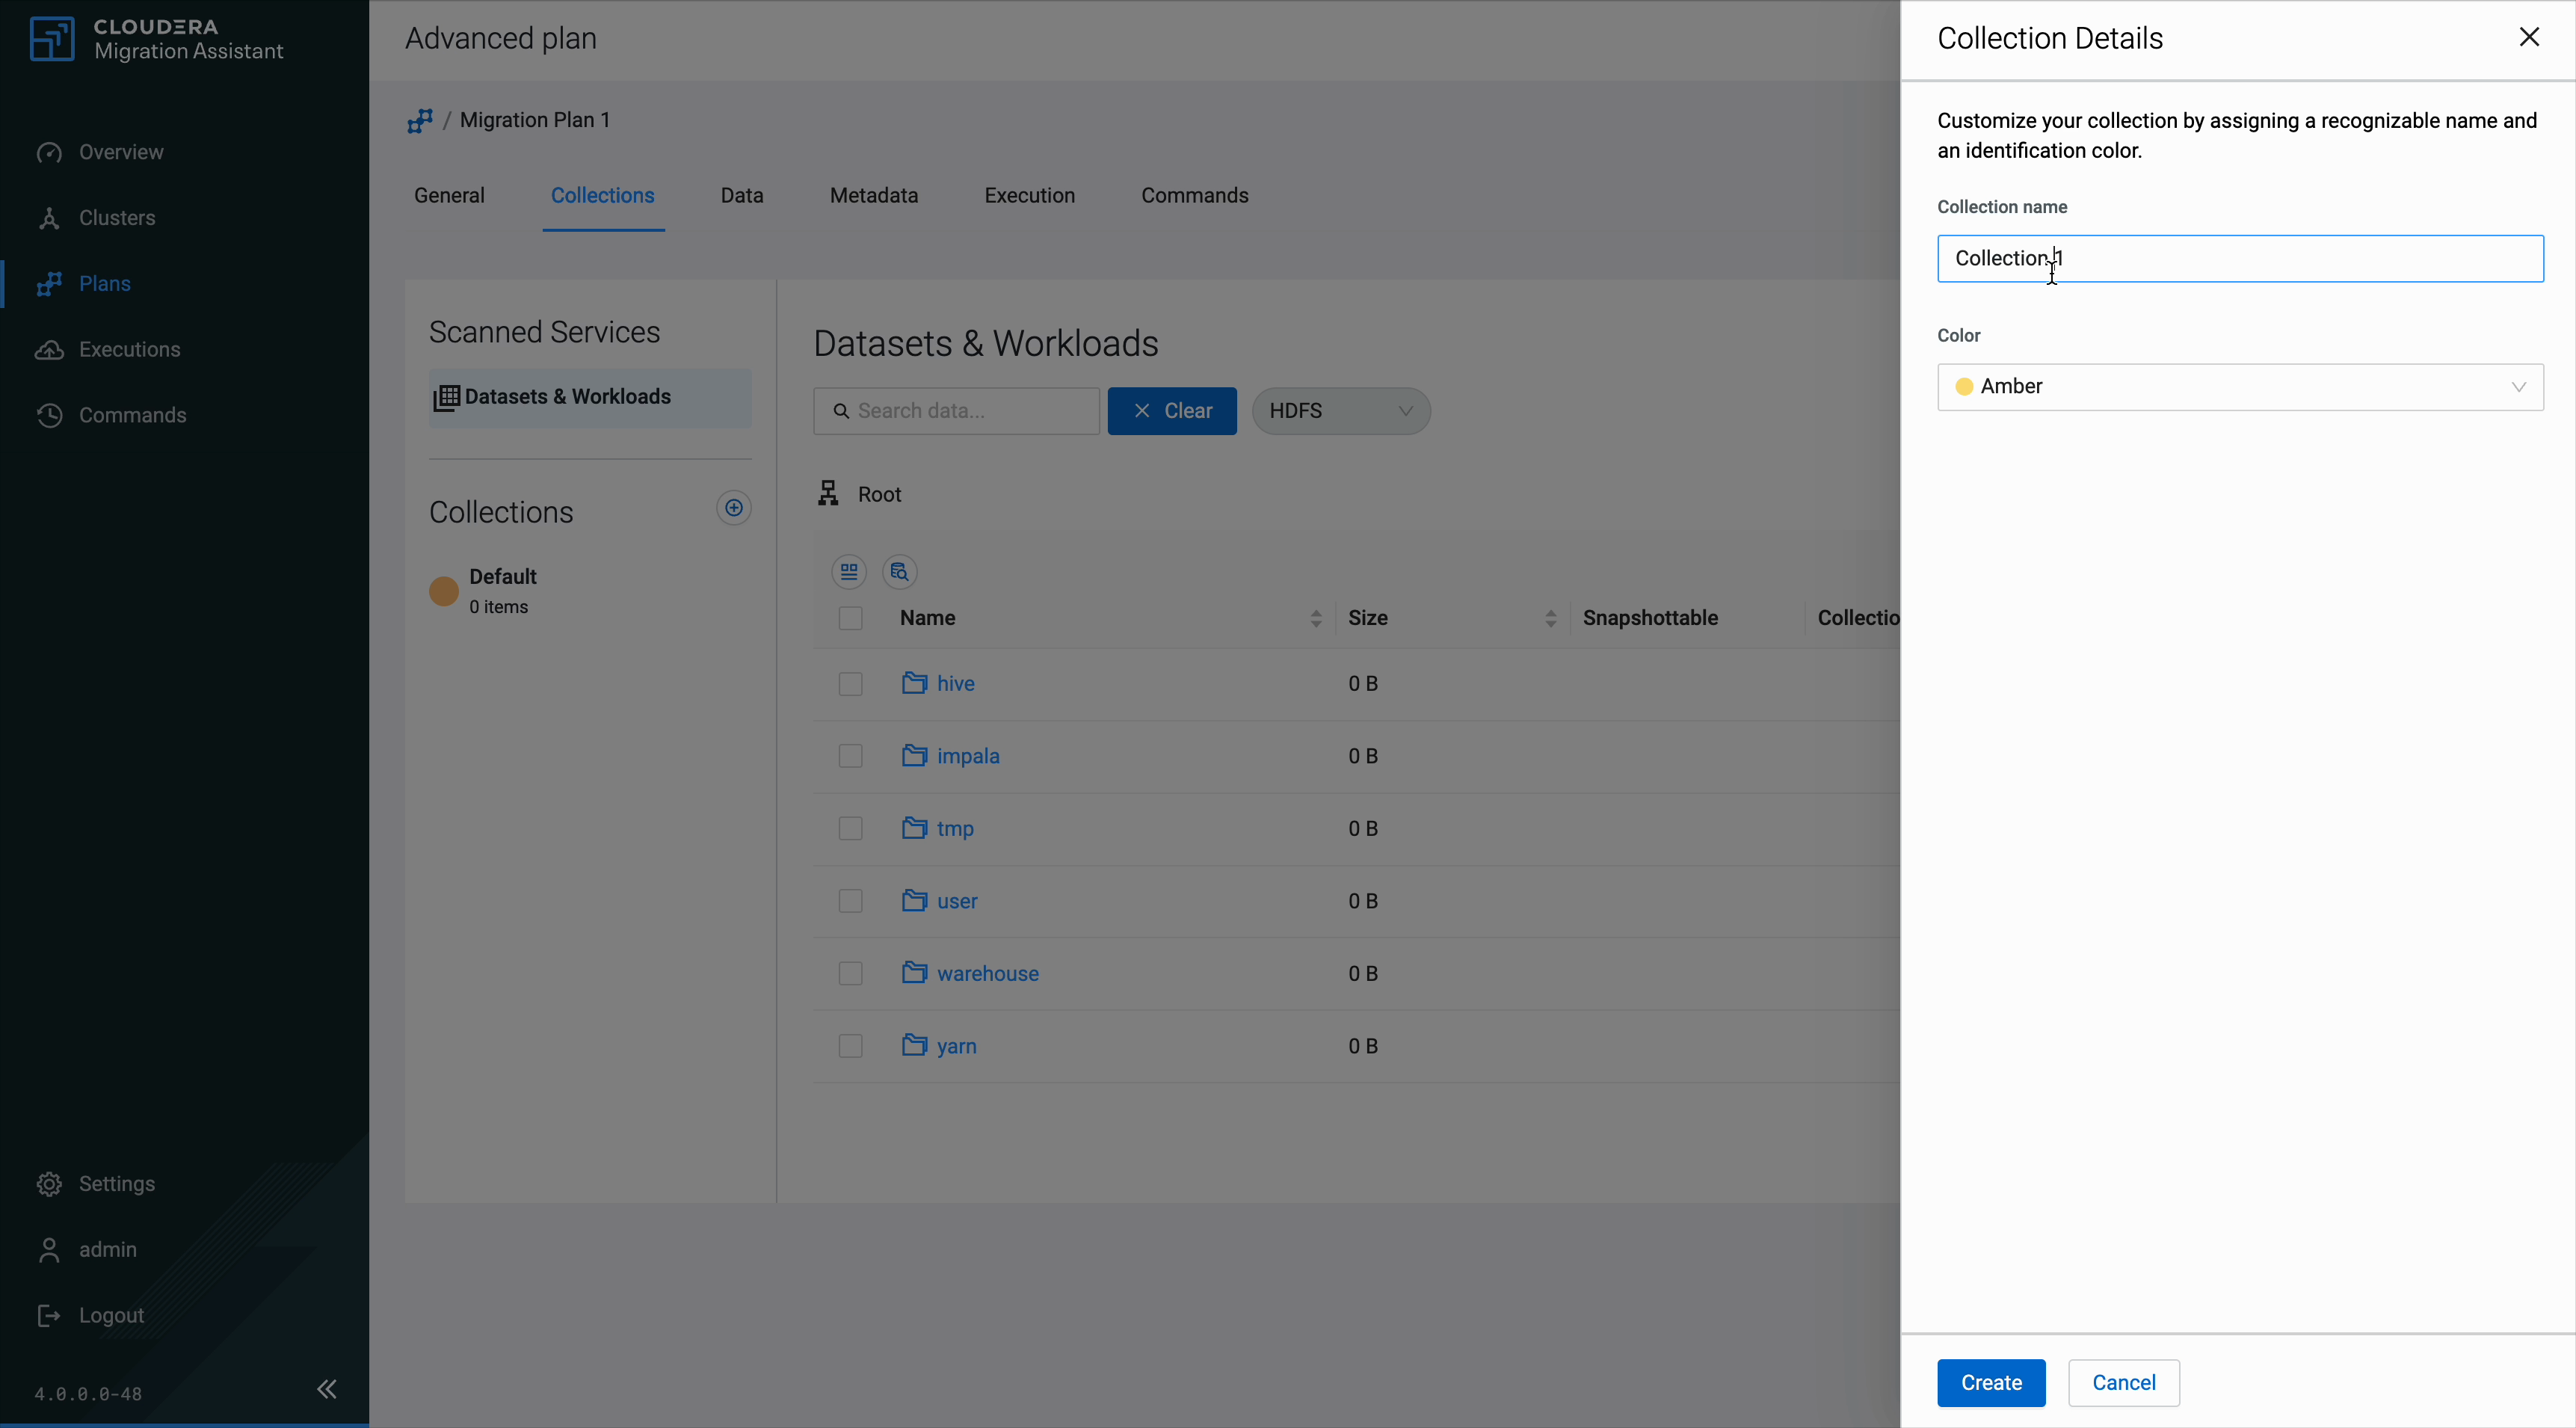
Click the + icon next to Collections in the sidebar.
In the Collection Details drawer, enter a Collection name and select a Color for identification.
Figure 11. create collection
Click Create.
The new collection appears in the sidebar with 0 items.
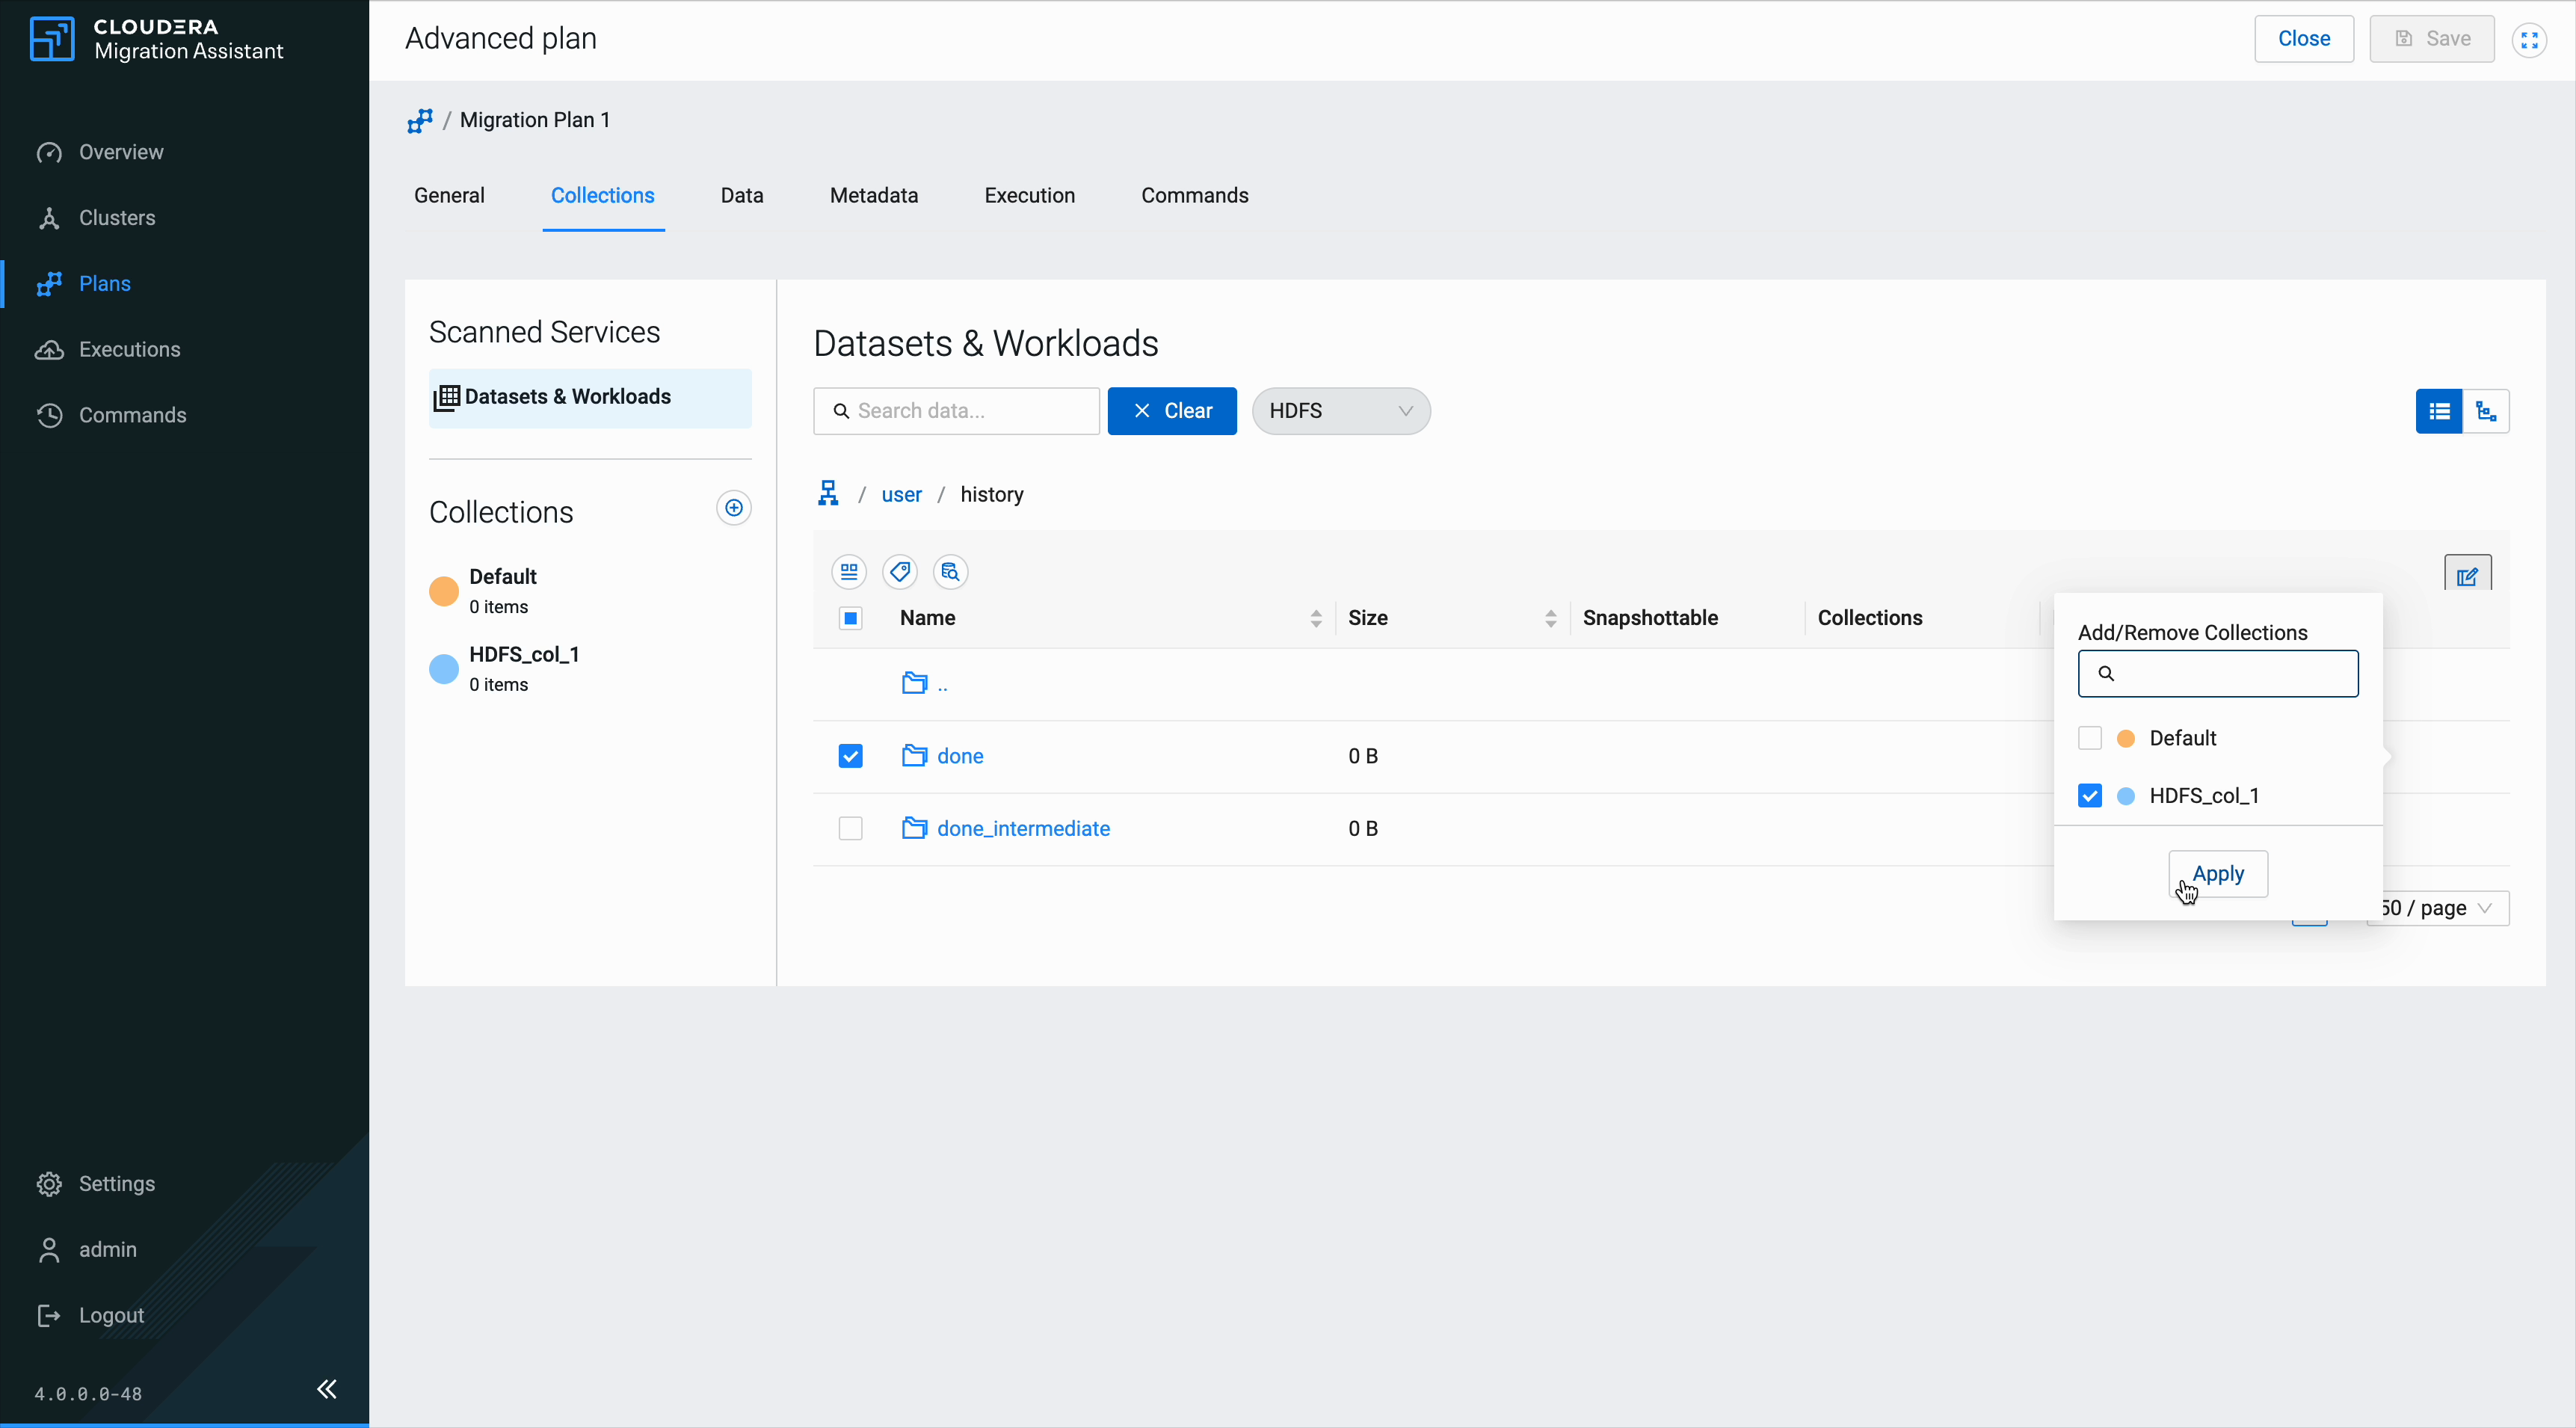
Browse the data tree to find the items you want to migrate. Click folder names to navigate deeper into the hierarchy.
Select items using the checkboxes next to each item.
Click the collection icon that appears on the selected item row.
In the Add/Remove Collections popup, check the collections you want to assign the item to.
Click Apply.
Figure 12. assign to collection
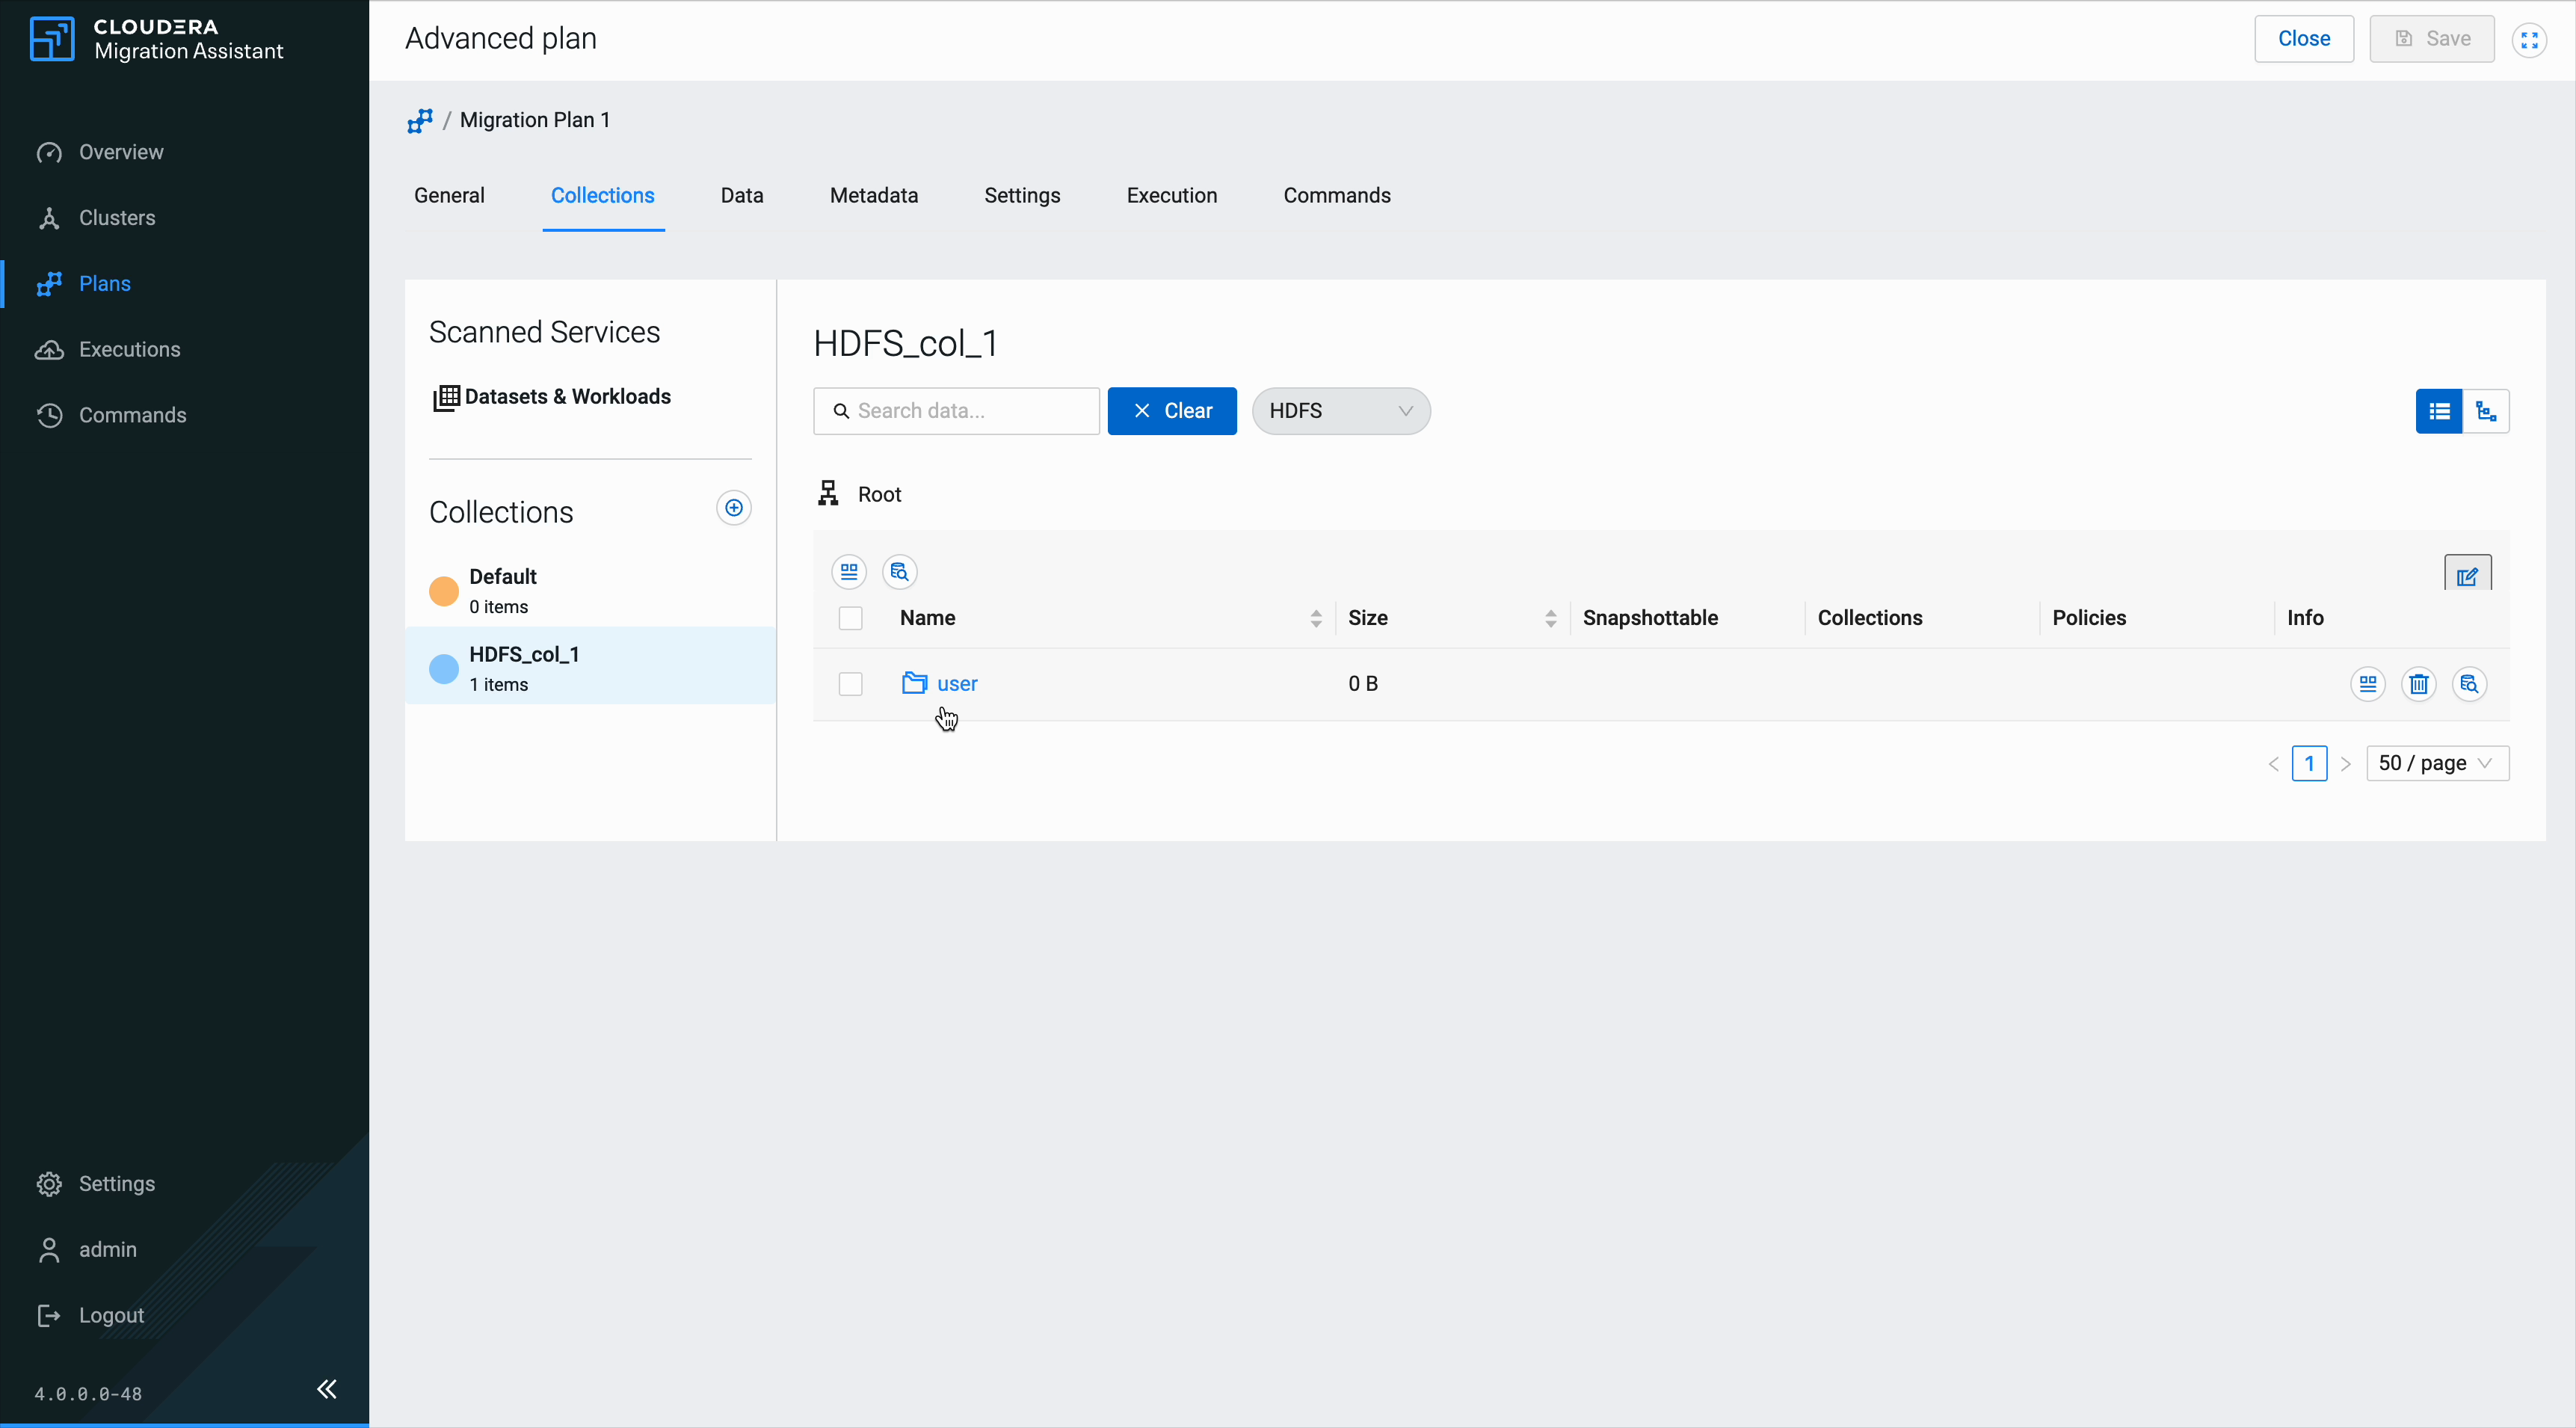
Click a collection name in the sidebar to view its contents. The data browser switches to show only the items assigned to that collection.
Figure 13. view collection
Phase 6 — Run the migration workload
Step 1 — Scan the
source
cluster
(HDFS)
Open Clusters, then
select
the source cluster.
Click Start Scanning.
Select
Hdfs data scan.
Optional: Constrain
the scan path,
for example,
/tmp or
/user,
to shorten runs on massive namespaces.
Click Scan selected and watch the progress drawer until
completion.
After success,
Discovery lists HDFS trees with
sizing and ownership snapshots.
Step 2 — Scan the
target
cluster
(Ozone)
Confirm Apache Ozone is healthy in before scanning.
From
Clusters,
open the target cluster.
Click Start Scanning.
Select Ozone data scan.
Click Scan selected and wait until the status turns green.
 icon next to the template name.