Deploying Cloudera in multiple GCP availability zones
You can optionally choose to deploy Data Lake, FreeIPA, and Cloudera Data Hub clusters across multiple availability zones (multi-AZ). With multi-AZ support, newly created GCP environments, enterprise Data Lakes and Cloudera Data Hub clusters using HA templates can be deployed across multiple availability zones of the selected GCP region. This provides fault tolerance during the extreme event of an availability zone outage.
Overview
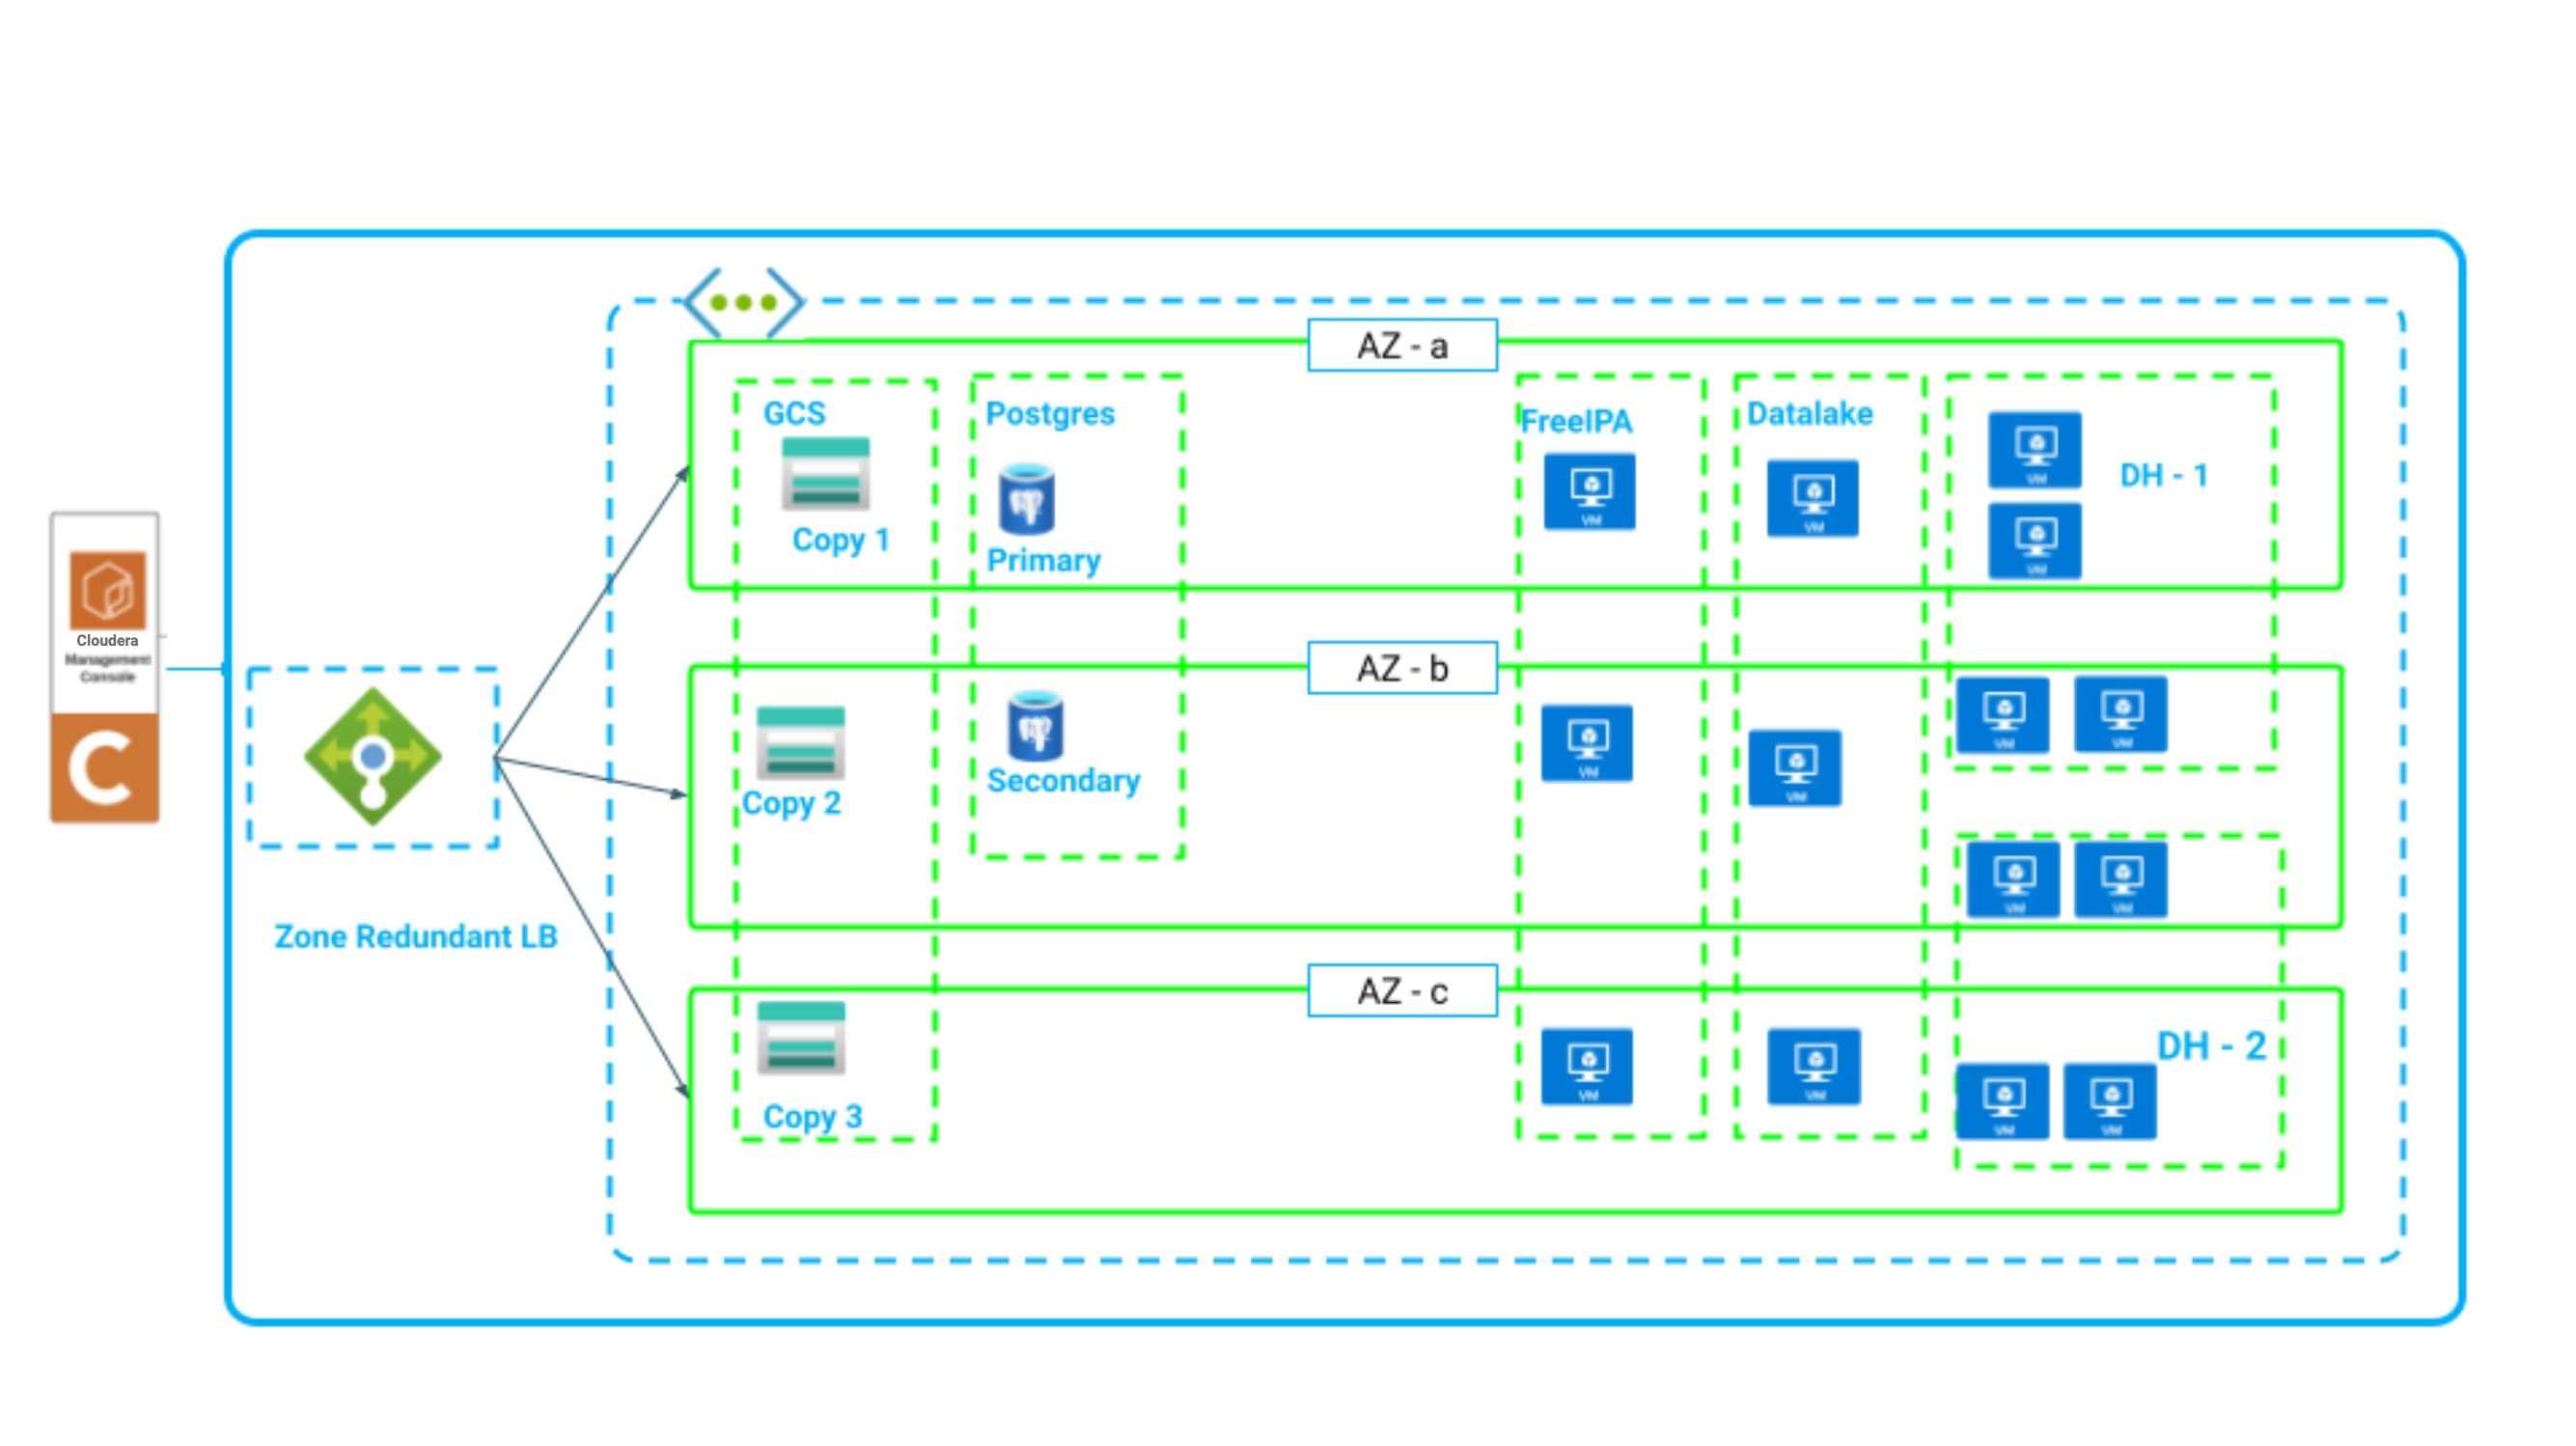
With the multi-AZ option enabled, your services are deployed as follows:
- GCP environments are always created with three FreeIPA servers, deployed on virtual machines spread across three available zones.
- In a GCP Enterprise Data Lake, each host group is configured so that virtual machines of all critical services are spread across three available zones.
- In HA Cloudera Data Hub clusters, virtual machines of each host group are evenly spread across three availability zones, following a round-robin logic.
When a zone failure happens and a cluster needs to be repaired, the replacement VMs are always provisioned in the same subnet and availability zone as the old ones since the detached disks can only be reattached to a VM in the same availability zone. This means that if there is an availability zone outage, cluster repair is not possible.
By default, if you do not enable multi-AZ, all GCP Cloudera and Cloudera customers do not have visibility into how GCP distributes VMs across availability zones, because the GCP Portal or CLI do not provide this information.
When creating Data Hubs via CDP CLI, you have the option to specify the AZ, which, in addition to allowing you to select the AZs that should be used, allows you to set up AZ targeting, where all nodes of the cluster are placed on the same AZ. This enables creating disaster recovery scenarios, where a primary and secondary cluster are running in different AZs. If an AZ outage occurs and the primary cluster is lost, it is guaranteed that the secondary cluster is not impacted.
Limitations
The following limitations apply when deploying a multi-AZ Cloudera:
- When an AZ is down, you cannot create a new Cloudera Data Hub cluster, and create or activate Cloudera Data Services within the environment. Existing workloads will continue to work.
- When an AZ is down, you cannot resize, stop, or restart Cloudera Data Hub clusters.
- Non-AZ environments or clusters cannot be converted to multi-AZ.
Use cases
A multi-AZ Data Lake and FreeIPA constitute a resilient environment that provides a solid basis for multi-AZ Data Hubs and Cloudera Data Services. Cloudera Data Hub clusters and Cloudera Data Services depend on the FreeIPA instance in the Data Lake to provide DNS resolution. Deploying FreeIPA across multiple availability zones ensures that critical DNS resolution is available in the event of an availability zone outage. Furthermore, an enterprise Data Lake provides high availability and additional compute and memory resources for key Data Lake services and is recommended for production workloads.
Deploying your Cloudera Data Hub clusters across multiple availability zones is key if your mission-critical applications depend on HBase and Kafka. Multiple availability zone deployment for operational workloads is considered best practice by the cloud vendors. It ensures that your applications can continue to run in the event of an availability zone outage.
When an entire availability zone fails, HBase automatically rebalances regions among the remaining instances in the cluster to maintain availability. The write-ahead log (WAL), which is replicated across the three availability zones, is automatically replayed by the newly assigned region servers in other availability zones to ensure writes to the database are not lost.
When using the multi-availability zone feature, Cloudera ensures that Kafka replicates partitions across brokers in different availability zones. During an availability zone failure, this ensures that no data is lost and applications can continue to access the data they need. Cruise Control, which is deployed alongside every Kafka cluster in Cloudera on cloud, detects that topics need to be rebalanced to the remaining brokers. Once the availability zone is back online, you can repair your Kafka cluster, restoring the initial broker distribution across availability zones. Afterwards, Cruise Control ensures that all topic partitions are balanced across the cluster.
Register a multi-AZ environment
You can register a multi-AZ GCP environment through Cloudera UI or CDP CLI. During environment creation, you can enable multi-AZ for the Data Lake, for FreeIPA, or for both.
- On the Data Access and Data Lake Scaling page:
- Select Enterprise.
- Scroll down and at the bottom of the page enable Advanced Options.
- In the Network And Availability section enable the Enable Multiple Availability Zones for Data Lake toggle to enable multi-AZ for Data Lake. The option is disabled by default and only appears when Enterprise Data Lake is selected.
- On the Region, Networking and Security page:
- Scroll down and at the bottom of the page enable Advanced Options.
- In the Network And Availability section enable the Enable Multiple Availability Zones for Data Lake toggle to enable multi-AZ for FreeIPA. The option is disabled by default.
- Finish registering your environment as usual.
Use the following CDP CLI commands to register an environment with a multi-AZ Data Lake and FreeIPA:
- Register a GCP environment using theIf you do not include the
cdp environments
                create-gcp-environment
command and includemultiAz=truein the--free-ipaparameter as shown in this example:cdp environments create-gcp-environment \ --environment-name test-env \ ... --free-ipa instanceCountByGroup=3,multiAz=true \multiAz=true, the default AZ distribution will be used.You can also optionally include the--availability-zonesparameter to select the specific availability zones that should be used. Valid availability zone name format is<region-region>-<zone>, where<zone>is a lowercase letter. Each region has a different number of availability zones. For example, theus-west2region has three zones,us-west2-a,us-west2-b, andus-west2-c. If this parameter is not provided, all AZs are used. For example:cdp environments create-gcp-environment \ --environment-name test-env \ ... --free-ipa instanceCountByGroup=3,multiAz=true \ --availability-zones us-west2-a,us-west2-b - Set IDBroker mappings using the
cdp environments set-id-broker-mappingscommand. - Create a Data Lake using the
cdp datalake create-gcp-datalakecommand with the--multi-azparameter. For example:cdp datalake create-gcp-datalake \ --datalake-name test-dl \ --environment-name test-env \ ... --scale ENTERPRISE \ --runtime 7.3.2 \ --multi-az
