Spark lineage
Atlas collects metadata from Spark to represent the lineage among data assets.
The Atlas lineage graph shows the input and output processes that the selected entity
participated in, specifically relationships modeled as inputToProcesses and
outputFromProcesses. Entities are included if they were inputs to processes
that lead to the current entity or they are output from processes for which the current entity
was an input.
In the context of Spark, a Spark job is modeled as a spark_application
entity. Each application entity includes relationships to one or more processes that were
executed in the job. The spark_process entities are automatically named
execution-n, where n is a
counter
that starts at 0 for each Spark application and increases for every query
that Spark runs, including internal queries and queries that do not produce lineage. As a
result, the numbers in Atlas are not always consecutive. For example, in the following
figures, the two CREATE TABLE AS SELECT statements of a single job appear as
execution-2 and execution-4.
To view the lineage of an entity, open the entity details page and select the Lineage tab.
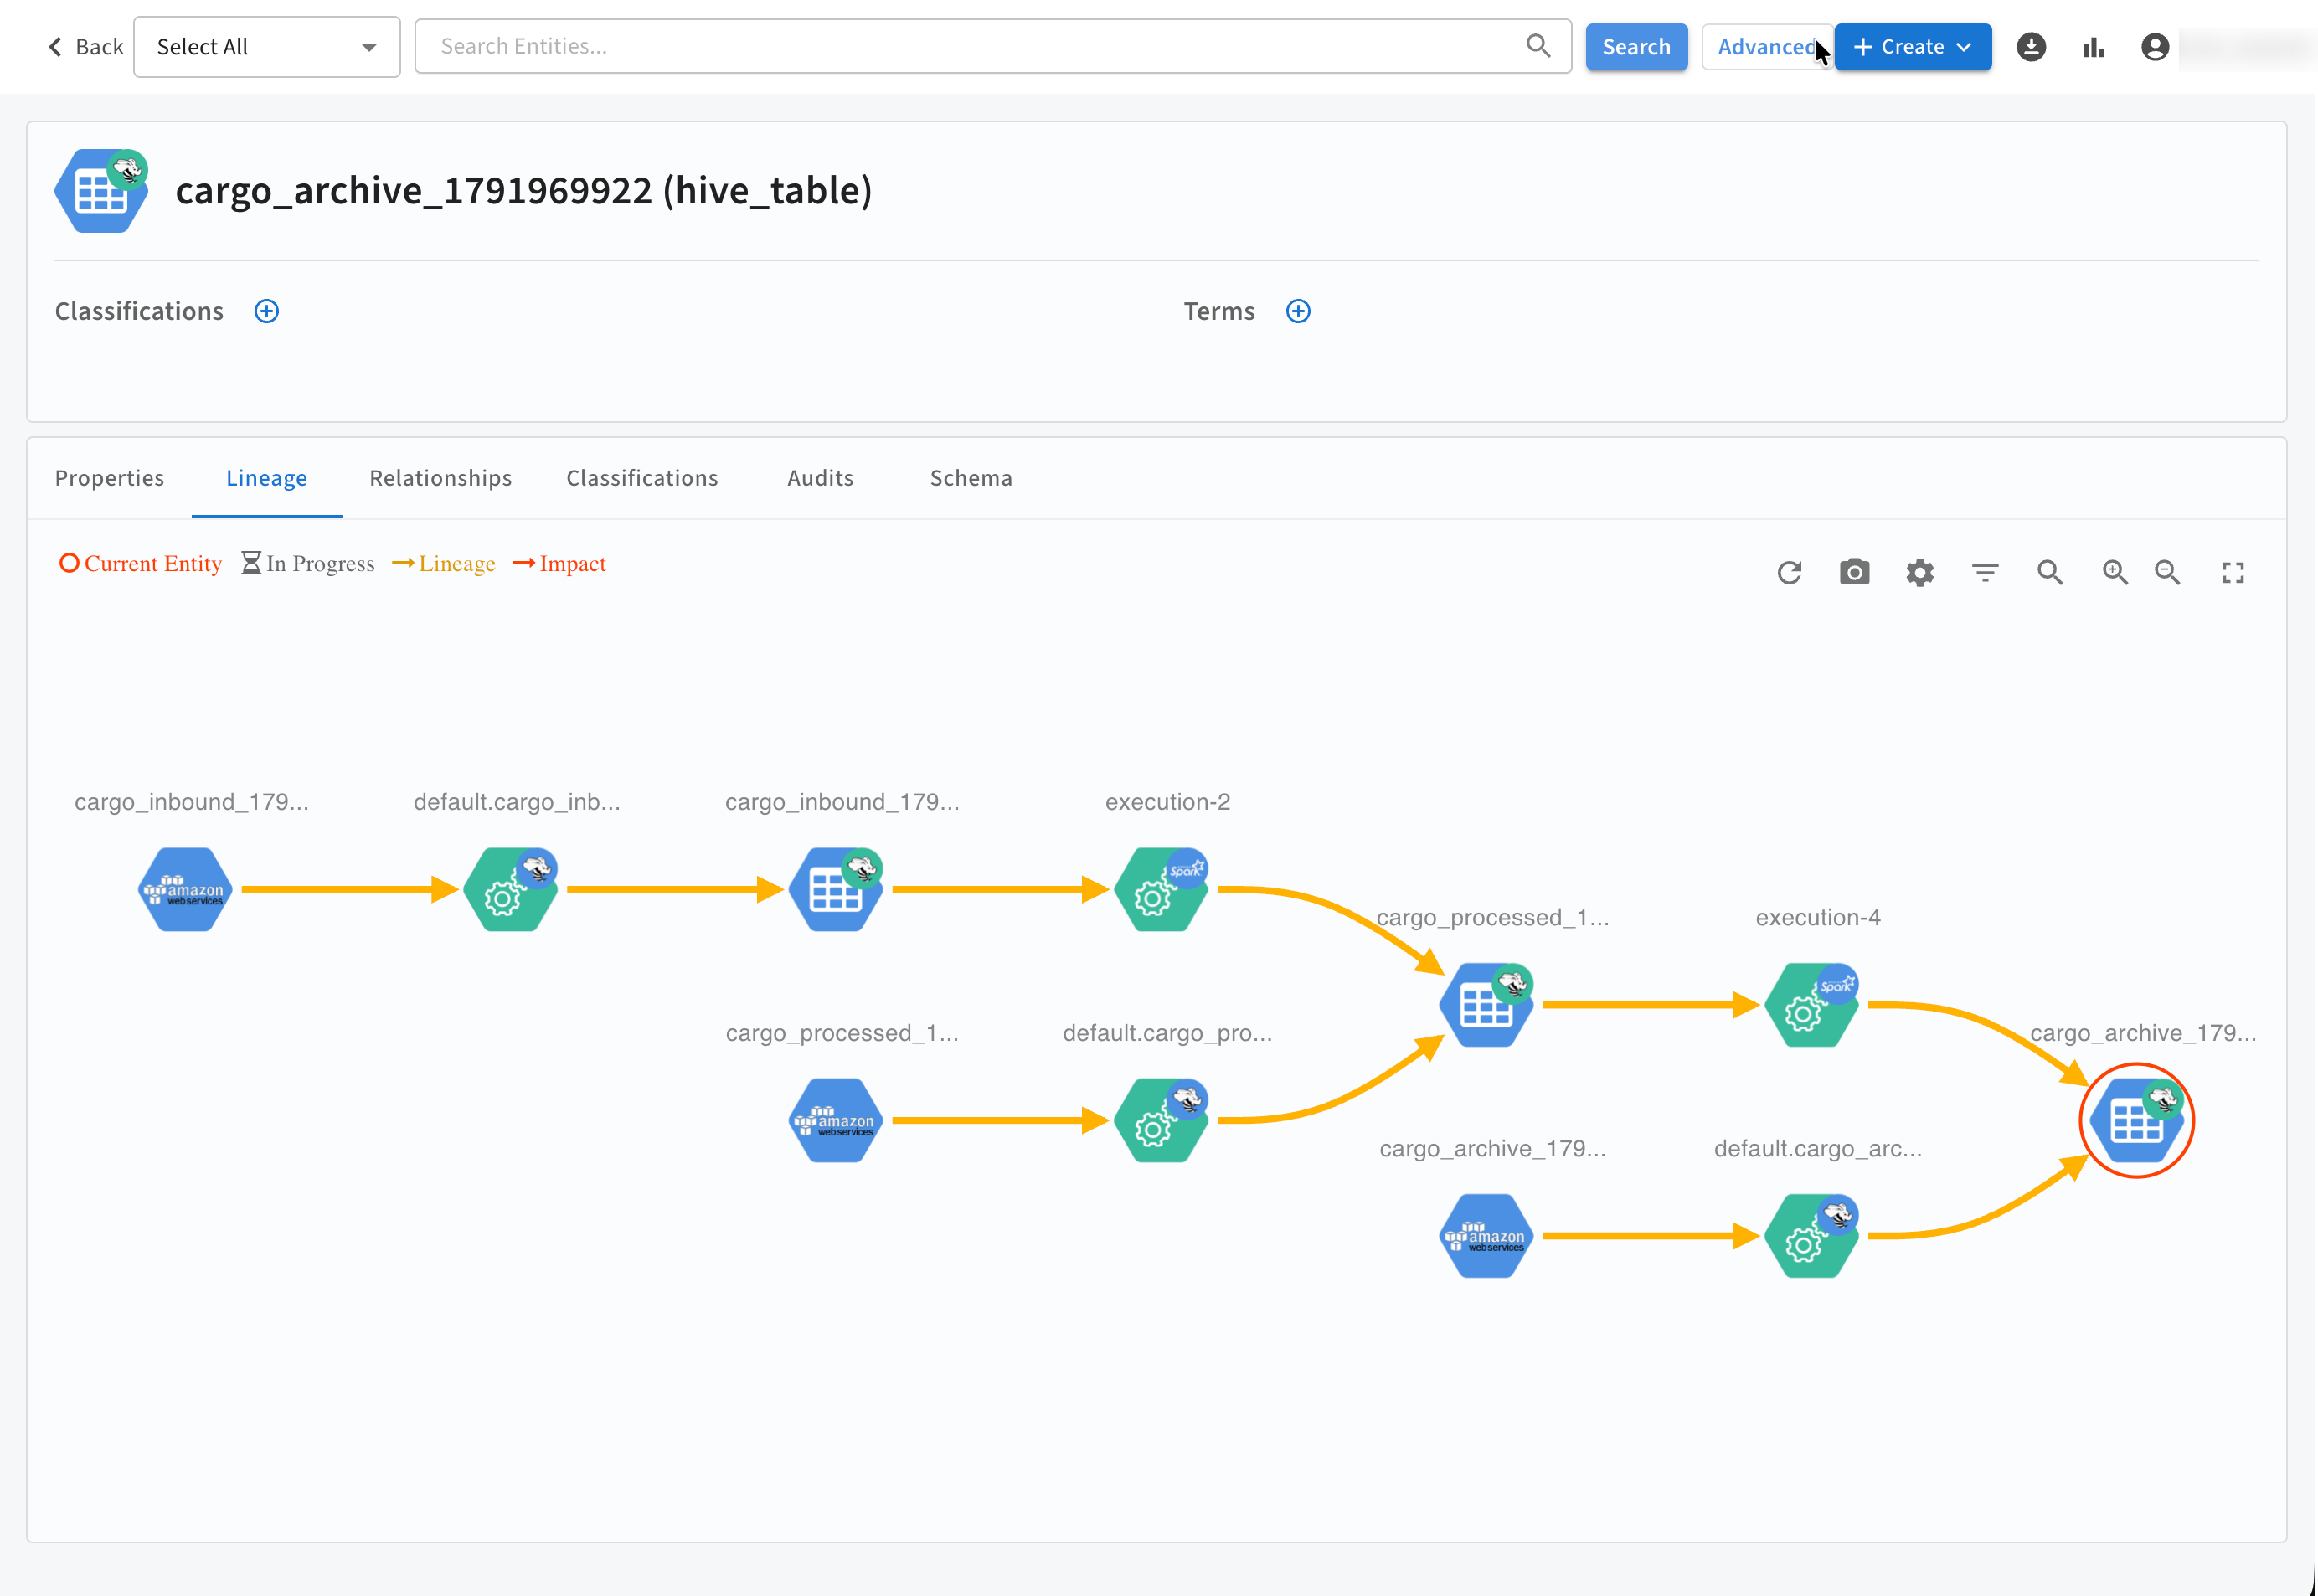
The Lineage tab of the cargo_archive
hive_table entity in the New User Interface. The
cargo_inbound table feeds the cargo_processed table
through the Spark process execution-2, and the
cargo_processed table feeds the cargo_archive table
through the Spark process execution-4. Each table is linked to its storage
directory through a Hive process.
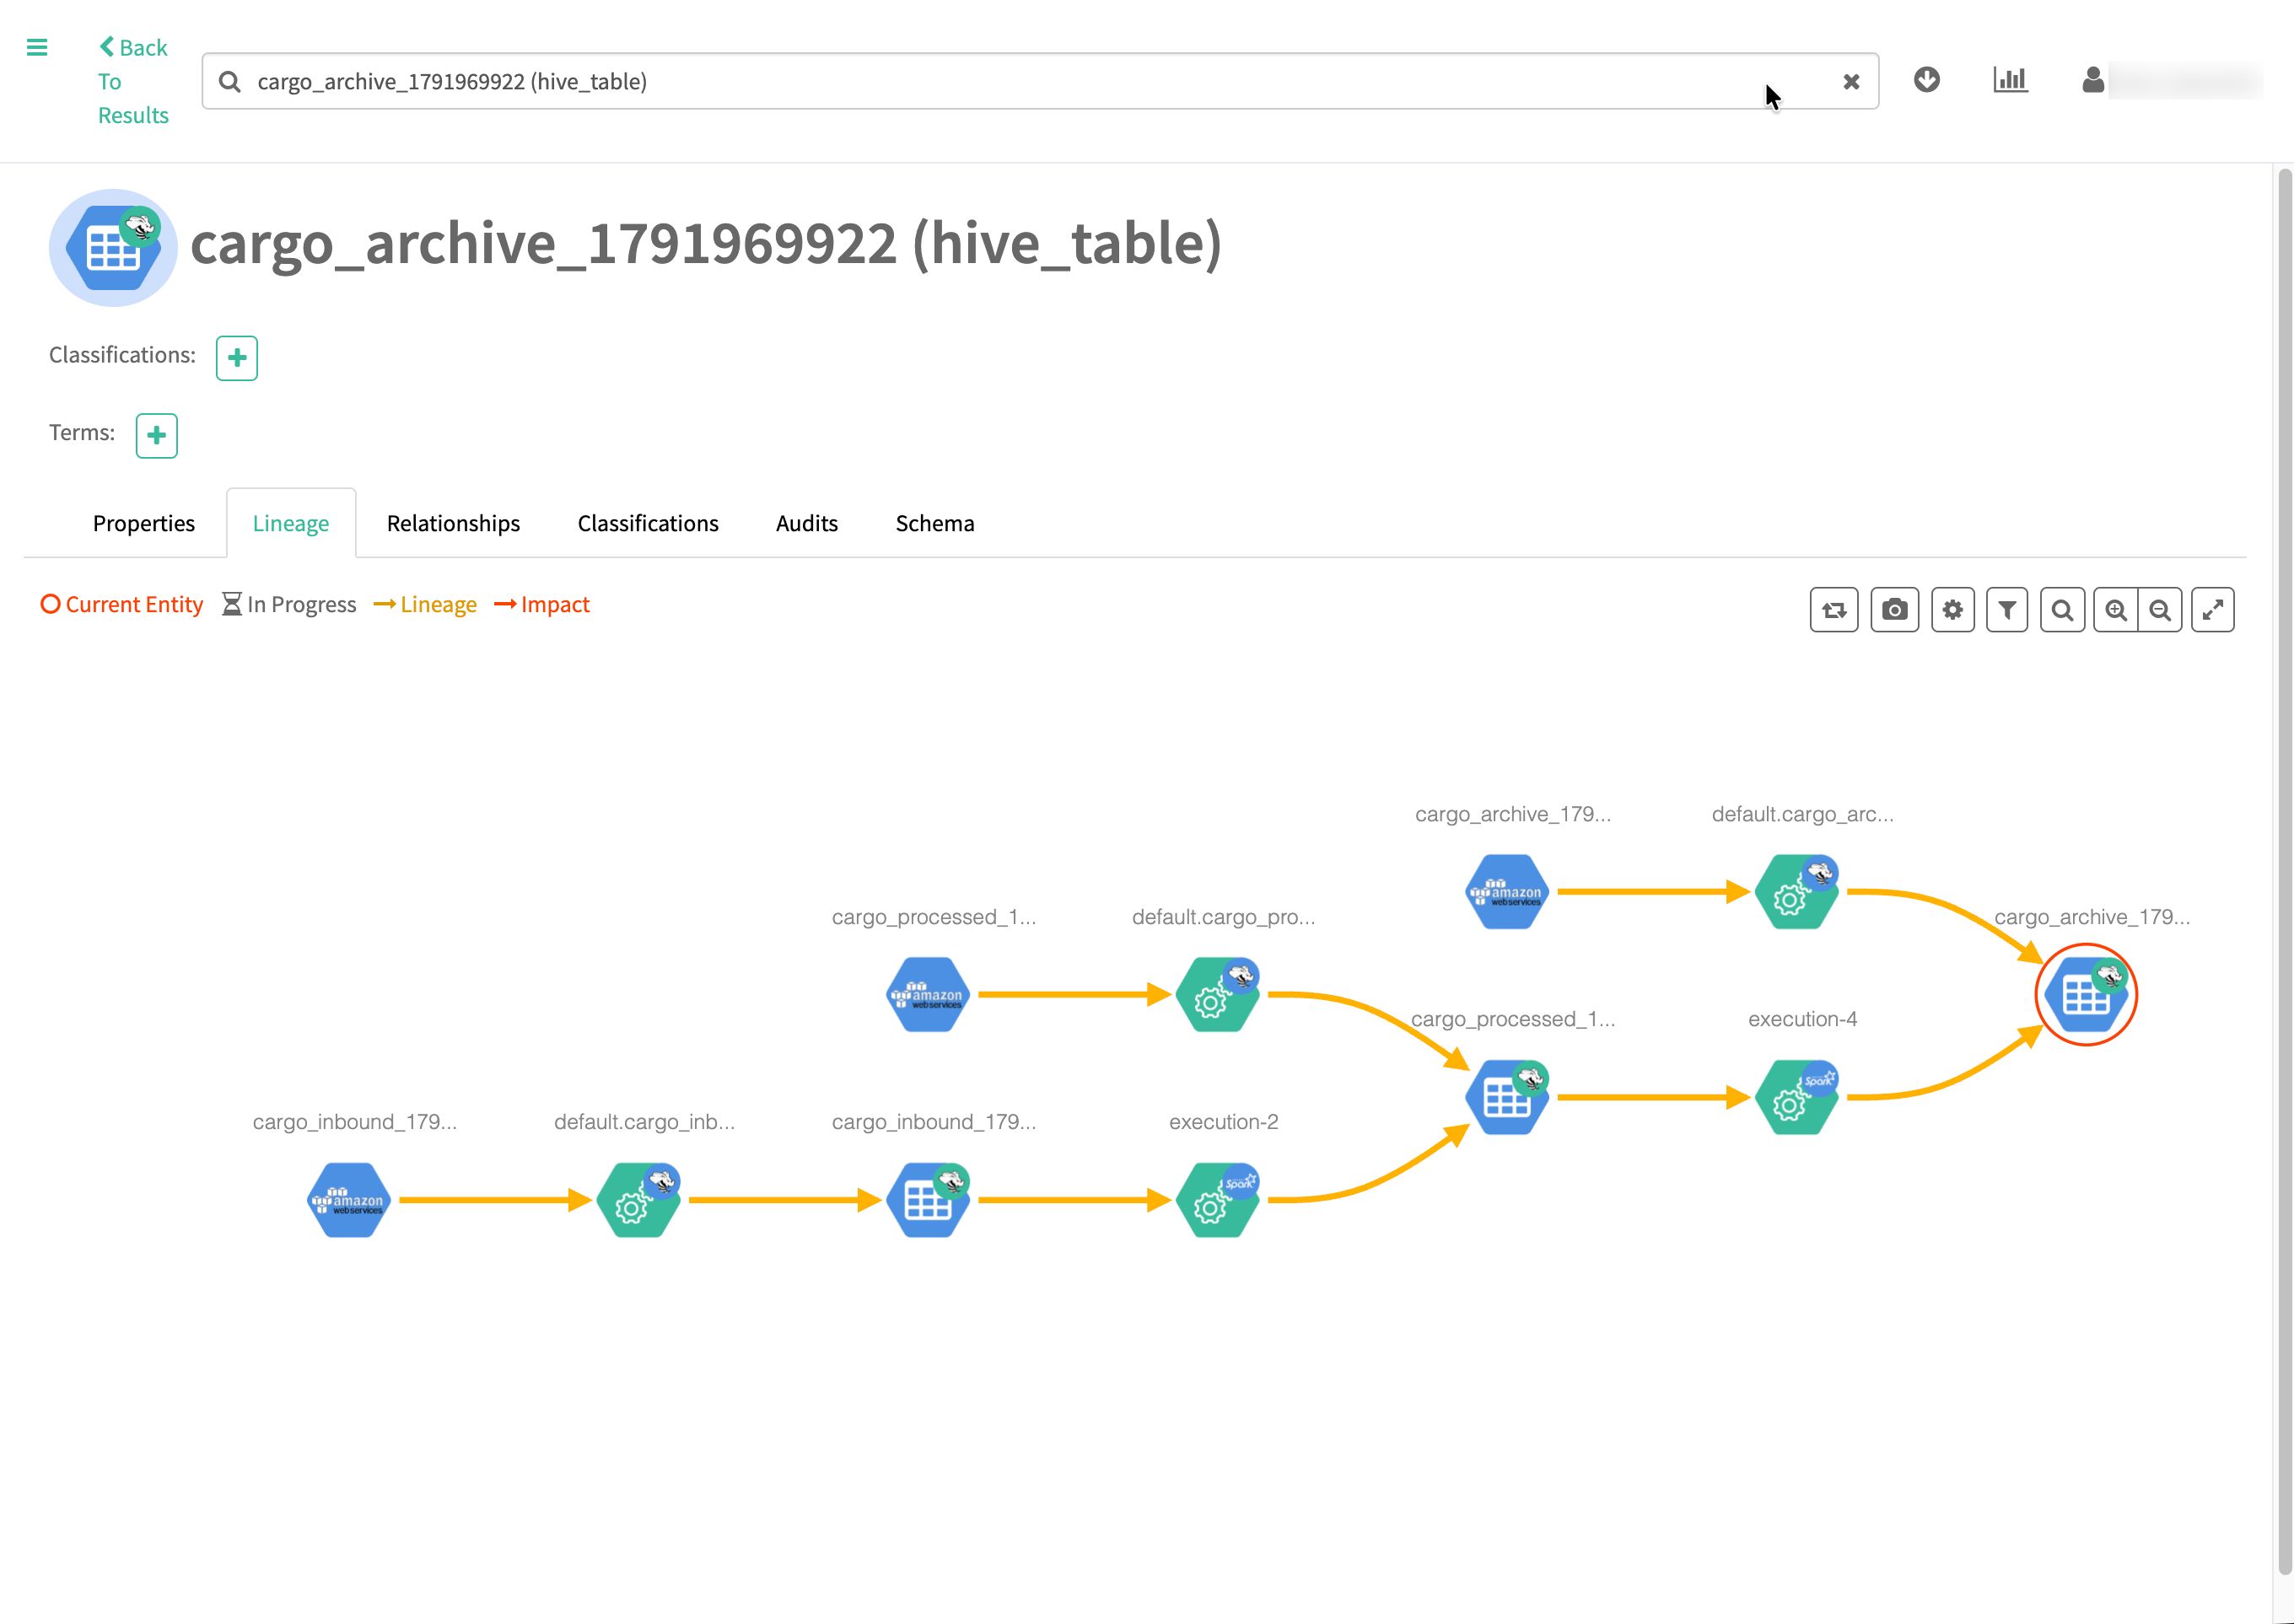
The Lineage tab of the cargo_archive
hive_table entity in the Classic User Interface. The
cargo_inbound table feeds the cargo_processed table
through the Spark process execution-2, and the
cargo_processed table feeds the cargo_archive table
through the Spark process execution-4. Each table is linked to its storage
directory through a Hive process.
The lineage graph can also contain Hive process nodes, for example
default.cargo_inbound_... in the figures. The Hive Metastore hook creates
these nodes to link
the storage location of a table to the table entity. They are not Spark
processes.
